Retrieval is the step that finds the useful pieces of your documents when a question arrives, so that an LLM can read them and answer. Two parts share the work: the retriever finds the pieces, and the reader reads them and writes the answer.
The need for it showed up in lesson 1. Putting one line of the queue log into the raised the probability of Thursday from 0.21 to 0.81, but we picked that line ourselves. Now picture a company with 2,000 documents of about 30 paragraphs each, so 2,000 × 30 = 60,000 paragraphs. The from lesson 1 had room for 7,000 tokens of passages. At 500 tokens a paragraph, only 7,000 ÷ 500 = 14 paragraphs fit.
So for every question, some program has to pick the 14 out of 60,000 that hold the answer. This lesson builds such a program in the simplest way: by counting words. Of the course's 3 questions, it handles the first well. On the second it ties a right passage with a wrong one, and on the third it returns nothing.
The ladder for this lesson
The ladder has 8 steps. The first 4 are the same as in the easy version, and steps 5 to 8 take you to the level of the Stanford slides. Under each step you can see what you will be able to do after it.
What you need first: Lesson 1 (token, prompt, context window, parameters, hallucination). This lesson explains everything else it uses. From step 5 on, a few terms from later lessons appear, such as TF-IDF and Exact Match, and this lesson explains them briefly where they come up. If you already know a step, skip to the next one. A word with a dotted underline and ▾ opens its definition when you click it.
1Corpus, document and passage: where the retriever looks
The set of all your documents is called the corpus, and the retriever searches inside it. Each single item in the corpus is a document: a web page, a file or an email. Another name for the corpus is the collection.
The retriever does not return a whole document, because the prompt has room for only 14 pieces, and most of a long document has nothing to do with the question. The milestone date in a 40-page syllabus probably takes 2 lines. So the retriever returns a small piece, such as one paragraph, and this piece is called a passage.
The question you are searching for is the query. This lesson's first query is the one from lesson 1: which office hour is least crowded.
Later lessons keep coming back to this small corpus. It has 6 documents, with one passage from each. Every passage also has a short ID, such as P3, so that an answer can name it. the syllabus, queue log, Homework 1 announcement and project page come from the slides, the office hours page and the old forum post are mine
ID
Passage
P1
Grading. The project milestone is due Week 6, Thursday 11:59pm. Late days may not be applied to the milestone. The final report is due Week 10.Syllabus
P2
Office hours: Tuesday 4pm in Room 104 and Thursday 9am on Zoom, run by the TAs.Office hours page
P3
Queue log, last 3 weeks: Tuesday 4pm office hour averaged 14 students waiting; Thursday 9am office hour averaged 3.Queue log
P4
Old forum post (2024): midweek afternoons are usually the least crowded time to visit.Old forum post
P5
Homework 1 will be released on Oct 5.Homework 1 announcement
P6
Project proposal due on Oct 9. Teams of 1-3 people are recommended.Project page
Think first
Suppose the syllabus and the Homework 1 announcement were two paragraphs of the same document. How many documents would there be, and how many passages?
Show the answer
5 documents, but still 6 passages, and the retriever chooses among those 6. The company has the same split: 2,000 documents, but 60,000 passages.
2Retrieval: putting the right passage into the prompt when a question arrives
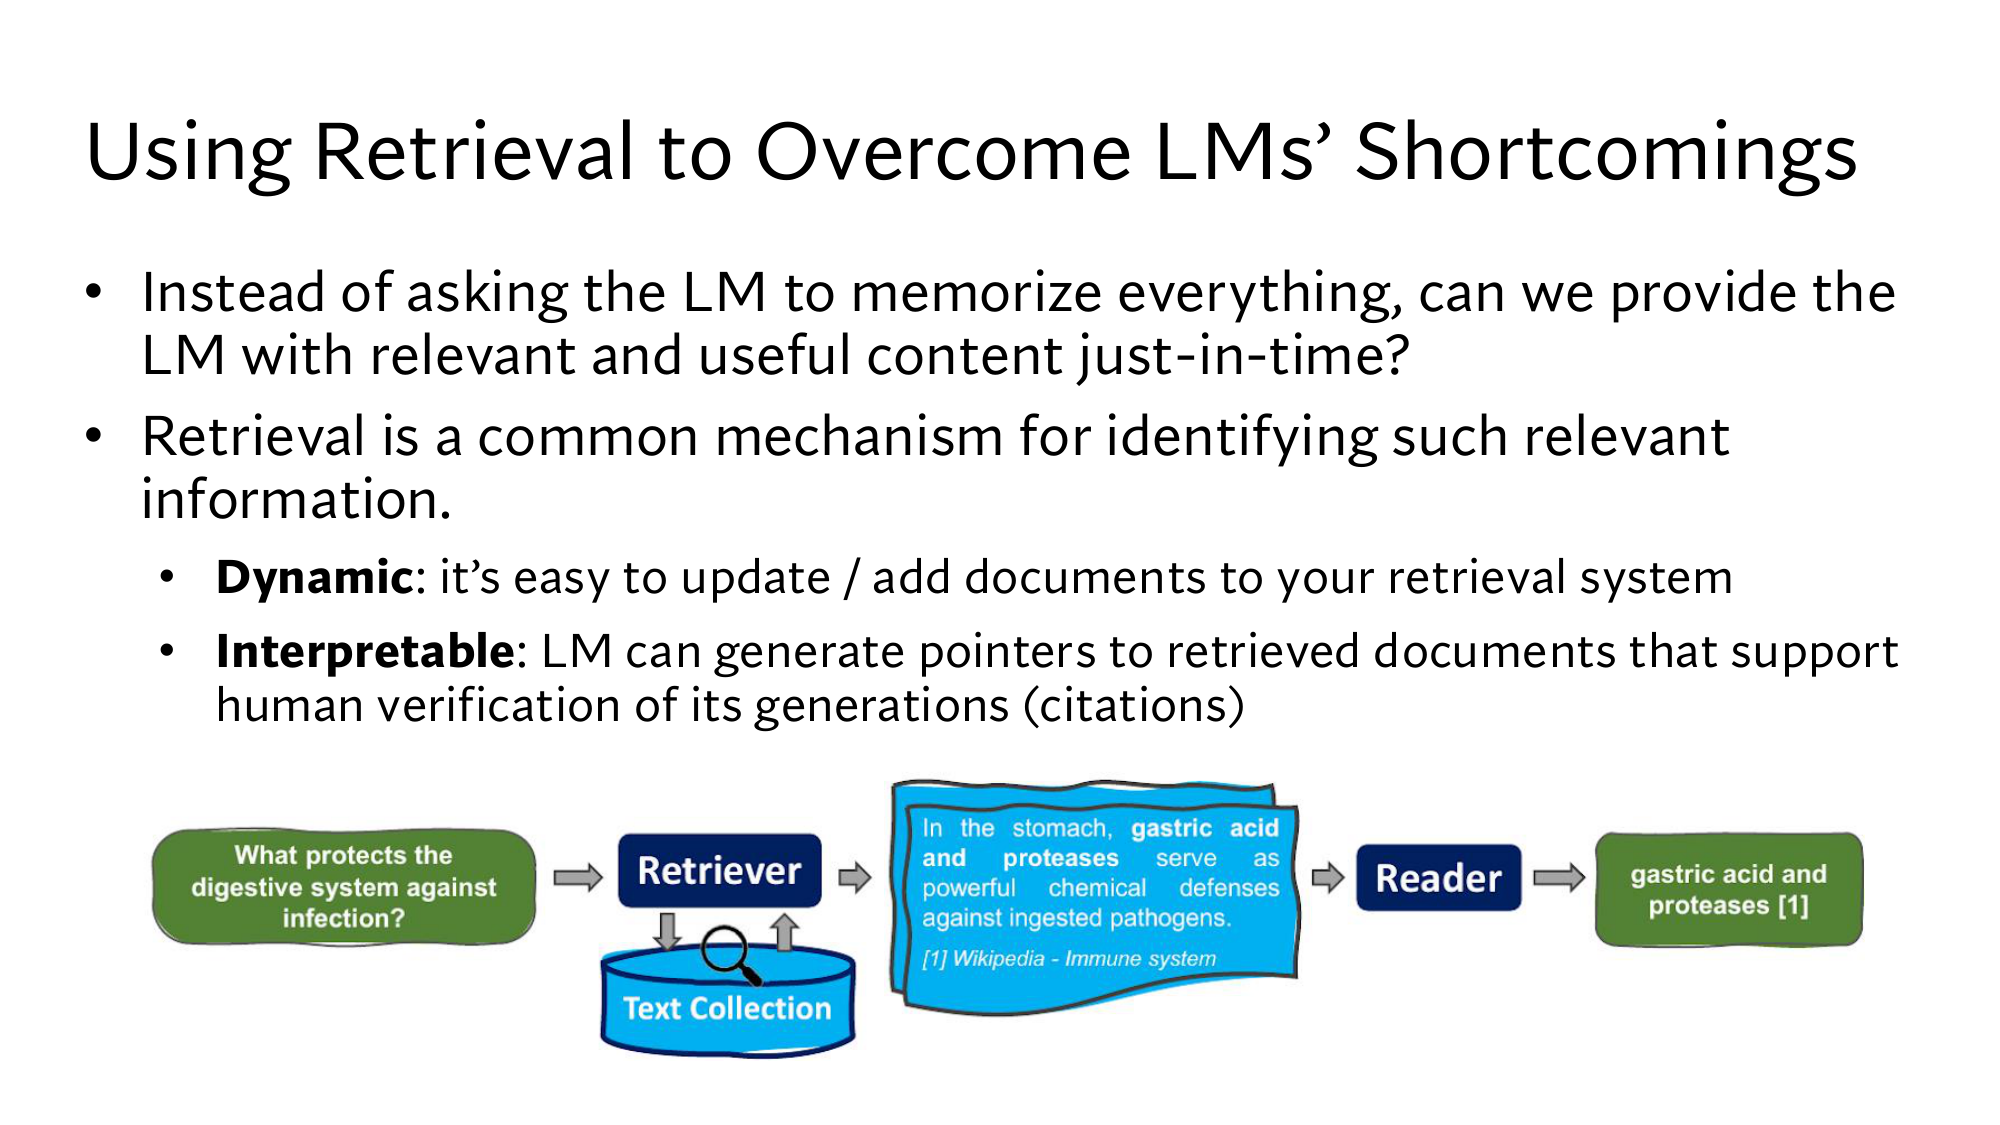
Retrieval means finding the most useful passages in the corpus when a query arrives, and putting them into the prompt with the question. The model then does not have to memorize everything in advance. Stanford's slide calls this just-in-time: the right text reaches the model exactly when the question does.
For our query the retriever finds the queue log, and the LLM gets a prompt like this: my example
Answer the question using the passage below. Cite the passage ID. [P3] Queue log, last 3 weeks: Tuesday 4pm office hour averaged 14 students waiting; Thursday 9am office hour averaged 3. Question: Which office hour is least crowded?
The answer comes back as Thursday 9am, about 3 students ahead of you [P3]. The [P3] at the end says which passage the claim came from. A source written next to an answer is called a citation. With the citation you can open the queue log and check that it really says this.
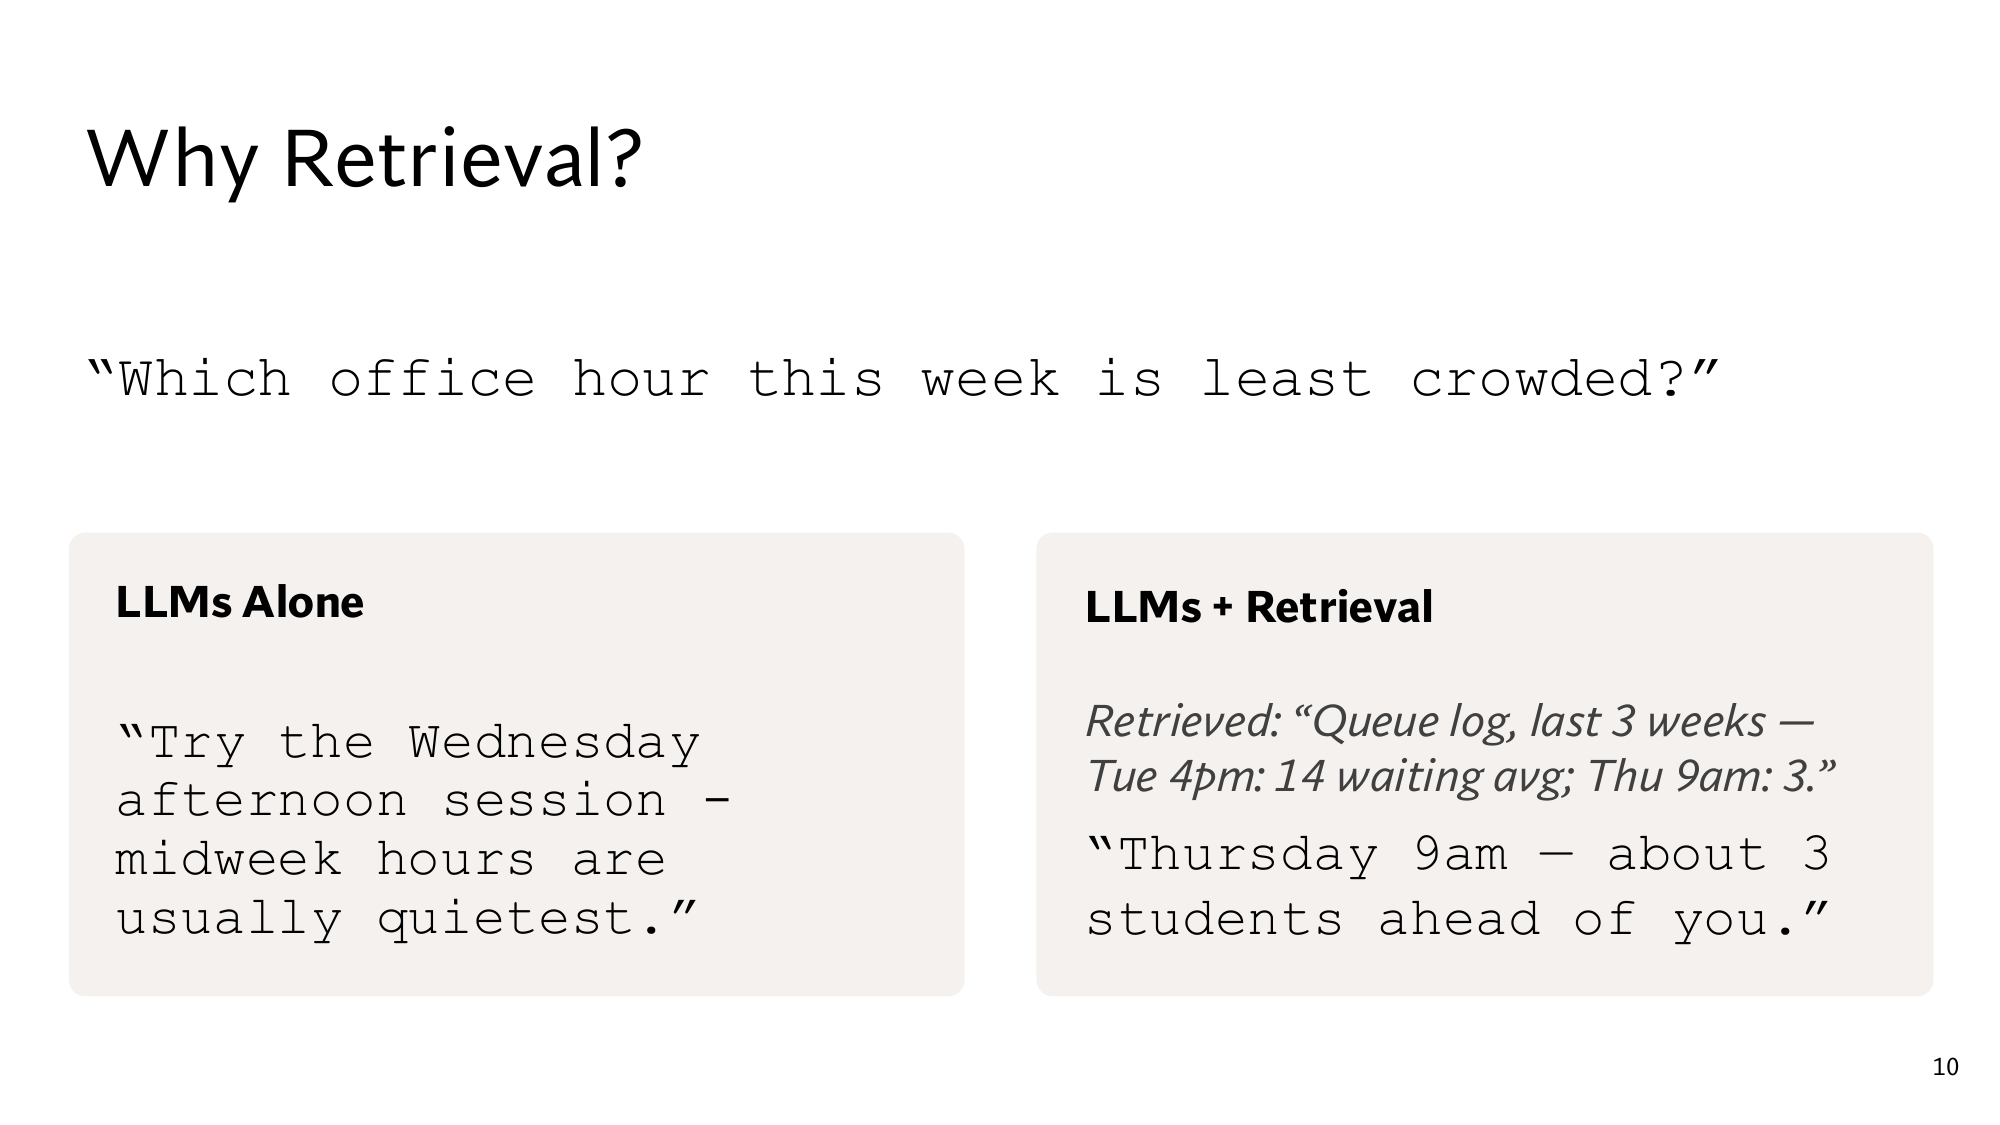
Stanford's Why Retrieval? slide. On the left is the LLM's guess on its own. On the right is the queue log the retriever returned, and the answer written from it. Click the image to open it at full size.
In lesson 1 all of the model's knowledge sat in its , which caused two problems. Adding a new fact needed training, and the model could not name its source. With retrieval you add a new fact by adding a passage to the corpus, and the citation shows the source. Stanford's slide calls these two benefits Dynamic and Interpretable.
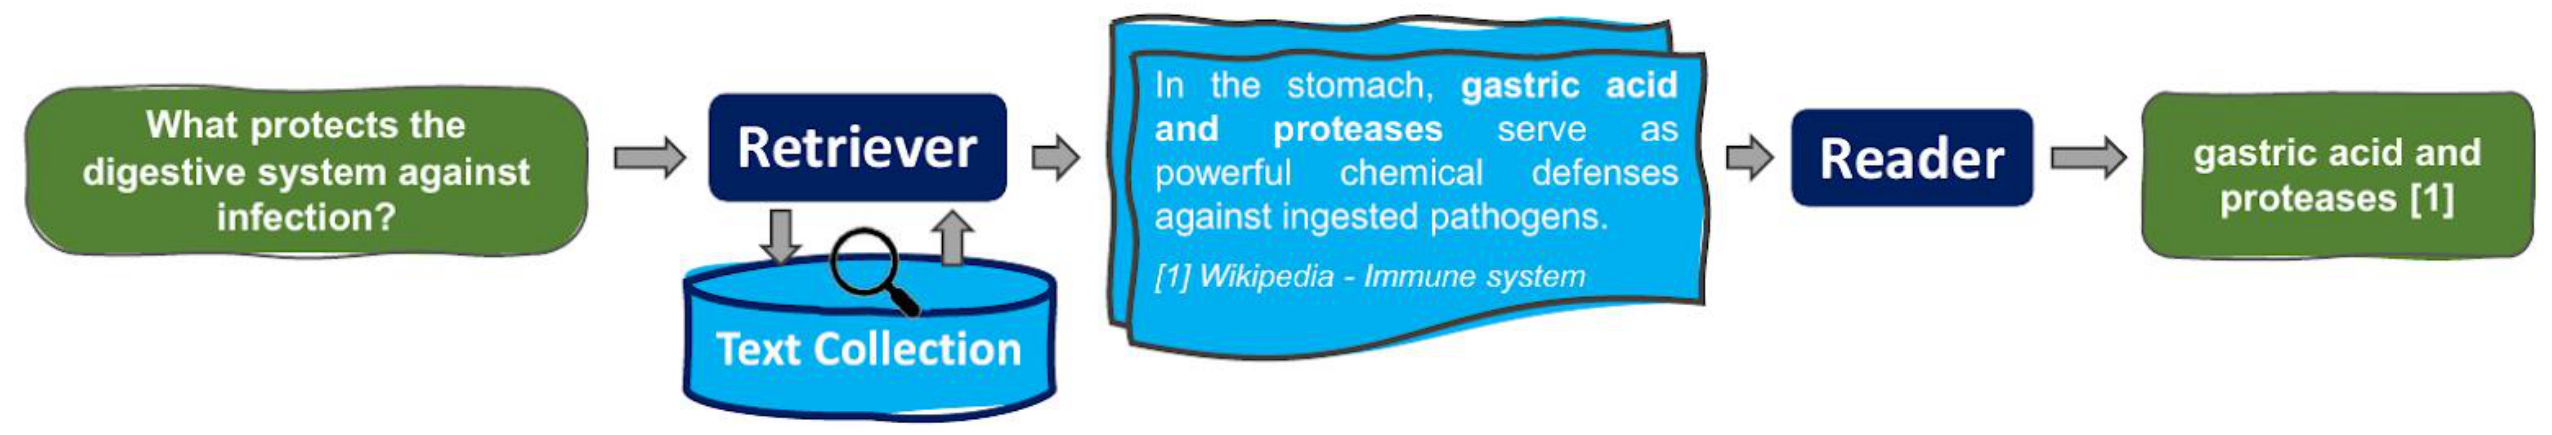
Stanford's slide: just-in-time, Dynamic and Interpretable. In the diagram at the bottom, the [1] in the reader's answer is a citation.
Lesson 1 called knowledge stored inside the parameters . Here the knowledge sits in the corpus, outside the model, and knowledge kept this way is called non-parametric memory.
Retrieval is only as good as the search, though. The end of lesson 1 showed that with the old forum post in the prompt, the model may write Wednesday again. So the next step builds a firm rule for searching.
3The retriever: score every passage, then take the top K
A retriever gives every passage a score for the query, sorts the passages by score, and returns the top K. A score is a number that says how useful a passage is for the query.
The K highest-scoring passages are called the top-K. K is fixed in advance, for example 2 or 100.
The simplest score is word overlap: how many of the query's words also appear in the passage. But words such as which, is and the appear in almost every text, so counting them tells you nothing.
Very common words like these are called stopwords, and the retriever removes them before counting. Remove which and is from the query which office hour is least crowded. Four words are left: office, hour, least and crowded.
Think first
The queue log holds the answer, and the old forum post holds only an opinion from 2024. Look for the four words in both passages in the corpus table. Which one gets the higher word-overlap score?
Show the answer
Neither. Both get 2. The queue log has office and hour, and the forum post has least and crowded.
Here are the scores for the whole corpus:
Passage
Words matched
Score
Queue log
office, hour
2
Old forum post
least, crowded
2
Office hours page
officeThe retriever matches words exactly, so hours and hour are different words to it.
1
Syllabus, Homework 1 announcement, project page
none
0
Word overlap only counts words, so it cannot see that the queue log is three weeks of data and the forum post a 2024 opinion. With K = 2 the retriever returns both. The prompt then carries the old opinion next to the real data, and the model may write Wednesday again because of it.
The part that reads the query and the top-K passages and writes the answer is called the reader. Today the reader is usually an LLM that was never trained for this particular task and simply follows the instruction in the prompt. The first line of the prompt above, Answer the question using the passage below, is that instruction.
Doing a task from an instruction alone, without training for it, is called zero-shot. Since the reader is usually such a ready-made LLM, lessons 3 to 15 mostly work on making the retriever better.
Run the retriever yourself
Pick a query and change K. The retriever does not return passages with score 0. When scores tie, the passage listed first in the corpus comes first.
Rank
Passage
Score
Work it out
Query: when is the project milestone due. Remove the stopwords and score the syllabus and the project page. With K = 1, which passage does the reader get? Check it in the widget.
Show the answer
The words left are project, milestone and due. The syllabus has all three, so its score is 3. The project page has project and due, so its score is 2. With K = 1 the reader gets the syllabus, which has the right date: Week 6, Thursday 11:59pm.
4The recall ceiling: a passage that never arrives is never read
Now pick the third query in the widget: when can I get help from a TA. After removing stopwords, help and ta are left. The answer is in the office hours page, but that page says TAs, not ta, and no passage contains help. So every score is 0 and the retriever returns nothing. However good the reader is, the office hours page never reaches its prompt.
How often a retriever finds the passage that is needed is, roughly, the retriever's recall. If the right passage reaches the top K for 60 out of 100 questions, the recall is 60%. 60% means 60 out of 100, that is 60 ÷ 100 = 0.6. Lesson 13 shows how to measure recall precisely.
Now add the reader: when it gets the right passage, it answers 90% of questions correctly, that is 0.9 per question. On the 60 questions that gives 60 × 0.9 = 54 correct answers. On the other 100 − 60 = 40 questions, no correct answer can come from the passages. You can now improve either the reader or the retriever. my example
Change
Arithmetic
Correct answers
As it is now
60 × 0.9
54
Make the reader perfect
60 × 1.0
60
Raise the retriever to 80, same reader
?
?
Work out the third row
The retriever now brings the right passage for 80 questions, and the reader is still right 90% of the time. How many correct answers do you get? More or fewer than with the perfect reader?
Show the answer
80 × 0.9 = 72, which is 72 − 60 = 12 more than the perfect reader. Even a perfect reader cannot go past 60, because for the other 40 questions the right passage never reached it.
The perfect reader stops at 60 because of a rule of multiplication. Multiply a number by something smaller than 1 and it shrinks, as in 60 × 0.5 = 30. Multiply it by 1 and it stays the same, as in 60 × 1.0 = 60. The reader's share can never be above 1, because 1 means every question answered correctly.
So the correct answers can never exceed the 60 questions for which the retriever brought the right passage. The retriever's recall becomes the upper limit of the whole system.
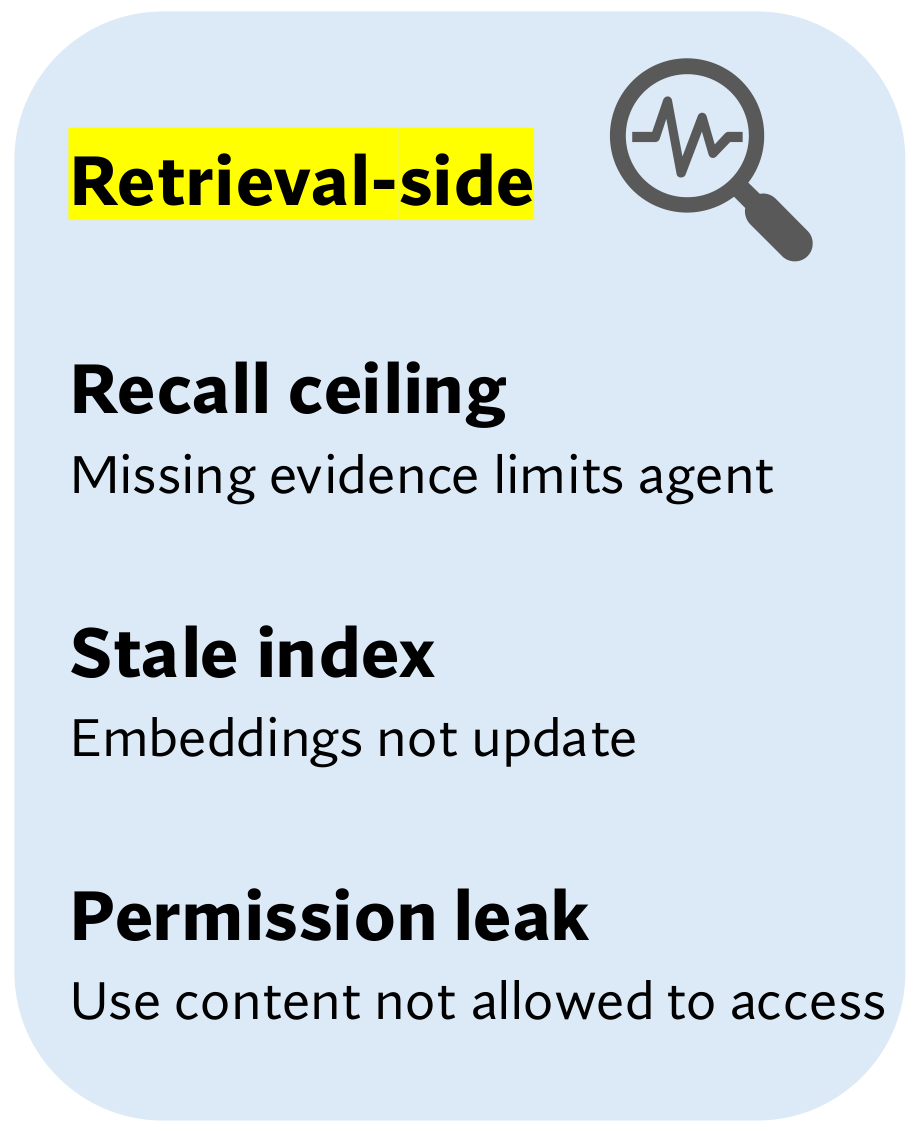
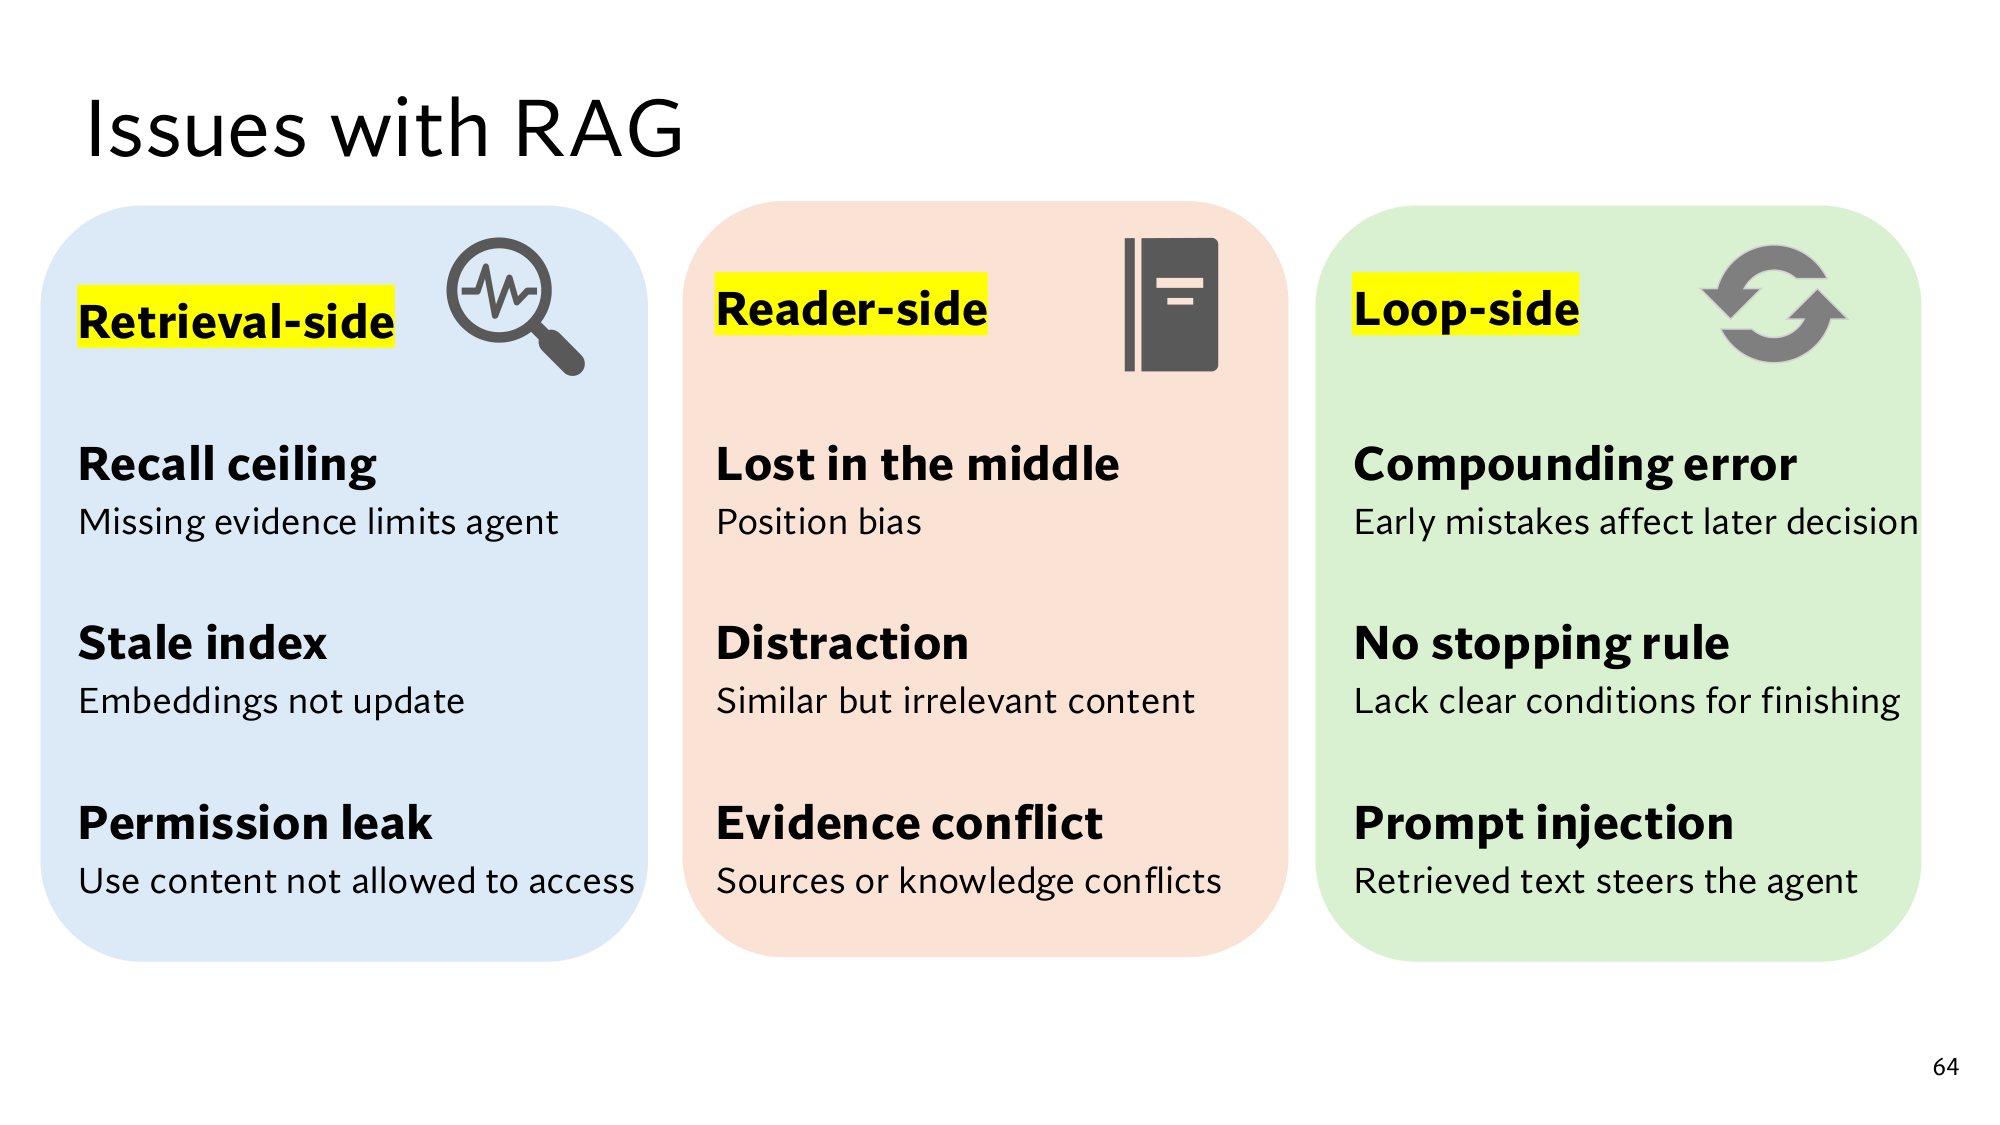
This limit is called the recall ceiling. Stanford's slide writes Missing evidence limits agent under it: evidence that never reaches the prompt holds the system back. Agents come in lesson 16.
The retrieval part of Stanford's slide Issues with RAG. The other two problems come in lesson 18.
A larger K raises recall, but wrong passages come along too, like the old forum post at K = 2. And the company's prompt cannot hold more than 14 passages anyway.
Word overlap failed twice, even on 6 passages. The first time it ranked a right and a wrong passage equally. The second time the query and the passage said the same thing in different words, help from a TA and run by the TAs, and the score was 0. Lesson 3 starts right here: turning text into numbers so that texts saying similar things get numbers close to each other.
From here: the Stanford level
The 4 steps above are the same as in the easy version. The 4 steps below take you to the level of the Stanford slides: the symbols on the retriever-reader slide and the maths of functions, then a real system called DrQA and its training data, then the recall ceiling in real numbers, and finally reading the slides yourself.
5Retriever and reader as functions: the slide's symbols
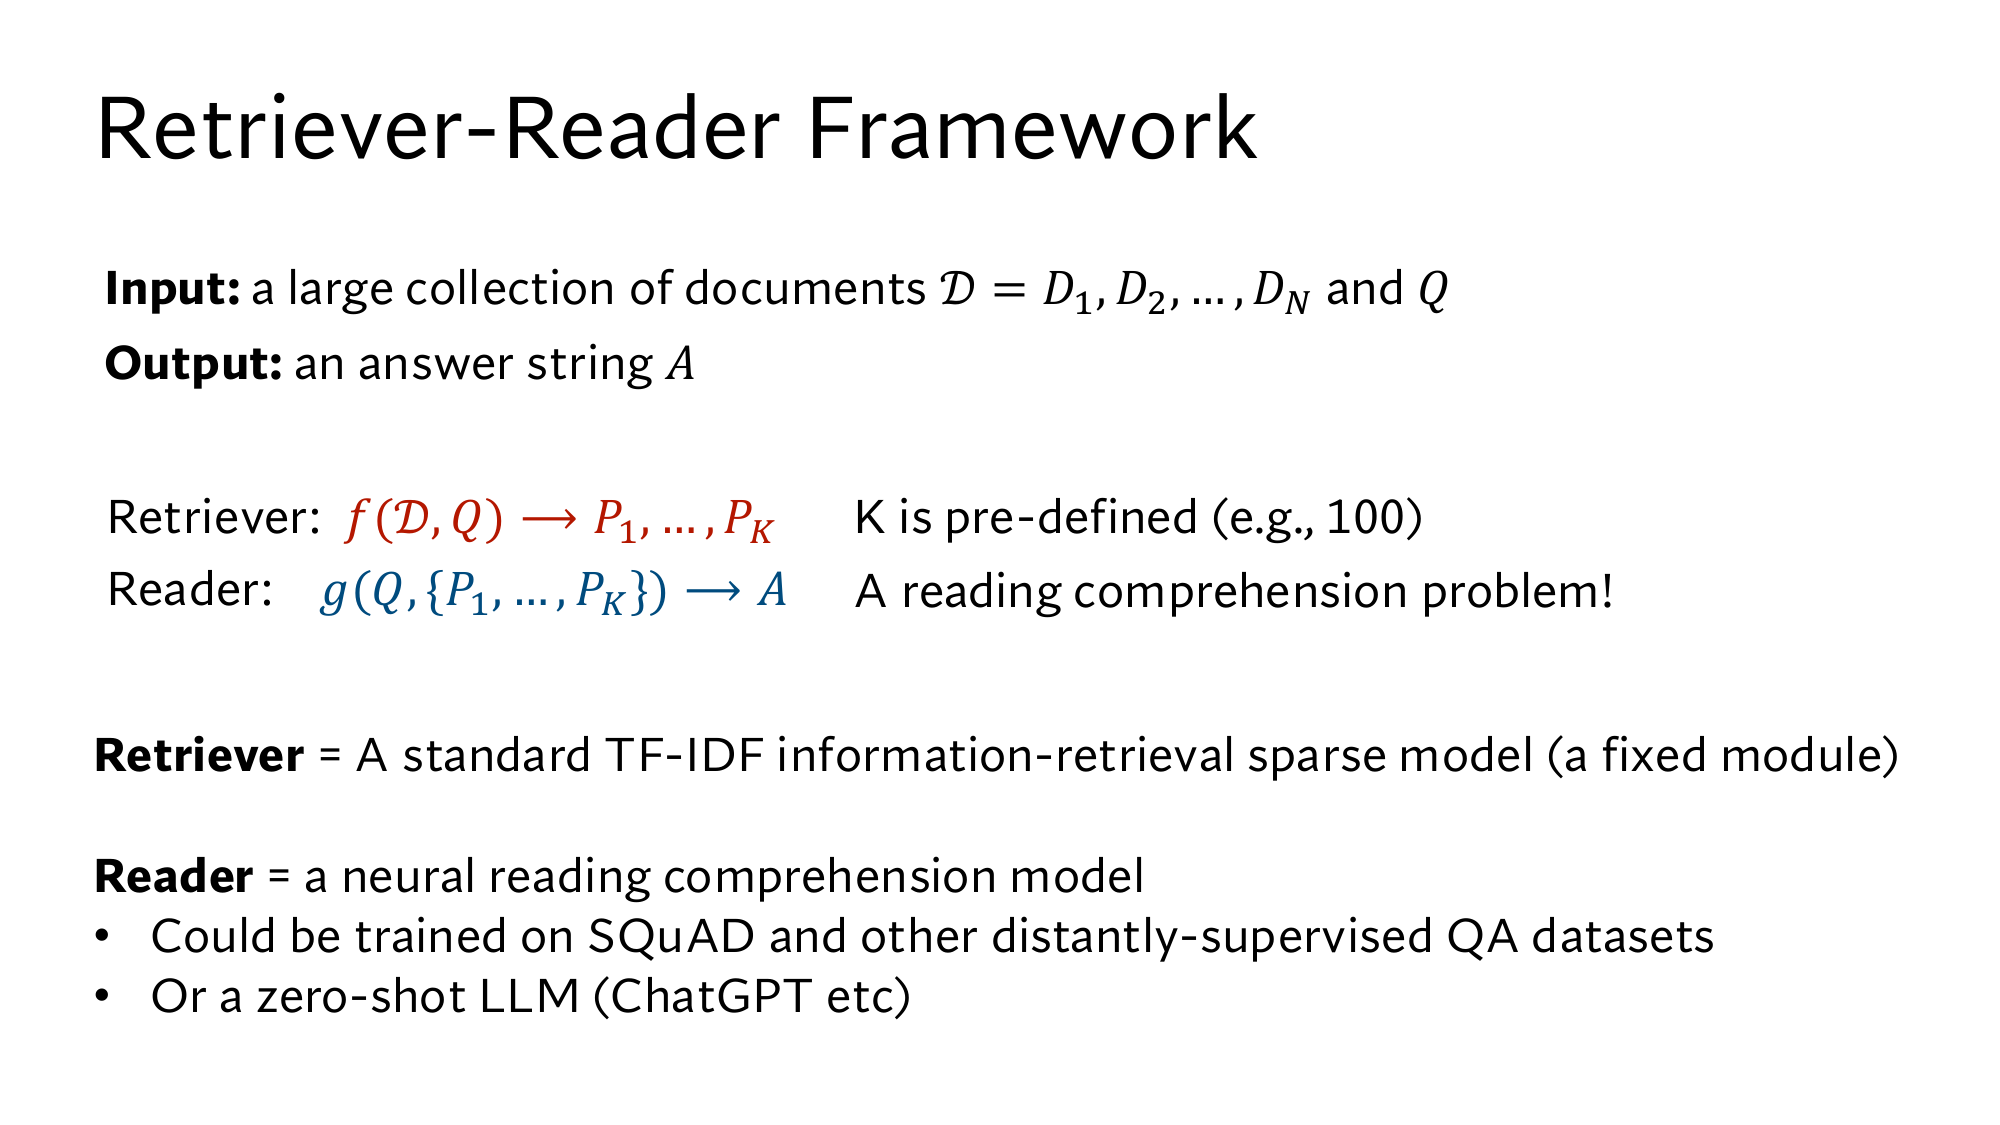
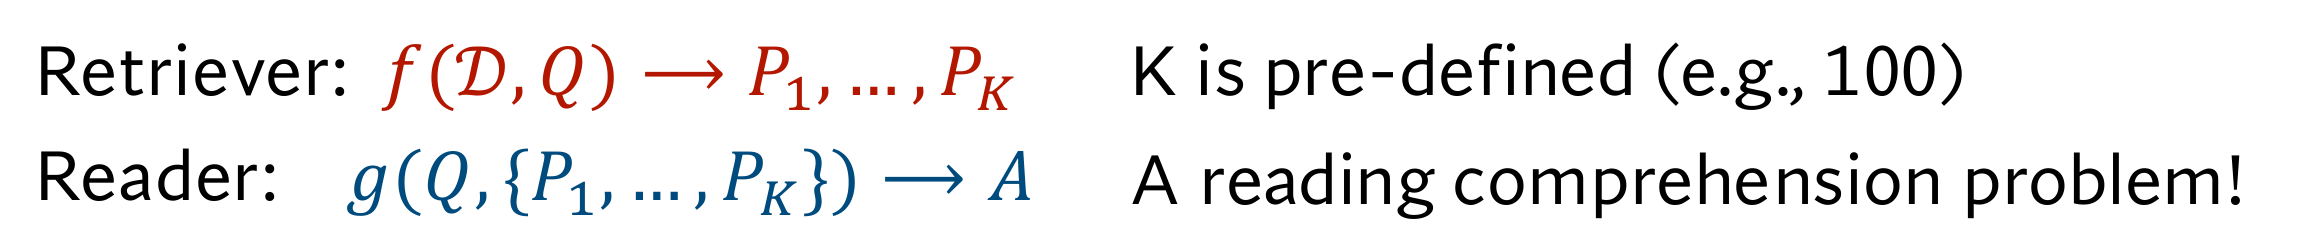
Stanford's slide writes the retriever and the reader as two functions: the retriever turns the corpus and the query into K passages, and the reader turns the query and those passages into an answer. To read it you first need what a function is.
A function is a rule that takes an input and gives an output. If the rule is “double it and add 1”, you write it as f(x) = 2x + 1. Here f is the name of the rule and x is the input, so f(3) = 2 × 3 + 1 = 7. A function in code does the same thing: it takes arguments and returns a value.
A function can also take more than one input. In f(x, y) = x + 2y, f(1, 3) = 1 + 2 × 3 = 7. Both lines on the slide are functions with two inputs, and “⟶” means “gives as output”:
Retrieverf(𝒟, Q) ⟶ P1, …, PK
Readerg(Q, {P1, …, PK}) ⟶ A
The table ties each symbol to our example:
Symbol
Meaning
In our example
𝒟 = D1, D2, …, DN
The whole corpus, a list of documents. The small number below says which document in the list it is, and “…” means “and so on up to”.
D1 = syllabus up to D6 = project page
N
The number of documents in the corpus
62,000 at the company
Q
The query
which office hour is least crowded
f
The retriever's rule
word overlap, then top-K
K
How many passages to return. The slide says K is fixed in advance, for example 100.
2
P1, …, PK
The K passages the retriever returns, in order of score
P1 = queue log, P2 = old forum post
{ … }
Curly brackets make a group of things, called a .
{queue log, old forum post}
g
The reader's rule
the zero-shot LLM from step 3
A
The answer, which the slide calls an answer string, meaning a piece of text
Thursday 9am, about 3 students ahead of you
The input has documents (D) and the output has passages (P), because, as step 1 said, a retriever returns pieces of documents. On our query the two functions run in three steps:
f(𝒟, Q): the retriever scores every passage. In corpus order the scores are 0, 1, 2, 2, 0, 0.
With K = 2 the top two passages come back: P1 = queue log and P2 = old forum post. Both score 2, so corpus order decided here.
g(Q, {queue log, old forum post}): the reader reads both passages and writes A. The set holds two passages that contradict each other, so A may say Thursday 9am or Wednesday.
Think first
For the query when is the project milestone due and K = 2, what does f(𝒟, Q) return? With K = 1, what is the input to g?
Show the answer
With K = 2, f returns P1 = syllabus (score 3) and P2 = project page (score 2). With K = 1 the reader gets g(Q, {syllabus}), and A = Week 6, Thursday 11:59pm.
A reading comprehension problem: the reader's job
A reading comprehension problem! is what the slide writes next to the reader line. Reading comprehension means answering a question about a text you are given. After the retriever has run, that is exactly the reader's job, because the passages are already in its hands.
The best-known dataset for this task is SQuAD, the Stanford Question Answering Dataset. Its makers showed people a Wikipedia paragraph, and the people wrote questions about that paragraph. The answer is always a piece of the same paragraph, and such a piece is called a span. The training part has 87,599 questions. from the paper One example:
Paragraph: … At the beginning of the 17th century the empire contained 32 provinces and numerous vassal states. … Q: How many provinces did the Ottoman empire contain in the 17th century? A: 32
The rest of the slide: a fixed retriever, and two kinds of reader
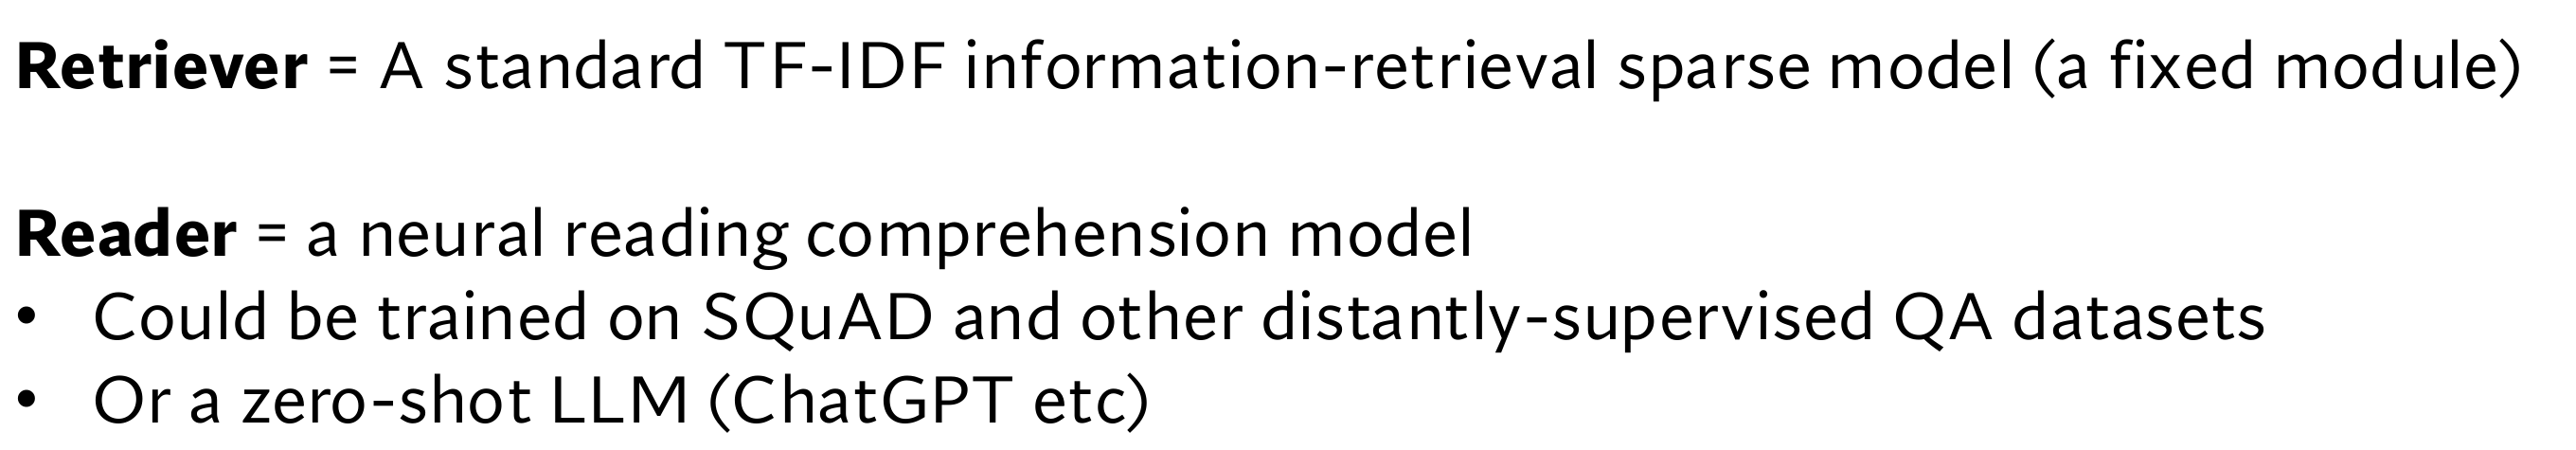
The slide has two more lines at the bottom. The first is about the retriever: A standard TF-IDF information-retrieval sparse model (a fixed module). It has three parts:
matches words like word overlap does, but it does not count every word equally. A word that appears in few documents gets more weight. Least appears only in the forum post and office appears in two passages, so least weighs more than office. Lesson 11 has the full arithmetic.
means a passage is seen as a long list with one number for every word in the vocabulary, and most of those numbers are 0. Our 6 passages have 69 different words, and the old forum post has 14 of them. So its list has 0 in 69 − 14 = 55 places.
A fixed module is not trained. Its rule is written in advance and does not change with data. Our word overlap is fixed too: for the same query the scores always come out the same. The DPR retriever in lesson 12 is the opposite, a retriever that is trained.
The second line is about the reader: a neural reading comprehension model. A neural model is a model with parameters that learns from examples, like the LLM in lesson 1. The slide gives two routes for such a reader:
Could be trained on SQuAD and other distantly-supervised QA datasets: train the reader on data such as SQuAD. Distantly supervised data comes in step 6.
Or a zero-shot LLM (ChatGPT etc): the reader from step 3, which writes the answer from an instruction without being trained for this task.
6DrQA: a retriever and a reader over all of Wikipedia
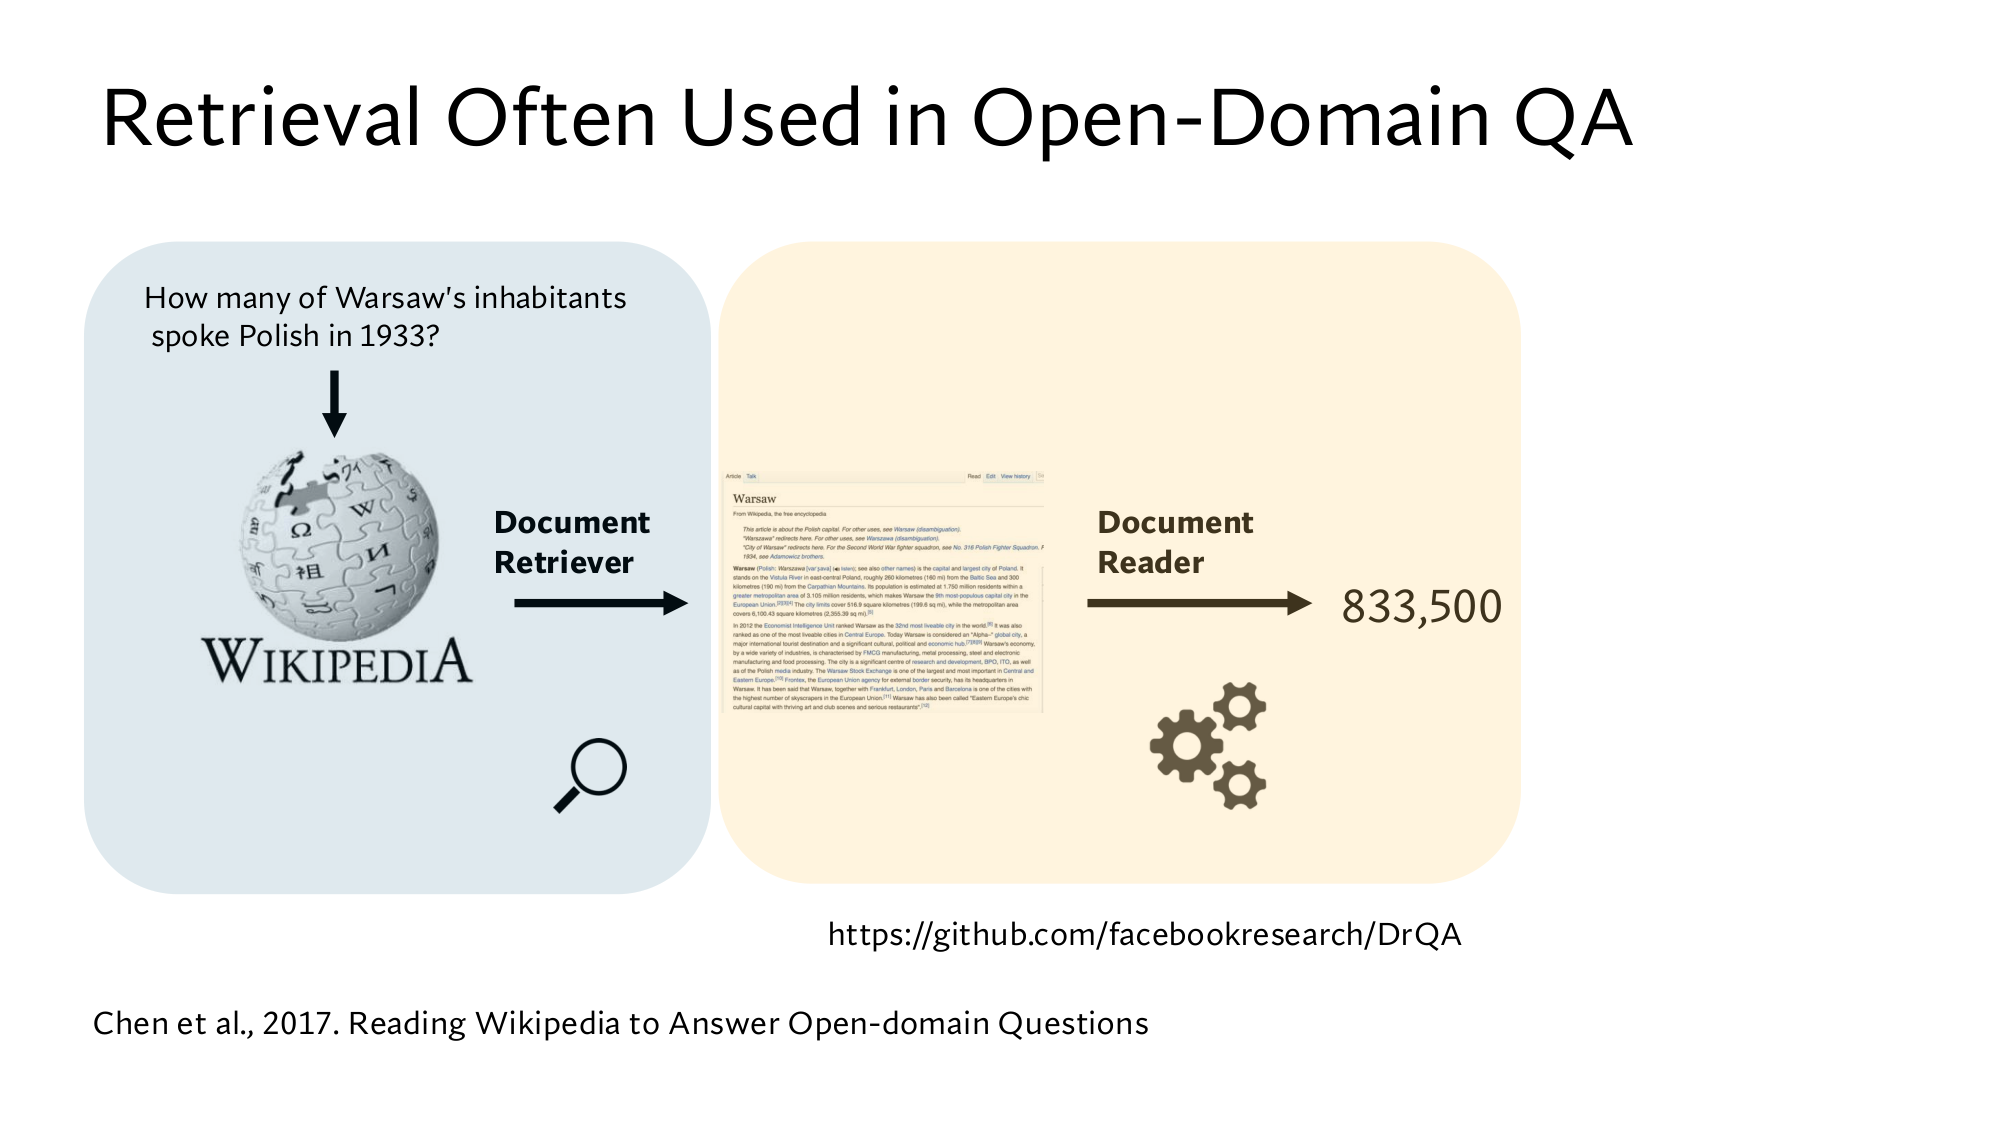
DrQA is a 2017 system that answers a question by searching all of English Wikipedia. Danqi Chen and colleagues built it at Facebook AI Research. from the paper Stanford's slide shows it as an example of the retriever-reader design. The slide's question is How many of Warsaw's inhabitants spoke Polish in 1933?, and the answer is 833,500.
Here the question can be about any topic, and the system is not handed the right paragraph. Question answering like this is called open-domain QA. In SQuAD-style reading comprehension the paragraph comes with the question. In open-domain QA the system has to find it in the whole corpus itself.
DrQA's retriever
DrQA's corpus is English Wikipedia from 21 December 2016. After some pages such as lists were removed, 5,075,182 articles were left, so N = 5,075,182. The retriever is not trained, and the paper itself calls it non-machine learning. It treats the question and every article as lists of TF-IDF word weights and scores every article from these lists. It returns 5 articles per question, so K = 5. from the paper
Besides single words, this retriever also matches pairs of words that appear side by side. Two adjacent words are called a bigram. The bigrams of our query are which office, office hour, hour is, is least and least crowded.
These articles hold 9,008,962 different words, and far more different bigrams. So DrQA uses a hash function to give each bigram the number of one of 224 buckets. A hash function is a fixed rule that turns any text into a number within a fixed range. 224 means 2 multiplied by itself 24 times, which is 16,777,216 buckets. from the paper
Think first
On our corpus, count the query's bigrams instead of its words. Does the tie between the queue log and the old forum post break?
Show the answer
No. The queue log has office hour and the forum post has least crowded, so each matches 1 bigram. The other 4 passages share no bigram with the query. Making bigrams after removing stopwords (office hour, hour least, least crowded) gives the same result. my arithmetic
The paper measured for what percentage of questions the answer text appears in at least one of the 5 articles the retriever returns. Wikipedia's own search engine was the comparison: from the paper
Dataset
Wikipedia search
DrQA, words only
DrQA, words + bigrams
SQuAD
62.7
76.1
77.8
CuratedTREC2,180 questions from the TREC competitions
81.0
85.2
86.0
WebQuestionsquestions taken from Google Suggest
73.7
75.5
74.4
WikiMoviesquestions about films
61.7
54.4
70.3
On SQuAD, DrQA's retriever beats Wikipedia search by 77.8 − 62.7 = 15.1 points.
Bigrams helped on three datasets, most on WikiMovies, from 54.4 to 70.3. On WebQuestions they cost a little, from 75.5 to 74.4.
The paper also tried BM25 and a retriever based on word embeddings, and both did worse. from the paper
DrQA's reader
DrQA's reader is a neural network trained on SQuAD. It gives every token of a paragraph two probabilities: that the answer starts here, and that the answer ends here. It then picks the piece whose start and end probabilities have the largest product, with no more than 15 tokens between start and end. from the paper
So DrQA's reader does not make up an answer: it picks a span from the text it was given. Step 7 needs this fact for the ceiling. On SQuAD questions that were not used in training, with the right paragraph given, this reader's is 69.5%. Exact Match counts an answer as correct only if it matches the right answer exactly. from the paper
Distant supervision: training data without paragraph labels
Distant supervision means building training examples for data that has only questions and answers, by finding the right paragraph automatically. SQuAD gives every question its paragraph, but CuratedTREC, WebQuestions and WikiMovies give only question-answer pairs. The reader has to learn to pick a span from a paragraph, so it needs paragraphs. This is what the slide means by distantly-supervised QA datasets.
Take one pair on our corpus: the question when is the project milestone due and the answer Week 6, Thursday 11:59pm. No passage carries a label. my example
Run the retriever on the question: the syllabus gets 3, the project page 2, and the other four get 0.
Of the returned passages, drop those that do not contain the answer text exactly. The project page does not contain Week 6, Thursday 11:59pm, so it goes.
The syllabus that is left becomes a training example: the question, the syllabus, and the answer span inside it.
DrQA did this at scale and added a few filters. For each question it took the retriever's top 5 articles and dropped paragraphs without an exact match of the answer. It also dropped paragraphs shorter than 25 or longer than 1,500 characters. If the question contained a name, such as Chadwick, paragraphs without that name were dropped too. It then counted the question's words and bigrams in a 20-token window around the answer and kept at most 5 paragraphs. from the paper
No person labelled the paragraph. The label came automatically from the answer text, which is why this is called distant, meaning indirect, supervision. An answer string can also appear in a paragraph by coincidence, so such a label is sometimes wrong. my caution
7The recall ceiling in real numbers, and the full arithmetic of K
DrQA shows the recall ceiling clearly, because its reader can only pick a span from the text it was given. If the answer text is not in the 5 articles at all, the reader cannot produce it in any way. The retriever brings an article with the answer for 77.8% of SQuAD questions, so the whole system can be right on at most 77.8% of them. numbers from the paper, the ceiling arithmetic is mine
The paper measured the reader in several situations. On the SQuAD questions the results are: from the paper
What the reader got
Exact Match (%)
Only the right paragraph, as in SQuAD
69.5
The whole right article
49.4
The retriever's 5 articles, from all of Wikipedia29.8 with a reader trained on SQuAD and the distantly supervised data together
27.1
The ceiling, the percentage of questions for which the retriever brought an article with the answer: 77.8.
Now apply the multiplication from step 4. If the reader were as good with 5 articles as with one right paragraph, the correct answers would be 0.695 of the 77.8%. my arithmetic
Turn both percentages into shares: 77.8% = 0.778 and 69.5% = 0.695.
Multiply: 0.778 × 0.695 = 0.541, which is 54.1%.
Compare with the real result: 54.1 ÷ 27.1 = 2.0, so the real result is half of this estimate.
The paper gives two reasons for the drop. First, the reader has to read 5 whole articles instead of one paragraph, and many sentences on the same topic look like answers. That is why even the right article brings the number down from 69.5 to 49.4. Second, people wrote the SQuAD questions while looking at one specific paragraph, so without that paragraph many questions read as incomplete. from the paper
So the recall ceiling is only an upper limit: the system can land anywhere below it. In DrQA the ceiling is 77.8 and the real result is 27.1. The questions the retriever missed set the ceiling. The reader's weakness makes the gap between the ceiling and the real result.
Changing K on our corpus
Here is the result for every K on the least-crowded query. Passages with score 0 are not returned. my arithmetic
K
What the retriever returns
Queue log in?
Without the answer
1
queue log
yes
0
2
queue log, old forum post
yes
1
3 to 6
queue log, old forum post, office hours page
yes
2
At K = 1 the queue log comes back only because ties follow corpus order, and the queue log (P3) is listed before the forum post (P4). If the forum post had been listed first, the reader would get only the forum post at K = 1. So in a tie the result is decided by a rule that has nothing to do with the question.
Now look at all three widget queries at K = 2. The least-crowded query brings the queue log, the milestone query brings the syllabus, and the TA query brings nothing. So the right passage arrives for 2 of 3 queries, and 2 ÷ 3 = 0.667. Lesson 13 calls a measure of this kind . On these 3 queries no reader can answer more than 2 of 3 from the passages.
Think first
Set K = 6 for the TA query. Does the office hours page reach the reader now?
Show the answer
No. Every passage scores 0, and the retriever never returns passages with score 0, so nothing comes back whatever K is. A larger K raises recall only when the right passage scores above 0 but sits lower in the ranking.
In the company's system every passage is 500 tokens, so K passages need K × 500 tokens. At K = 14 that is 14 × 500 = 7,000 tokens, the whole space from lesson 1. A larger K does not fit into the prompt, however much it would help recall.
8Now read Stanford's slides yourself
Below are this lesson's Stanford slides, unchanged. Under each slide are a few questions. Think of your own answer first, then open it. If something is unclear, go back to the step named in the answer. If a slide looks small on a phone, click the image and it opens at full size.
Stanford's slide: Why Retrieval?
Read the Why Retrieval? slide
The slide's query also contains this week: which office hour this week is least crowded. What changes in the word-overlap scores?
Show the answer
this is a stopword, and week is left. The syllabus has Week 6 and Week 10, so the syllabus gets 1. The queue log says weeks, not week, so it stays at 2, and the forum post stays at 2 as well. The tie stays. (Step 3)
In the box on the right, which part is the retriever's work and which is the reader's?
Show the answer
The Retrieved line is the passage the retriever returned, the queue log. The answer below it is what the reader wrote from that passage. (Steps 2 and 3)
The answer on the left talks about midweek hours. Which passage in our corpus says the same, and what does it do at K = 2?
Show the answer
The old forum post: midweek afternoons are usually the least crowded. At K = 2 it goes into the prompt with the queue log, and the reader may write Wednesday again. (Step 3)
Stanford's slide: Using Retrieval to Overcome LMs’ Shortcomings, with its diagram enlarged below.
Read the just-in-time slide
What does just-in-time mean, and how is it different from memorize everything?
Show the answer
The model does not keep everything in its parameters. The right text enters the prompt exactly when the question arrives. (Step 2)
Which problems from lesson 1 do Dynamic and Interpretable solve?
Show the answer
Dynamic: a new fact needs no training, only a new passage in the corpus. Interpretable: with the citation you can open the source and check it. (Step 2)
In the diagram, what is the Text Collection, and why does the answer end with [1]?
Show the answer
The Text Collection is the corpus the retriever searches. [1] Wikipedia - Immune system is the source of the returned passage, and the [1] in the answer is its citation. (Steps 1 and 2)
Stanford's slide: Retrieval Often Used in Open-Domain QA. The Wikipedia article in the middle is only a picture, and you do not need to read it.
Read the open-domain QA slide
What is the corpus on this slide, and what is its N in DrQA?
Show the answer
All of English Wikipedia. The paper has 5,075,182 articles, so N = 5,075,182. (Step 6)
Where did the Document Reader get 833,500 from?
Show the answer
From the Warsaw article the retriever returned. DrQA's reader does not make up an answer: it picks a span from the article. (Step 6)
Why is this called open-domain QA?
Show the answer
The question can be about any topic, and the system is not handed the paragraph. It has to find it in all of Wikipedia itself. (Step 6)
Stanford's slide: Retriever-Reader Framework, with its two lines and the text at the bottom enlarged below.
Read the Retriever-Reader Framework slide
Write f(𝒟, Q) ⟶ P1, …, PK for our first query and K = 2.
Show the answer
f(the 6-passage corpus, which office hour is least crowded) ⟶ queue log, old forum post. (Step 5)
Why does the slide call the retriever a fixed module?
Show the answer
DrQA's TF-IDF retriever is not trained. Its rule is fixed in advance, like the rule of our word overlap. (Steps 5 and 6)
What does distantly-supervised mean in the reader's first bullet?
Show the answer
For datasets with only questions and answers, a rule found the paragraphs automatically, from the retriever and the answer text. On our corpus that rule picks the syllabus for the milestone question. (Step 6)
Stanford's slide: Issues with RAG, with its retrieval part enlarged below. The other problems come in lesson 18.
Read the Issues with RAG slide
Missing evidence limits agent: what was this limit in the table of step 4?
Show the answer
60 questions. The retriever brought the right passage for 60 questions, so even the perfect reader stopped at 60. (Step 4)
What is this limit in DrQA, and what is the real result?
Show the answer
The ceiling is 77.8%, and the real Exact Match is 27.1%. (Step 7)
For the least-crowded query at K = 2, the prompt holds two passages that contradict each other. Which reader-side boxes does this match?
Show the answer
Distraction, meaning similar but useless text, and Evidence conflict, meaning sources that disagree. Both come in lesson 18. (Step 3)
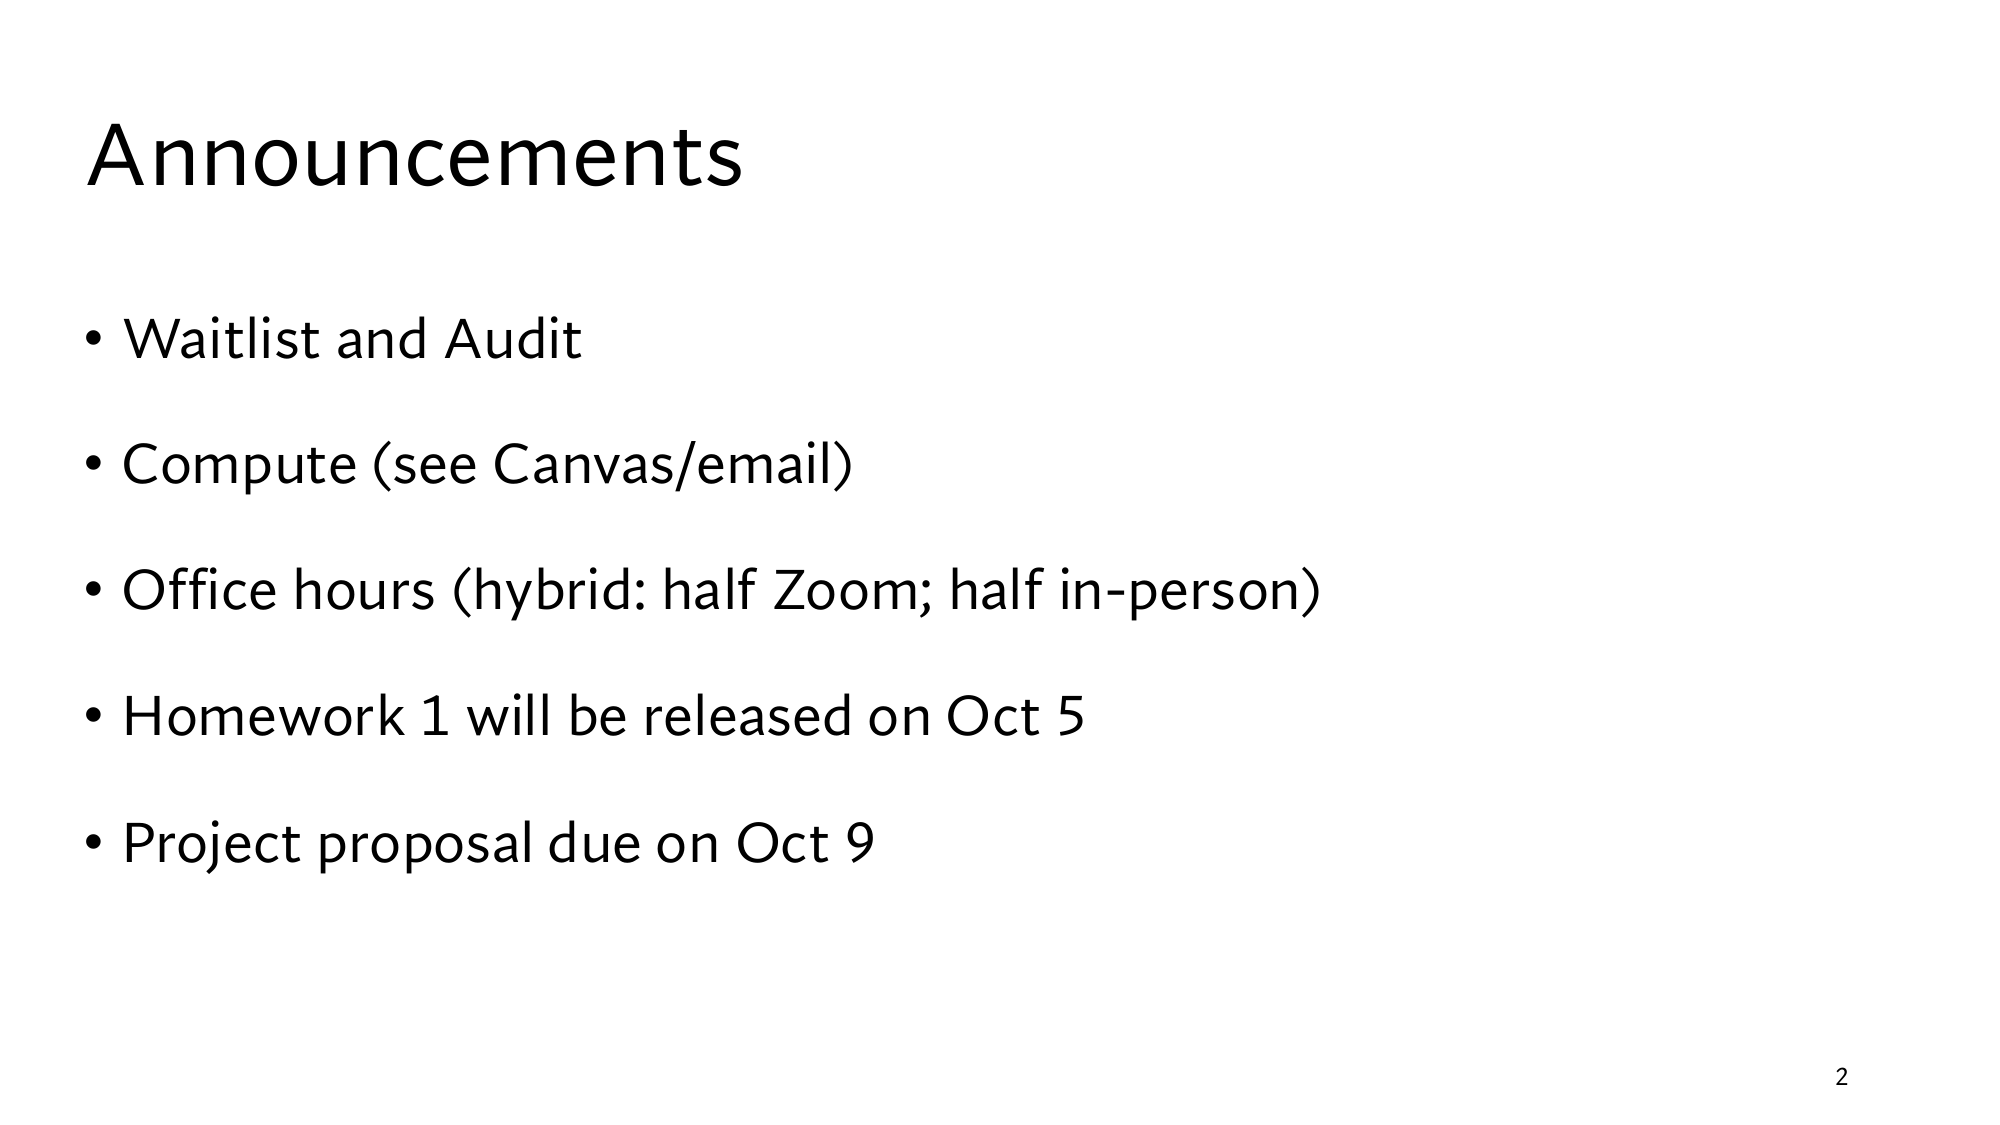
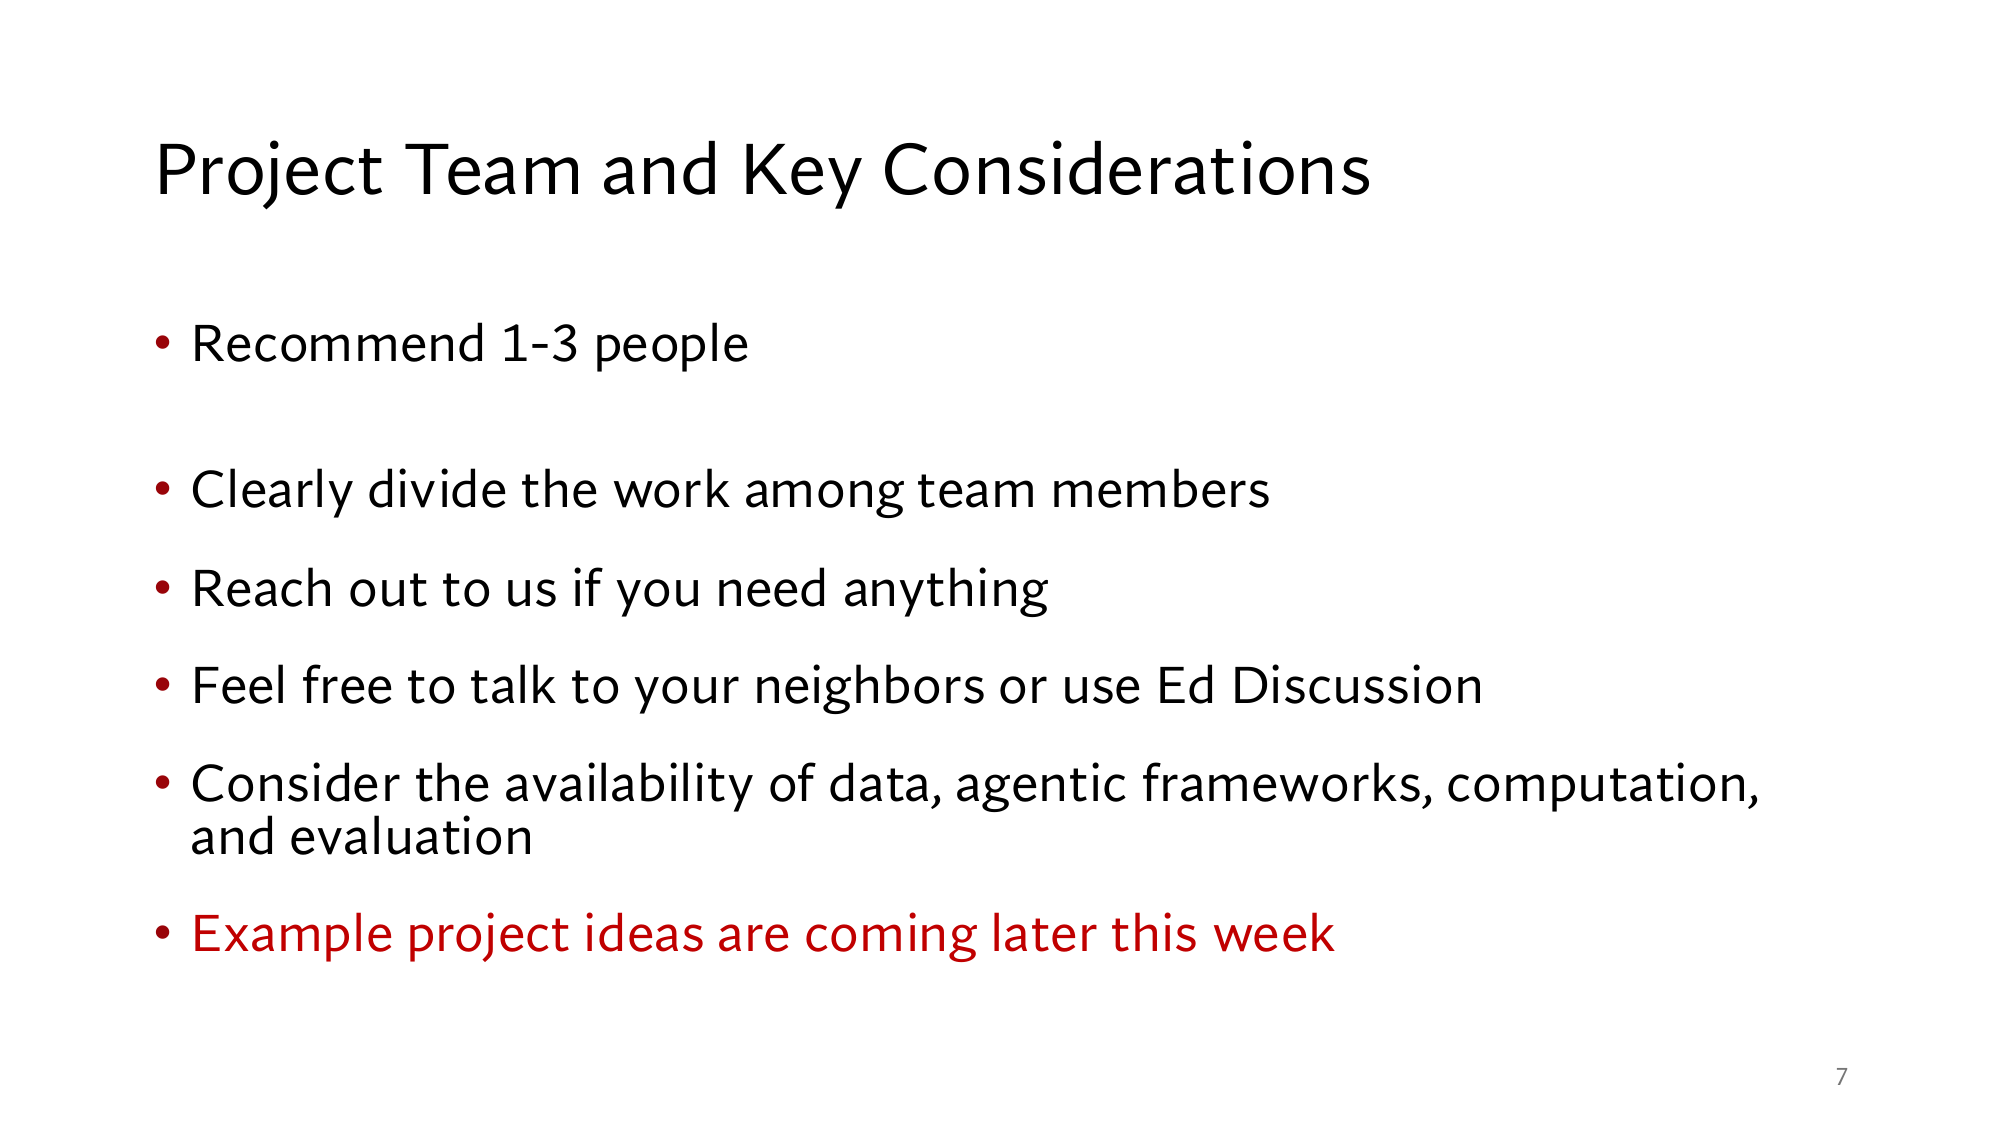
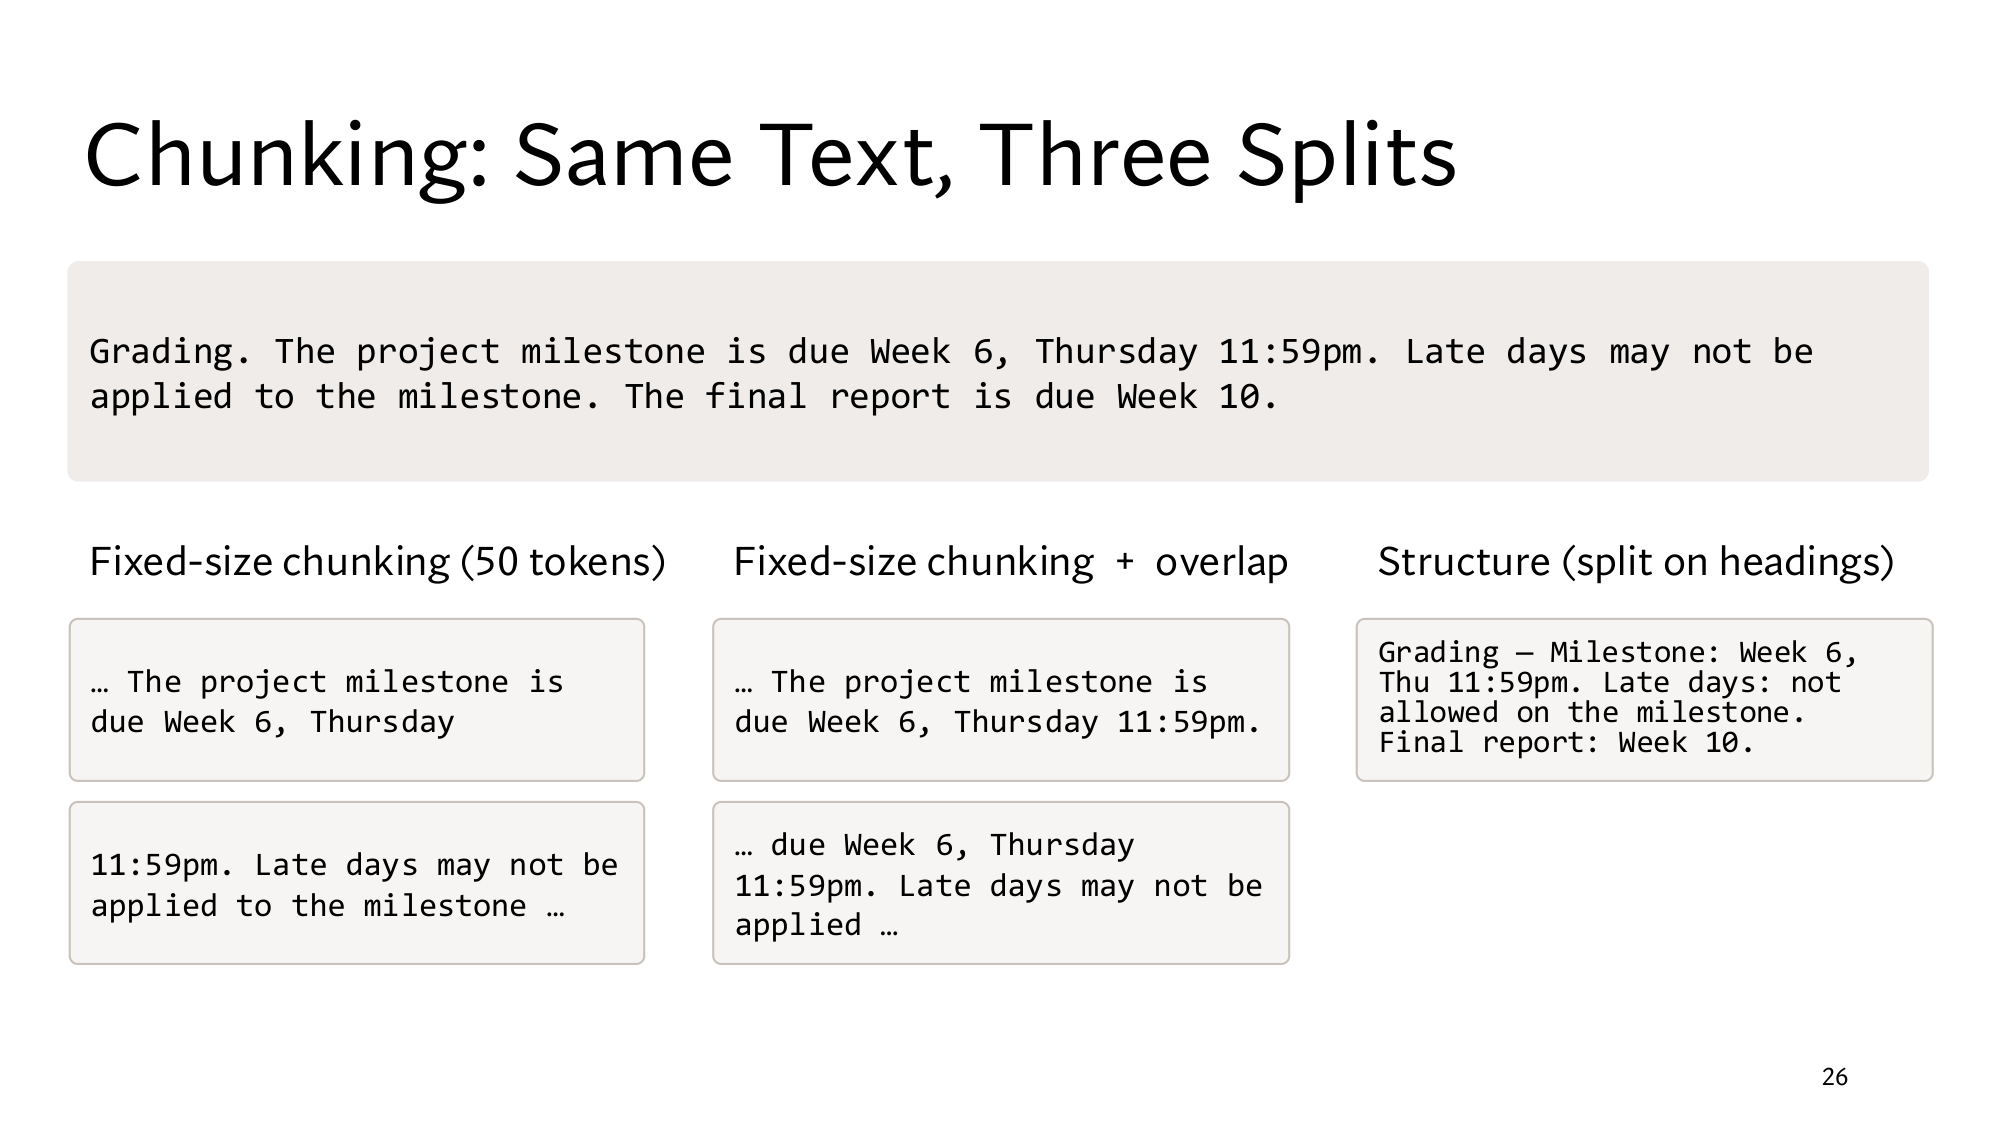
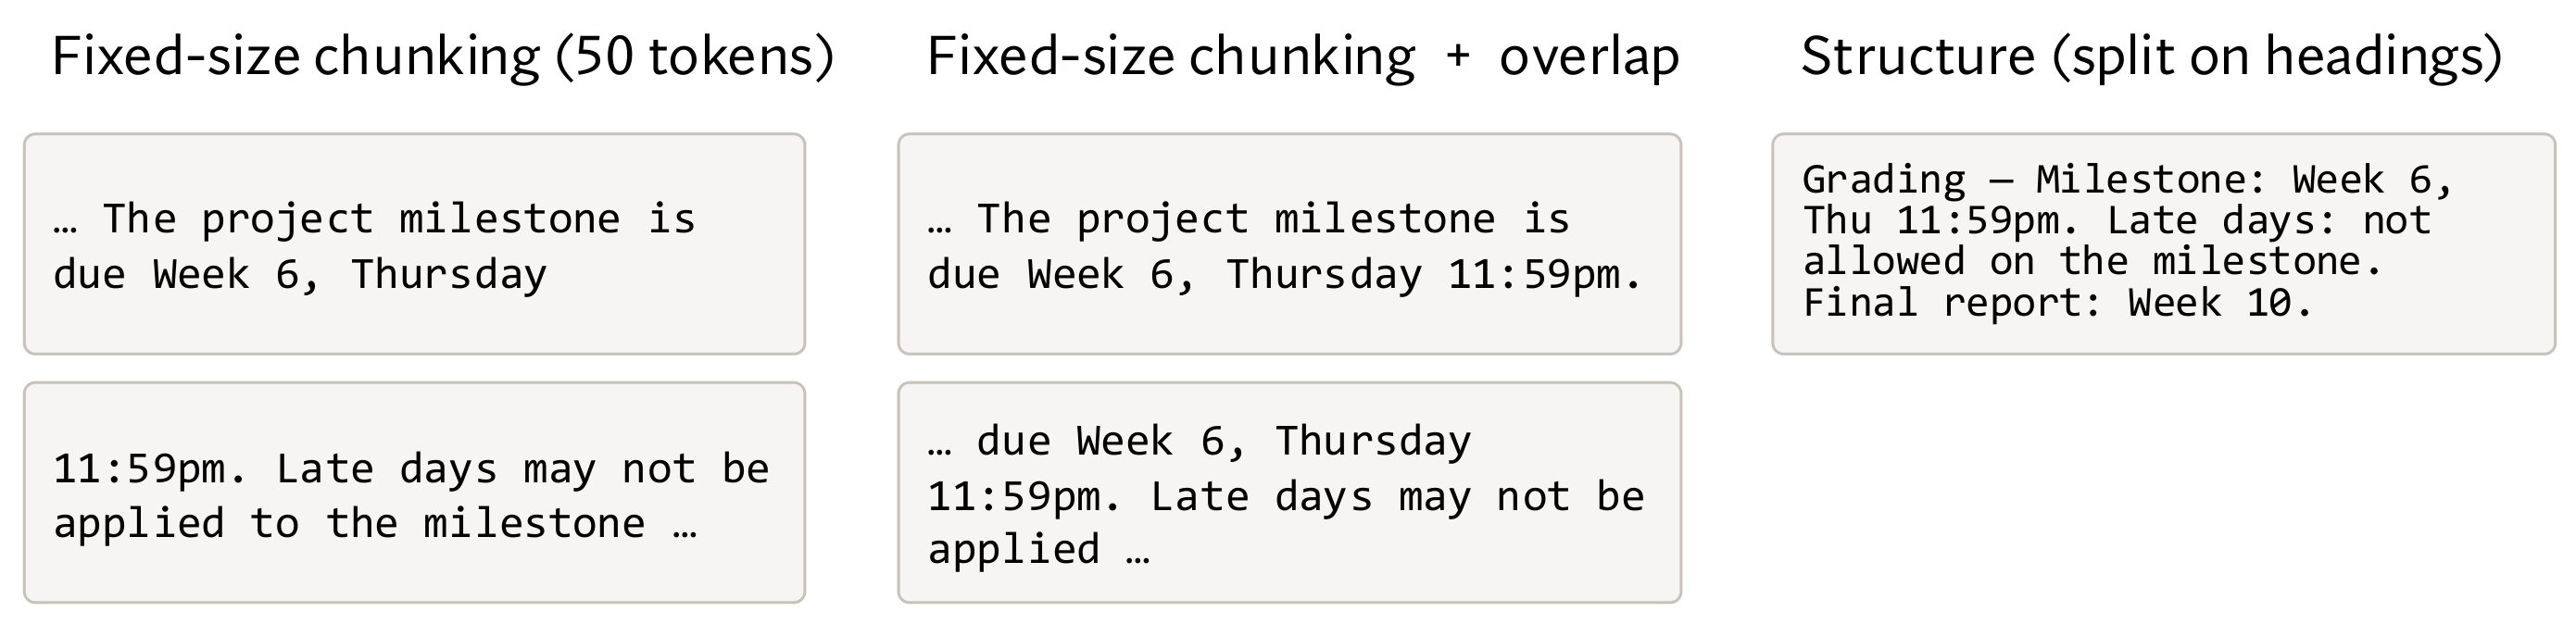
Three Stanford slides that our corpus passages come from: Announcements, Project Team and Key Considerations, and Chunking: Same Text, Three Splits. At the end, the three chunking methods enlarged.
Read the corpus slides
Which passages in our corpus come from these three slides?
Show the answer
The Announcements slide gave the Homework 1 announcement and the project proposal date. The Project Team slide gave the team of 1-3 people, and these two facts make up the project page. The Chunking slide gave the full text of the syllabus. (Step 1)
On the chunking slide, where do the fixed 50-token chunks cut the milestone date? What does that do to retrieval?
Show the answer
The first chunk ends at due Week 6, Thursday, and 11:59pm is in the second chunk. If the retriever returns only the first chunk, the reader does not get the full date. Where a passage should end is the subject of lesson 7. (Step 1)
3 points from this lesson
Retrieval: for every query, pick a few passages from the corpus and put them into the prompt. It needs no training, and the answer comes with a citation.
The retriever f(𝒟, Q) gives the top-K passages, and the reader g(Q, {P1, …, PK}) writes the answer from them. Word overlap gives the queue log and the old forum post the same score, 2, and bigrams do not break the tie either.
A passage the retriever did not bring is never read, and that is the recall ceiling. In DrQA the ceiling is 77.8%, yet the whole system reaches 27.1%, because the ceiling is only an upper limit.
New terms in this lesson
Corpus (collection)
The set of all documents. For example, the company's 2,000 documents, or this course's 6 short texts.
Document
One item in the corpus: a web page, a file or an email. For example, the course syllabus.
Passage
A small piece of a document, which the retriever returns. For example, the syllabus paragraph that holds the milestone date.
Query
The question you search for. For example, “which office hour is least crowded”.
Retrieval
Finding useful passages for a query and putting them into the prompt. For example, the queue log going into the prompt with the question.
Citation
The source written next to an answer. For example, the [P3] in “Thursday 9am [P3]”, which points to the queue log.
Non-parametric memory
Knowledge kept outside the model, in the corpus. For example, the queue log: changing it needs no training.
Retriever
The part that scores every passage and returns the top K. For example, this lesson's word-overlap retriever.
Score
A number for how useful a passage is for the query. For example, the queue log's word-overlap score of 2.
Top-K
The K passages with the highest scores. For example, the queue log and the old forum post at K = 2.
Word overlap
How many of the query's words appear in the passage. The simplest score. For example, the queue log has office and hour, so its score is 2.
Stopwords
Very common words such as is, the and which, left out of the count. From “which office hour is least crowded”, which and is are removed.
Reader
The part that reads the query and the top-K passages and writes the answer. Today usually an LLM. For example, reading the queue log and writing “Thursday 9am”.
Zero-shot
Doing a task from an instruction alone, without training on that task. For example, the prompt line “Answer the question using the passage below”.
Recall
How often the retriever finds the passage that is needed. For example, 60 out of 100 questions gives a recall of 60%.
Recall ceiling
The retriever's recall becomes the upper limit of the whole system. With a recall of 60%, no reader can get more than 60 of 100 answers from the passages.
Reading comprehension
Answering a question about a text you are given. This is the reader's job after the retriever. For example, reading the Ottoman empire paragraph and answering 32.
SQuAD
Stanford Question Answering Dataset: questions people wrote about Wikipedia paragraphs, with the answer always a span of the paragraph. For example, 87,599 training questions.
Open-domain QA
A question on any topic that comes without its paragraph, so the system has to find it in the whole corpus. For example, DrQA's Warsaw question over all of Wikipedia.
DrQA
A 2017 retriever-reader system: a fixed TF-IDF retriever returns 5 Wikipedia articles, and a neural reader picks a span from them. For example, 833,500 for the Warsaw question.
Bigram
Two words that appear side by side. For example, office hour in the queue log, and least crowded in the forum post.
Distant supervision
Finding paragraphs automatically for data that has only questions and answers: run the retriever and keep the passages that contain the answer text exactly. For example, the syllabus for the milestone question.