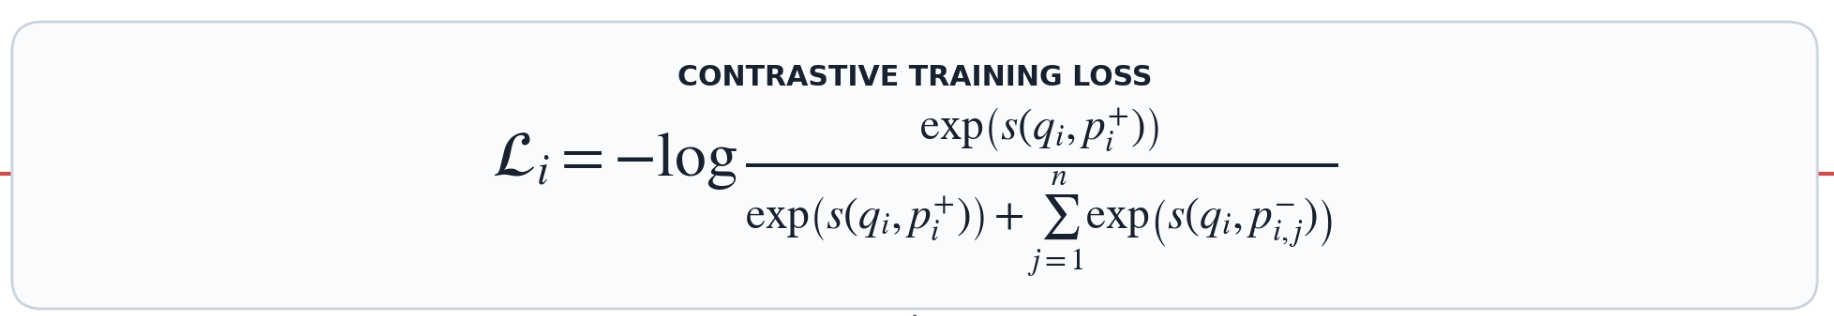DPR: a retriever trained on question-passage pairs
DPR is a retriever that turns the question and every passage into vectors. It then picks the passages whose vectors have the largest dot product with the question's vector. Two encoders produce these vectors, and both encoders are trained on pairs of a question and its correct passage. DPR stands for Dense Passage Retrieval, and it is the retriever inside the RAG model from lesson 5.
The need for it showed up in lesson 11. For the question which office hour is least crowded, BM25 gave an old 2024 forum post 2.749 and ranked it first. The answer is in the queue log, which came second with 2.473, because it does not contain the words least and crowded. DPR's encoders are trained so that this question's vector moves close to the queue log's vector.
The ladder for this lesson
The ladder has 9 steps. The first 5 are the same as in the easy version, and steps 6 to 9 take you to the level of the Stanford slides. Under each step you can see what you will be able to do after it.
What you need first: Lesson 3 (vector, dot product, encoder), Lesson 4 (exp, softmax, ln, loss, gradient) and Lesson 11 (BM25). From step 6 on, Lesson 5 (θ, backpropagation, Exact Match) and Lesson 10 (HNSW) also help. If you already know a step, skip to the next one. A word with a dotted underline and ▾ opens its definition when you click it.
1Two encoders and a dot product
DPR has two separate encoders: the question encoder EQ makes the question's vector, and the passage encoder EP makes a vector for every passage. An is a model that reads text and returns a vector of fixed length. Both DPR encoders start from , and DPR them on question-passage pairs.
The score is the of the two vectors:
s(q, p) = EQ(q)⊤ EP(p)
The here is only a way of writing the dot product, and Stanford's slide writes it this way.
Now look at a small example. A real vector has 768 numbers. Here each has only 4, so you can do the arithmetic by hand. my vectors
Text, and the vector the encoder makes for it
Dot product with the question
Question: least crowded office hour[1.0, 0.5, 0.5, 1.0]
–
Queue log, which has the answer[0.2, 0.4, 0.4, 0.4]
1.0
Old forum post[0.8, 1.0, 0.4, 0.5]
2.0
Homework 1 announcement[0.5, 0.4, 0.6, 0.5]
1.5
The queue log's score comes from 1.0 × 0.2 + 0.5 × 0.4 + 0.5 × 0.4 + 1.0 × 0.4 = 1.0. The encoders are not trained yet, so the wrong forum post is on top with 2.0. Training in step 2 changes this order.
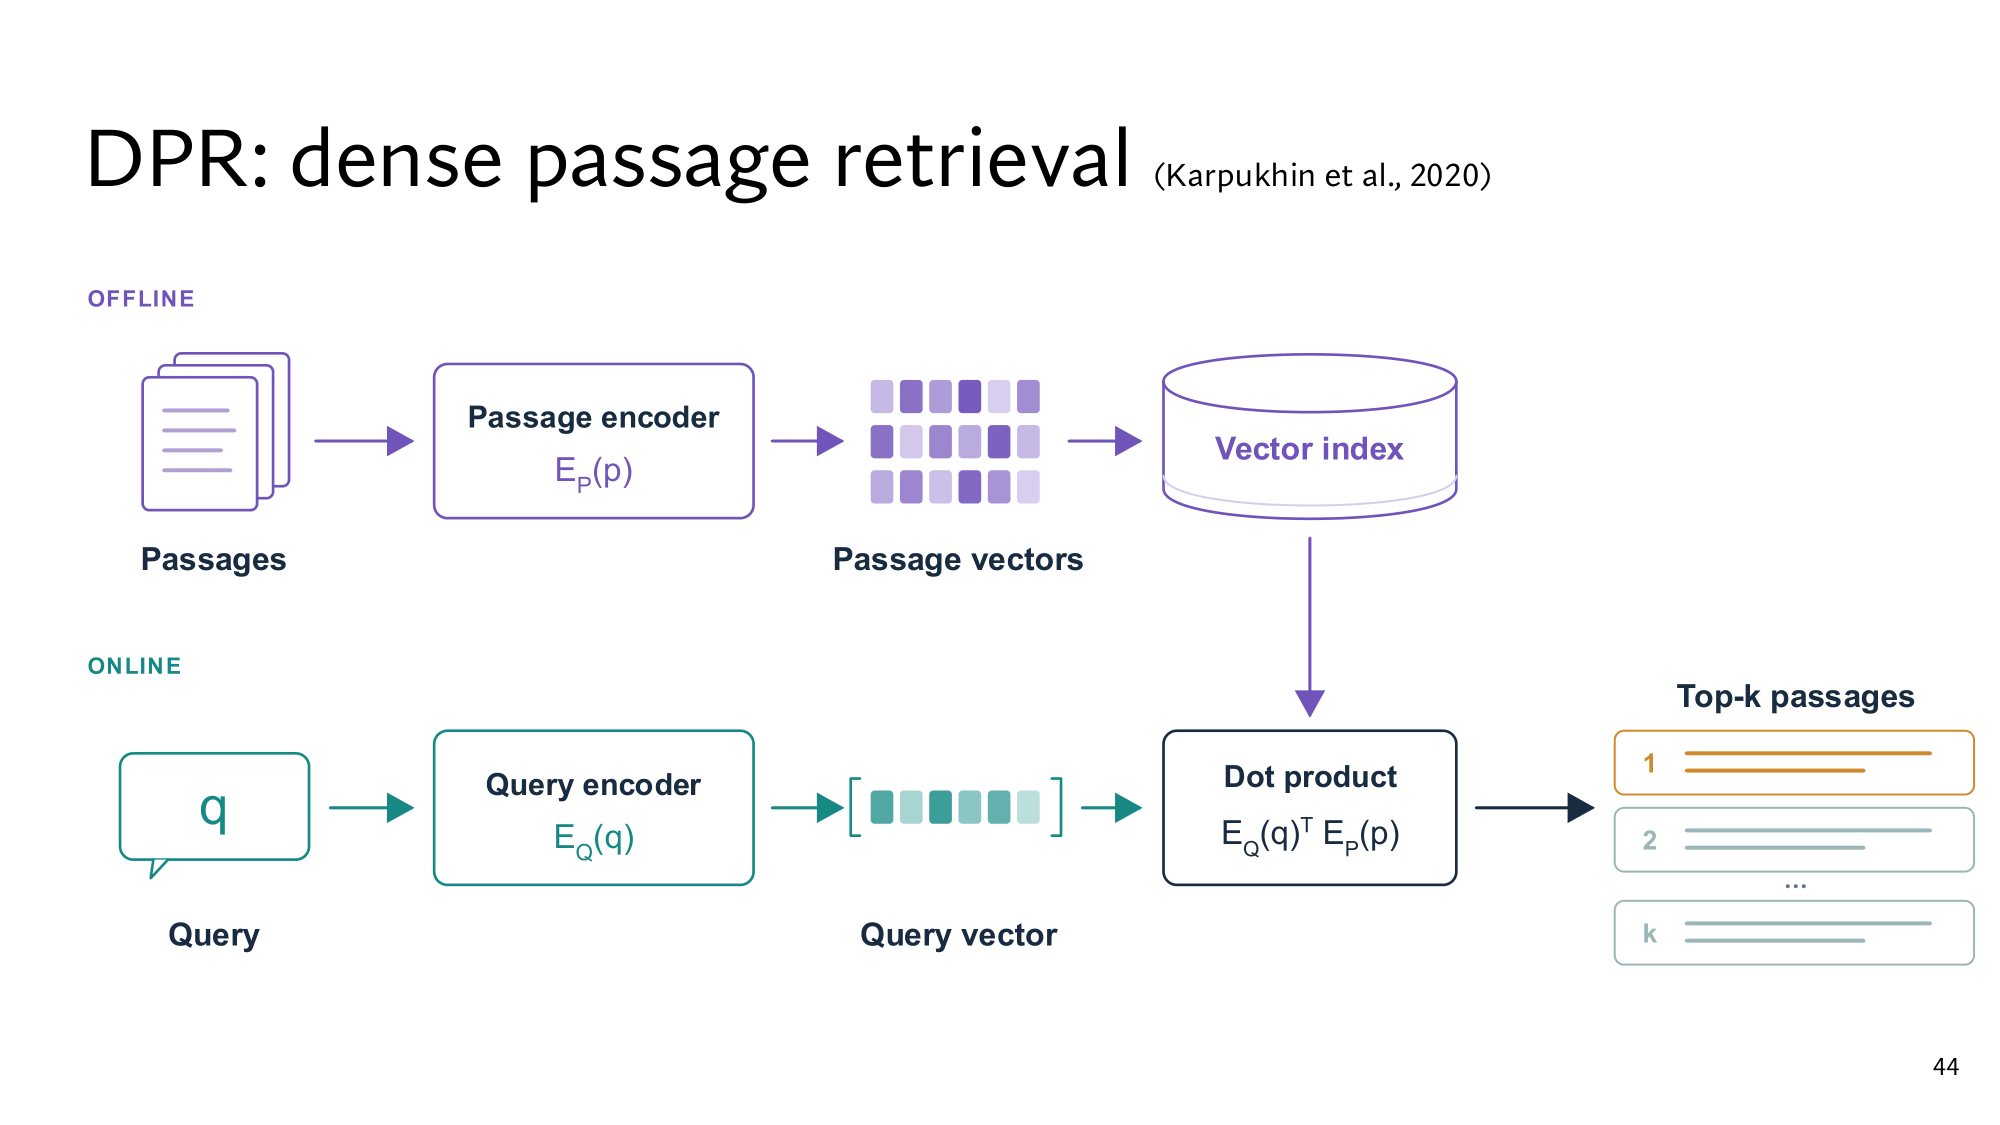
DPR reads the question and the passage separately, and the benefit is speed. Its work splits into two parts:
, before any question arrives: the passage encoder makes each passage's vector once and stores them all in an .
Online, when a question arrives: the question encoder runs once. Then the dot products with the index vectors are computed, and the passages with the k largest scores come back.
If one model read the question and the passage together, it would have to run once for every passage on every question. The Wikipedia from lesson 5 had about 21 million passages, so the model would run 21 million times per question. In DPR the model runs only once per question. This two-encoder design is called a bi-encoder.
Stanford's slide: the offline and online parts of DPR. The top half is offline, and the bottom half is online. You can now read every box on it. Click the image to open it at full size.
Think first
Double the question's vector, so it becomes [2.0, 1.0, 1.0, 2.0]. What are the three scores now, and does the order change?
Show the answer
The scores become 2.0, 4.0 and 3.0. In a dot product, every multiplication takes one number from the question's vector. That number doubled, so every product doubled, and so did their sum: for the queue log, 2.0 × 0.2 + 1.0 × 0.4 + 1.0 × 0.4 + 2.0 × 0.4 = 2.0. Every score doubled, but the order stayed the same, and the forum post is still on top. This matters in step 2.
2Contrastive loss: putting the right passage ahead of the wrong ones
Contrastive loss compares the score of the right passage with the scores of the wrong passages. The further ahead the right passage is, the smaller the loss. Both DPR encoders are trained to make this loss small.
For this comparison, every training question needs two kinds of passages:
Positive
The question's correct passage. The training data lists it with every question. For our question it is the queue log.
Negative
A wrong passage for the same question. In our example, the forum post and the Homework 1 announcement.
The comparison matters because a retriever passes on only the top passages, so the order is what counts. In the question at the end of step 1 you saw that a longer question vector raises every score but keeps the order. If training only asked for a higher positive score, the encoder could take exactly that easy route.
Now compute the loss on the scores from step 1: queue log 1.0, forum post 2.0 and Homework 1.5. The loss takes three steps:
Take for each score: 2.72, 7.39 and 4.48. e is a fixed number, about 2.718, so e1.0 = 2.72 and e2.0 = 2.718 × 2.718 = 7.39. The three add up to 14.59.
Find the positive's share: 2.72 ÷ 14.59 = 0.186.
Take −ln of that share: −ln 0.186 = 1.68. This is the loss. ln tells you the power you must raise e to in order to get a number. Check: e−1.68 = 1 ÷ e1.68 = 1 ÷ 5.37 = 0.186.
Steps 1 and 2 together are , and step 3 is the from lesson 4. The formula holds the same three steps:
𝓛 = − ln es+es+ + ∑ es−
On top is the positive's escore (2.72), and below is the sum of escore for the positive and all negatives (14.59).
Think first
Add 1 to all three scores: 2.0, 3.0 and 2.5. What is the loss now?
Show the answer
Still 1.68. Adding 1 to a score makes its escore 2.72 times bigger, because ea+1 = ea × e. For example, e2.0 = e1.0 × 2.72 = 7.39. The top and the bottom are both multiplied by 2.72, and the division cancels it. So the queue log's share stays at 0.186.
The table below has four situations. The last two rows are two stages of training, and step 3 uses the middle stage. my scores
Scores (queue log, forum post, Homework)
Queue log's share
Loss
Before training: 1.0, 2.0, 1.5
0.186
1.68
Question vector doubled: 2.0, 4.0, 3.0
0.090
2.41
Partway through training: 3.0, 2.0, 0.5
0.690
0.372
After training: 5.0, 2.0, 0.5
0.943
0.059
Doubling the question vector raises the loss from 1.68 to 2.41, because the forum post moves further ahead. So the easy route of a longer vector does not work here.
As training goes on, the queue log moves ahead, and the loss falls from 1.68 to 0.372 and then to 0.059.
So the encoders have only one way to lower the loss: give the queue log a higher score than the other two.
Run the contrastive loss yourself
Change the three scores. The loss is small when the queue log is well above the other two. Move all three by the same amount, and the loss does not change.
3Negatives: from the batch and from BM25
Contrastive loss needs negatives for every question, and the more negatives there are, the stricter the comparison. But every negative has to go through the passage encoder, and that is expensive. DPR takes negatives from two places where this cost is low.
The positives of the other questions in the batch
In-batch negatives means treating the positives of the other questions in a batch as negatives for this question. Training runs questions in small groups, and each group is called a batch. The positive of every question in the batch is already encoded in that same step, so these negatives need no extra encoding.
Below is a batch of 3 questions, partway through training. In each row the bold number is that question's positive, and the other numbers in the row are its negatives. my scores
Question ↓ / passage →
Queue log
Syllabus
Office hours
Loss
Least crowded office hour?
3.0
1.0
0.5
0.197
When is the milestone due?
0.8
3.0
1.2
0.244
Where are office hours held?
0.3
2.5
2.0
?
Work out the third row
The positive is the office hours page, with score 2.0. The negatives are the queue log (0.3) and the syllabus (2.5). What is the loss, and why is this row different from the other two?
Show the answer
e0.3 = 1.35, e2.5 = 12.18 and e2.0 = 7.39, which sum to 20.92. The office hours page's share is 7.39 ÷ 20.92 = 0.353, and the loss is −ln 0.353 = 1.041. In this row the wrong syllabus (2.5) is above the right page (2.0), so its loss is the largest.
In the paper a batch has 128 questions, so each question gets 127 in-batch negatives. from the paper
Hard negatives from BM25
A hard negative is a wrong passage that looks similar to the question but does not contain the answer. For our question, the forum post is exactly such a passage. It has both words, least and crowded, but no data about how crowded anything is.
In-batch negatives are mostly easy, because they are passages for other questions. Hard negatives produce a large loss, and the larger the loss, the more training changes the encoders. Partway through training the queue log is at 3.0, and the two negatives compare like this: my scores
Negative
Loss with only this negative
What the encoder learns
Homework announcementeasy negative, score 0.5
0.079queue log's share 0.924
Almost nothing, because the gap is already clear
Forum posthard negative, score 2.0
0.313, about 4 times as muchqueue log's share 0.731
The question's words are not enough. The passage needs crowd data.
The first row works out like this: e3.0 = 20.09 and e0.5 = 1.65, which add up to 21.73. The queue log's share is 20.09 ÷ 21.73 = 0.924, and the loss is −ln 0.924 = 0.079.
To find such passages, DPR uses BM25. For each training question it looks at BM25's top passages and takes one that does not contain the answer. This works because BM25 makes exactly the mistake the encoders need to unlearn. On our question, too, BM25 put the forum post on top.
Watch out: Check the labels before you take hard negatives. Sometimes a top BM25 passage really does contain the answer, and only its label is missing. Then the encoder learns to push a correct passage down.
4How far ahead of BM25 DPR is
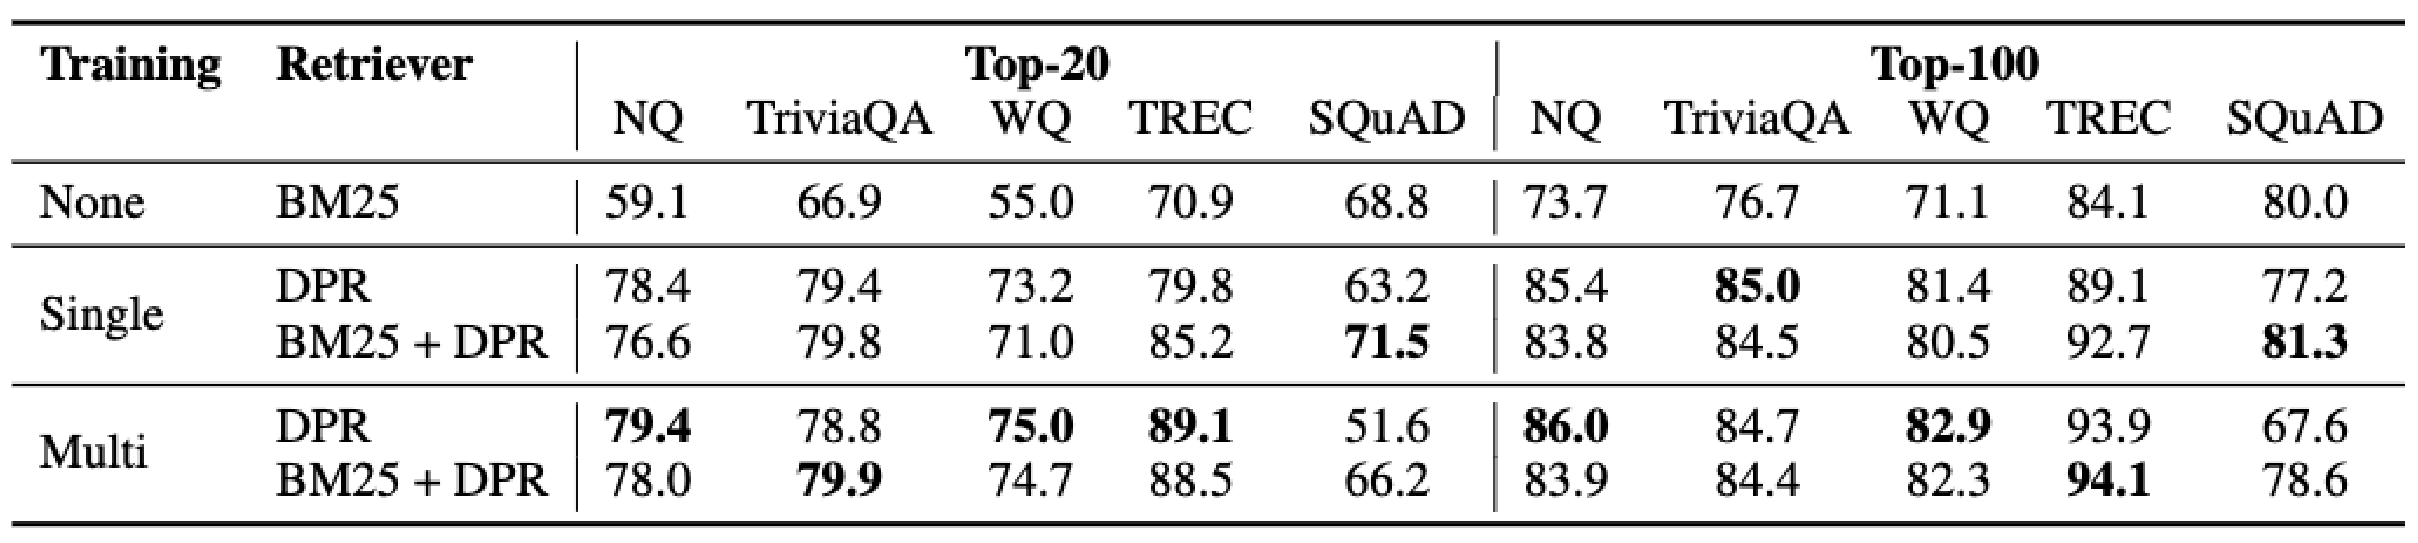
The DPR paper measures a retriever by top-k retrieval accuracy: the percentage of questions whose answer passage appears in the top k. The NQ dataset holds real questions people typed into Google. On it, BM25's top-20 accuracy is 59.1%, and DPR's is 78.4%.
Out of 1,000 questions, that is 591 against 784. So with DPR, the answer passage reaches the reader for 193 more questions.
DPR is ahead on 4 of the 5 datasets. On SQuAD it is behind, 63.2 against 68.8, because there people wrote the questions after reading the passage. Those questions therefore reuse the passage's own words, and matching exact words is what BM25 does. this reason is in the paper
Numbers for all five datasets
Dataset
BM25
DPR
NQ
59.1
78.4
TriviaQA
66.9
79.4
WQ
55.0
73.2
TREC
70.9
79.8
SQuAD
68.8
63.2
Top-20 accuracy (%) on the test sets. Here DPR was trained separately on each dataset.
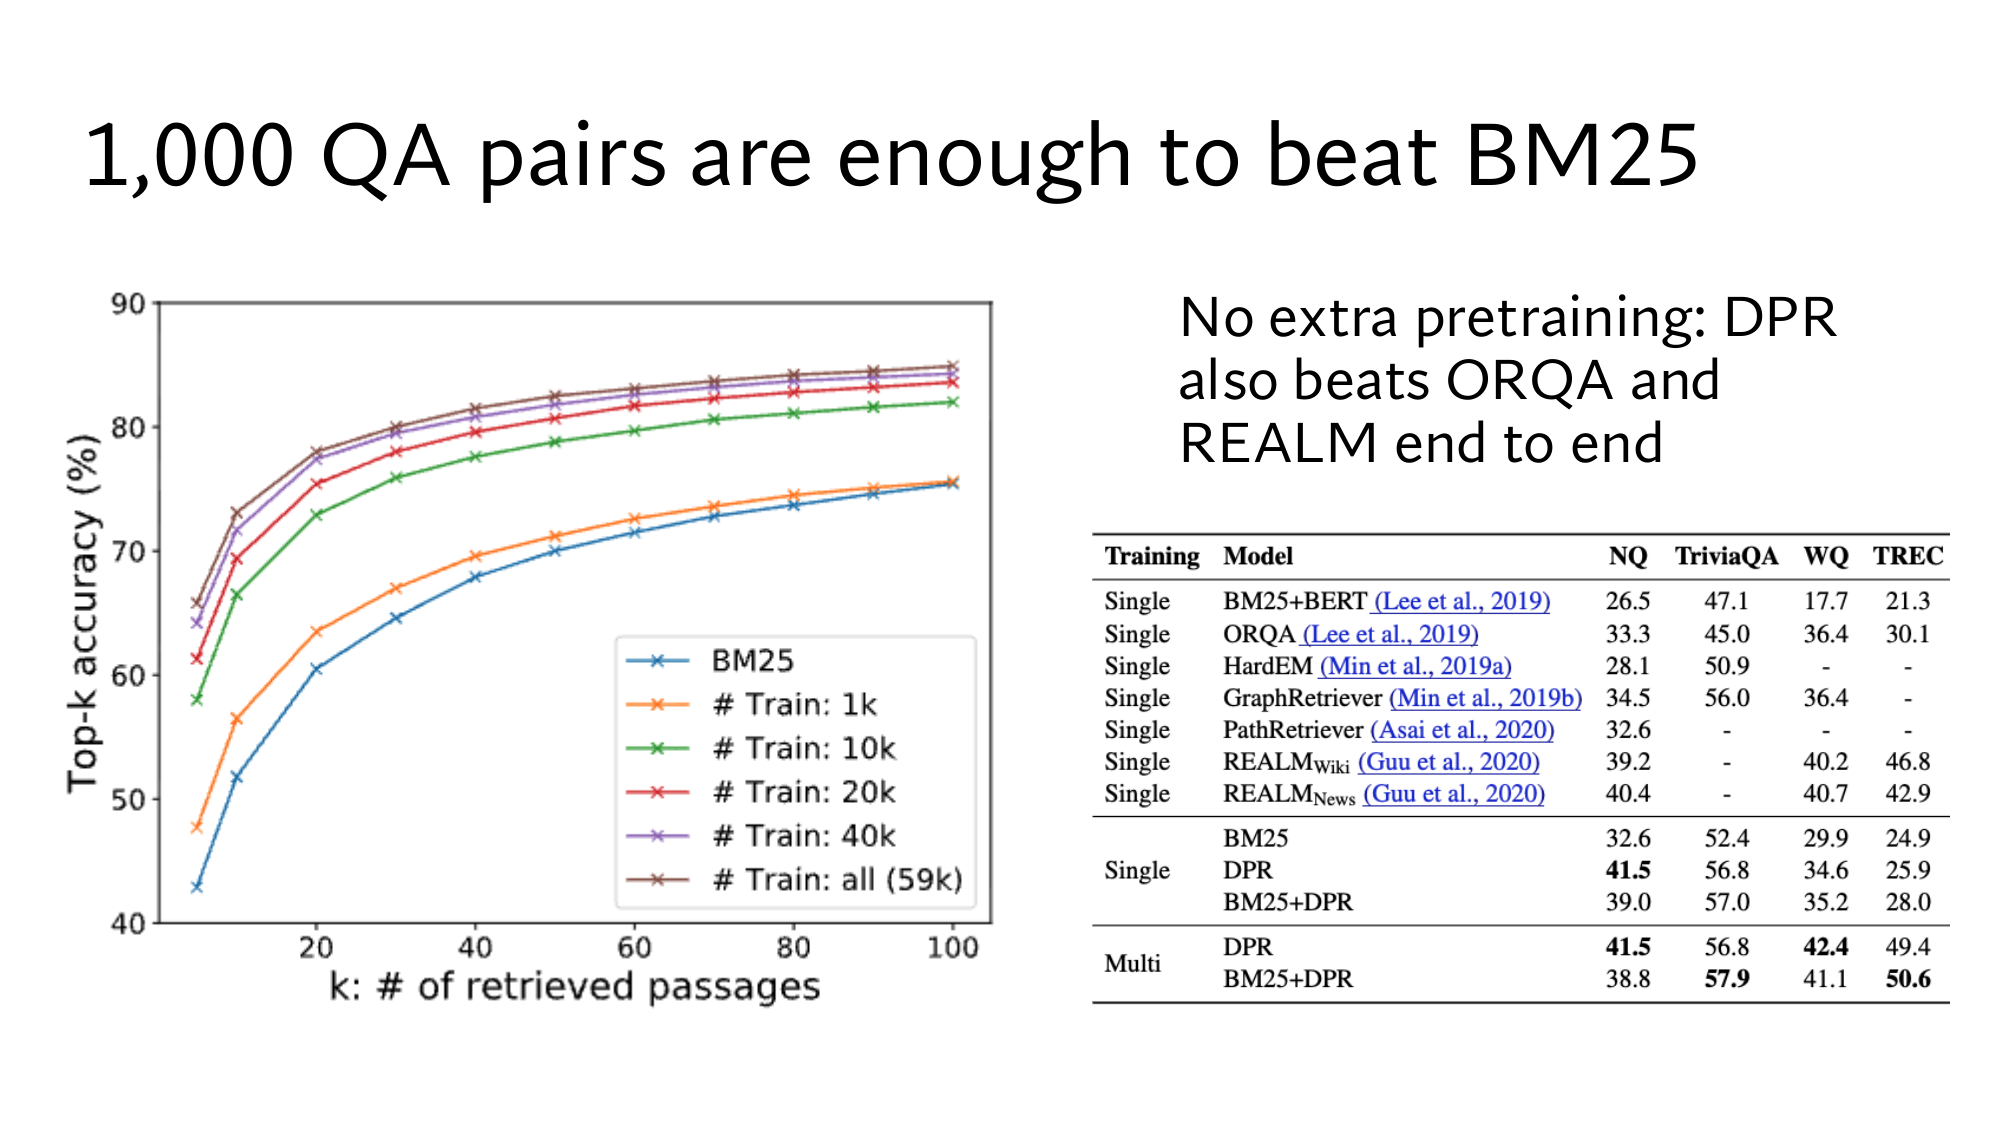
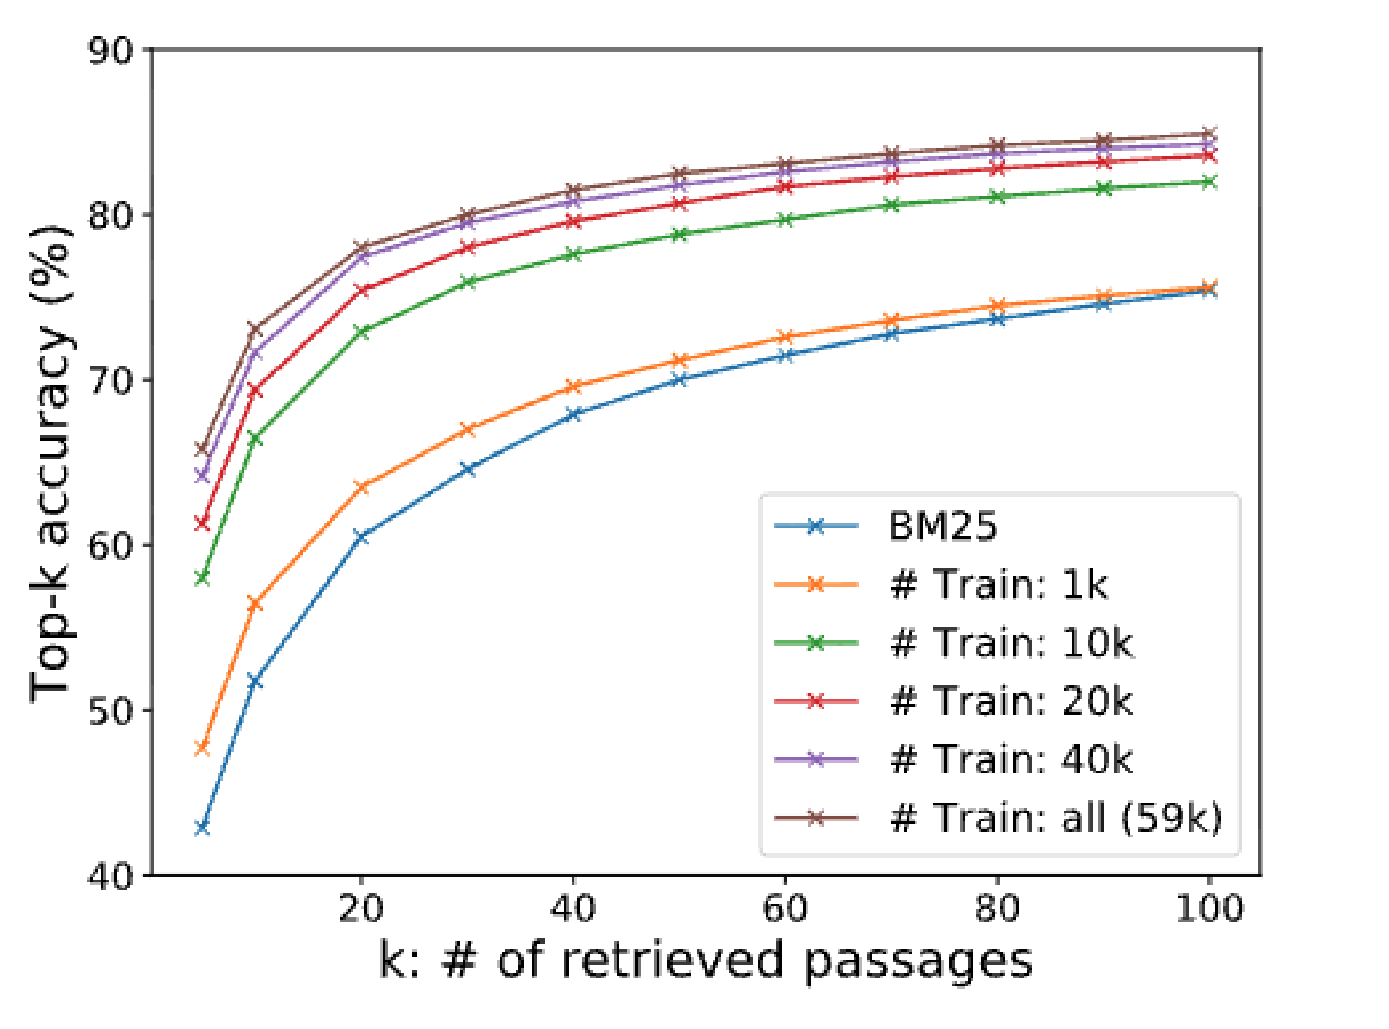
DPR needs labeled pairs, and the paper also measured how many. A DPR trained on only 1,000 pairs from NQ already beats BM25, and accuracy keeps rising with more pairs.
5Where DPR is weak
DPR wins at semantic matching across a whole corpus, but it has three weaknesses:
If a code like error 4012 appears in only one or two passages, BM25 treats it as rare and ranks those passages high. DPR's vector sums up the whole passage, and a single code like that is easily lost in it. Lesson 15 starts from exactly this case.
A passage's vector is made without seeing the question, so the question and the passage meet only at the final dot product. The reranker in lesson 14 works on this gap.
Training needs labeled question-passage pairs, even if only 1,000 of them.
BM25's strengths and weaknesses are the opposite of these. That is why lesson 14 combines the lists from BM25 and DPR.
From here: the Stanford level
The 5 steps above are the same as in the easy version. The 4 steps below take you to the level of the Stanford slides: the slide's symbols and the maths behind them, the whole batch as one multiplication and the paper's experiments, the real scale, and finally reading the slides yourself. Every piece of maths is explained where it first appears.
6The slide's symbols, and the maths of the gradient
So far everything has been one question and its numbers. The slide writes the same arithmetic in symbols, so that it applies to every question in a batch. Here is the slide's full formula:
The table below ties each symbol to a number from our example:
Symbol
Meaning
In our example
qi
The i-th question in the batch
The least-crowded question, i = 1
pi+
The positive for question qi
Queue log
pi,j−
The j-th negative for question qi. j runs from 1 to n.
j = 1 is the forum post, j = 2 is Homework, and n = 2
EQ( · ; θQ)
The question encoder. Text goes where the “·” is, and θQ are its , the numbers that training changes.
The question encoder from step 1
EP( · ; θP)
The passage encoder, with parameters θP
The passage encoder from step 1
hqi = EQ(qi) ∈ ℝd
The question's vector. means a list of d real numbers, and ∈ means “belongs to”.
[1.0, 0.5, 0.5, 1.0], so d = 4
s(qi, p) = EQ(qi)⊤EP(p)
The score, the dot product of the two vectors. The slide calls it inner-product similarity, and inner product is another name for dot product.
1.0, 2.0 and 1.5
exp(x)
ex, where e is about 2.718
exp(1.0) = 2.72
∑j=1n
The over j from 1 to n
7.39 + 4.48
log
The natural log, ln
−ln 0.186
𝓛i
The loss for question qi
1.68
∇θQ𝓛i
The rate of the loss for every parameter in θQ, as one list. It is built up step by step below.
–
The gradient: the loss's rate for each score
Lesson 4 introduced the : which way to change each parameter so that the loss goes down. There are hundreds of millions of parameters, so first look at the same idea on three scores, where the arithmetic is small.
Finding a rate is simple: change the input a tiny amount, see how much the output changed, and divide that change by the change in the input. On the scores from before training, 1.0, 2.0 and 1.5, the loss is 1.68. Now raise one score at a time by 0.01:
Score raised by 0.01
Change in loss
Change ÷ 0.01
Queue log (positive)
−0.0081
−0.81
Forum post
+0.0051
+0.51
Homework
+0.0031
+0.31
Take an even smaller change than 0.01, and these rates settle at −0.814, +0.506 and +0.307. The number a rate settles at is the gradient. The minus sign means the loss falls when the queue log's score rises, and the plus signs mean the loss rises when a negative's score rises.
This rate is written ∂𝓛/∂s: how fast the loss 𝓛 changes when the score s changes a little. The ∂ means that only this one score changed and everything else stayed the same. It is called a partial derivative.
Why these rates match the softmax shares
These rates match the softmax shares from step 2: −0.814 = 0.186 − 1, and 0.506 and 0.307 are exactly the shares of the forum post and Homework. This is no coincidence, and the reason takes five short steps:
Split the loss into two parts. Lesson 4 gives two rules: ln(a ÷ b) = ln a − ln b, and ln(ex) = x. So 𝓛 = −ln(es+ ÷ Z) = −s+ + ln Z, where Z is the sum of all escore, here 14.59. Check: −1.0 + ln 14.59 = −1.0 + 2.680 = 1.680.
The rate of es is es itself. Check: e1.01 − e1.00 = 2.7456 − 2.7183 = 0.0273, and 0.0273 ÷ 0.01 = 2.73, about e1.0 = 2.72.
The rate of ln Z is 1 ÷ Z. Check: ln 14.60 − ln 14.59 = 0.000685, and 0.000685 ÷ 0.01 = 0.0685, which equals 1 ÷ 14.59 = 0.0685.
Linked rates multiply. When the queue log's score changes, only es+ inside Z changes, at the rate 2.72. When Z changes, ln Z changes by 1 ÷ 14.59 times as much. So the rate of ln Z is 2.72 × (1 ÷ 14.59) = 0.186, which is the queue log's share. This rule of multiplying linked rates is called the chain rule. It is the chain rule for rates, not the probability chain rule from lesson 4.
Add the two parts. In 𝓛 = −s+ + ln Z, the rate for the queue log is −1 + 0.186 = −0.814. The forum post's score does not affect the −s+ part, so its rate is just 7.39 ÷ 14.59 = 0.506.
So the rate for each negative is its own softmax share, which means training pushes each negative's score down as hard as its share. That is why the hard negative taught more in step 3. Partway through training (3.0, 2.0, 0.5), the forum post's share is 0.254, and Homework's is only 0.057.
One step back: the rate on the question's vector
One step behind the scores is the question's vector hq, with 4 numbers q1 to q4. A passage's score is q1p1 + q2p2 + q3p3 + q4p4. Raise q1 by 0.01, and the score rises by p1 × 0.01. So the score's rate with respect to q1 is p1, the first number of that passage's vector.
Changing q1 changes all three scores, and each score changes the loss at its own rate. With the chain rule, the loss's rate with respect to q1 works out like this:
Queue log: score rate −0.814, times its first number 0.2, gives −0.163.
Forum post: 0.506 × 0.8 = 0.405.
Homework: 0.307 × 0.5 = 0.154.
Sum of the three: −0.163 + 0.405 + 0.154 = 0.396.
Doing this for all four numbers gives [0.396, 0.304, 0.061, 0.081] my arithmetic. It is written ∂𝓛/∂hq, one rate for each number of hq. The first two numbers are the largest because those are the two large numbers in the forum post's vector, 0.8 and 1.0. In formula form the same arithmetic reads:
∂𝓛 / ∂hq = (p+ − 1) hp+ + ∑j pj hpj
Here p+ and pj are the softmax shares, and hp+ and hpj are the passages' vectors. The four steps above are the first number of this formula.
Now move the question's vector a little in the opposite direction: subtract 0.5 times its rate from each number. The new vector is [0.802, 0.348, 0.469, 0.959], and the scores become 0.871, 1.657 and 1.301. The queue log's score also dropped a little, but the forum post's dropped more. So the gap between them shrank from 1.0 to 0.786, and the loss went from 1.68 to 1.554.
The last step: back to the encoder's parameters
The question's vector is not itself a parameter. The encoder makes it, and the encoder has hundreds of millions of parameters. from lesson 5 applies this same chain rule backwards through every layer of the encoder, and gets one rate for each parameter. The list of all these rates is written ∇θQ𝓛i, and the is read "nabla".
Training nudges every parameter a little against its rate, exactly as we nudged the question's vector above. ∇θQ𝓛i changes the question encoder, and ∇θP𝓛i changes the passage encoder. These are the two red arrows on the slide in step 9.
7The whole batch in one multiplication, and the paper's experiments on negatives
The batch table from step 3 is really a matrix. A matrix is a table of numbers with rows and columns. Stack the vectors of the batch's questions one under another, and you get the matrix Q, one question's vector per row. The vectors of their positives form the matrix P in the same way.
Writing P⊤ means turning P's rows into columns, which is called a transpose. The rule for multiplying Q by P⊤ is: the number in row i and column j of the result is the dot product of row i of Q with row j of P. Here it is with 2 questions and vectors of 2 numbers: my numbers
Question ↓ / positive →
p1 = [0, 2]
p2 = [1, 0]
q1 = [1, 2]
1×0 + 2×2 = 4
1×1 + 2×0 = 1
q2 = [2, 0]
2×0 + 0×2 = 0
2×1 + 0×0 = 2
This 2 × 2 table is S = QP⊤. On the diagonal, row 1 column 1 and row 2 column 2, sits each question's own positive: 4 and 2. The other cells are its in-batch negatives. The paper gets all of a batch's scores from this one multiplication: from the paper
S = Q P⊤
With a batch of B questions, S holds B × B scores. Each row gets its own contrastive loss, so one step yields B training examples. In the paper B = 128, so one multiplication gives 128 × 128 = 16,384 scores, and each question gets 127 in-batch negatives.
The paper also adds one BM25 negative per question, and all 128 BM25 negatives of a batch become negatives for every question in it. So each question gets 127 + 128 = 255 negatives. The n in the slide's formula is this 255 in DPR's real training. from the paper
The paper's experiments: which negatives help how much
The paper tried several ways of choosing negatives on the NQ dev set. The dev set is a set of questions the researchers use to check their decisions during training. In 1-of-N, each question has its own separate negatives, not shared with the other questions in the batch. In in-batch training, the negatives come from inside the batch. from the paper
Approach
Negatives per question
Top-20 (%)
1-of-N, random passages
7
64.3
1-of-N, BM25 passages
7
63.3
1-of-N, positives of other questionsfrom the whole training set
7
63.1
In-batch, batch 8
7
69.1
In-batch, batch 128
127
73.0
In-batch, batch 128, plus 1 BM25 negative per question
127 + 128
78.0
In 1-of-N, the kind of negative barely changes top-20 accuracy: all three are between 63 and 64.
When the same 7 negatives come from inside the batch, accuracy goes from 63.1 to 69.1. The paper's explanation is that one multiplication inside the batch forms more pairs, so there are more training examples.
Growing the batch from 8 to 128 raises the negatives from 7 to 127, and accuracy from 69.1 to 73.0.
Adding one BM25 negative per question raises accuracy from 73.0 to 78.0. A second BM25 negative does not help: at batch 32, one gives 77.3 and two give 76.4.
These are dev set numbers. On the test set, the final DPR's top-20 is 78.4, which appeared in step 4.
8Real scale and the full results
Our example had 3 passages and vectors of 4 numbers, so the arithmetic could be done by hand. The paper uses the same mechanism, only with bigger numbers: from the paper
Item
Our example
In the DPR paper
Passages
3
21,015,324 pieces of Wikipedia, 100 words each
Vector length d
4
768, the output vector of BERT-base
Encoders
The ones from step 1
Two separate BERT-base models
Batch
3 questions
128 questions
Negatives per question, n
2
127 in-batch + 128 BM25 = 255
Building all passage vectors
By hand
About 8.8 hours on 8 GPUs
Building the index
–
An HNSW index in FAISS, about 8.5 hours
Search speed
–
995 questions per second, top 100 per questionBM25: 23.7 questions per second on one CPU thread
is an open-source library for fast search over vectors. DPR used it with the index from lesson 10. Search is fast, but building the index is expensive. BM25's inverted index takes about 30 minutes, while DPR's vectors and index together take 8.8 + 8.5 = 17.3 hours. If the encoder changes, all of this has to be done again.
The full results
Step 4 gave the top-20 accuracy on NQ: 59.1% for BM25 and 78.4% for DPR. At top-5 the gap is even larger: 42.9% for BM25 and 65.2% for DPR. from the paper Below are all five datasets, along with a retriever that combines the BM25 and DPR scores:
Dataset
BM25
DPR
BM25 + DPR
NQ
59.1
78.4
76.6
TriviaQA
66.9
79.4
79.8
WQ
55.0
73.2
71.0
TREC
70.9
79.8
85.2
SQuAD
68.8
63.2
71.5
Top-20 accuracy (%) on the test sets. Here DPR was trained separately on each dataset.
For the score, the paper also tried cosine and L2 instead of the dot product. L2 did about as well as the dot product, and both did better than cosine. So DPR kept the simplest one, the dot product. from the paper
Before DPR, a dense retriever called (2019) had also beaten BM25. But ORQA first pretrained its retriever separately on an artificial task. In that task the model gets a sentence and has to say which passage it came from. DPR did no such extra pretraining. It used only BERT and question-passage pairs.
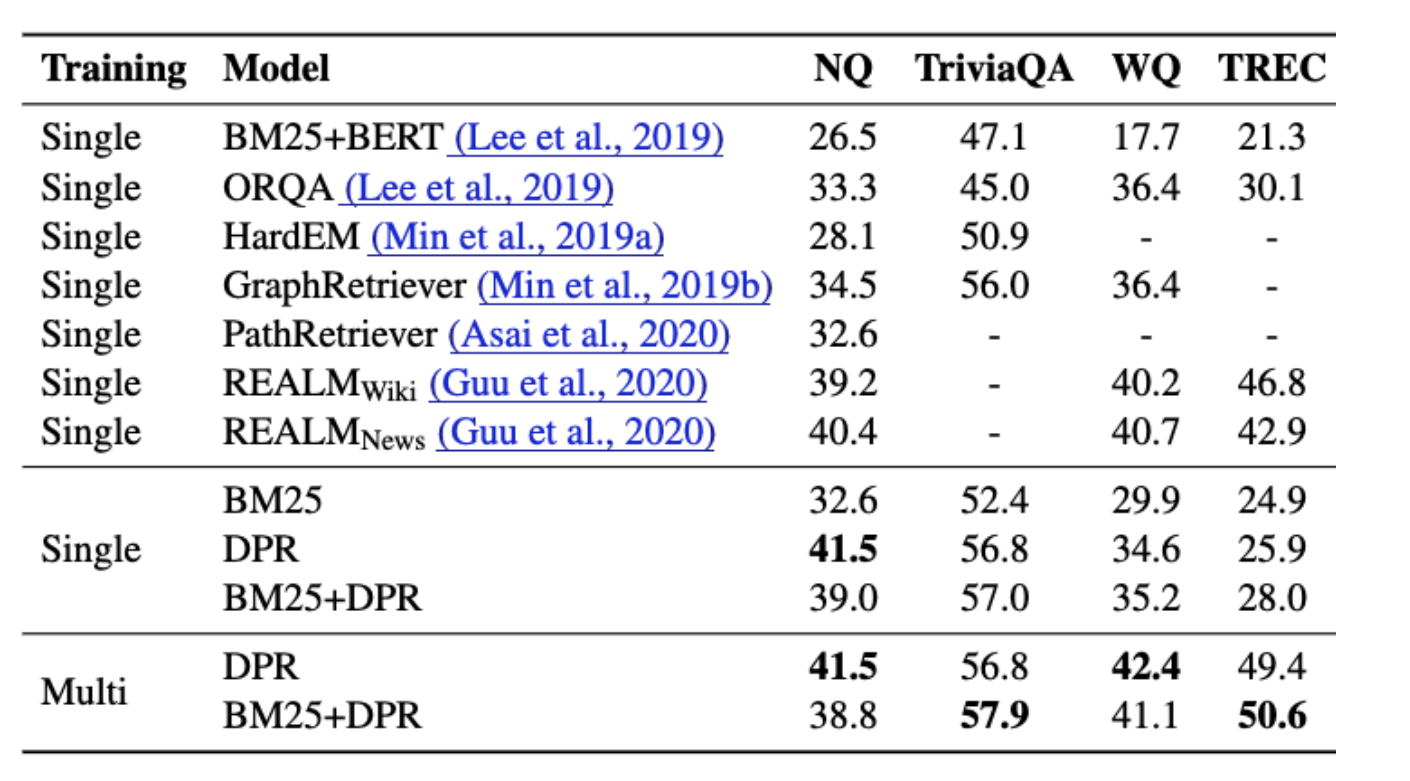
Even so, DPR is ahead in the full system. On NQ the with DPR is 41.5, with ORQA 33.3, and with BM25 32.6. REALM also uses extra pretraining, and its Exact Match is 39.2 and 40.4.
9Now read Stanford's slides yourself
Below are Stanford's four DPR slides, unchanged. Under each slide are a few questions. Think of the answer first, then open it. If a symbol stops you, go back to the step named in the answer. If a slide looks small on a phone, click the image to open it at full size.
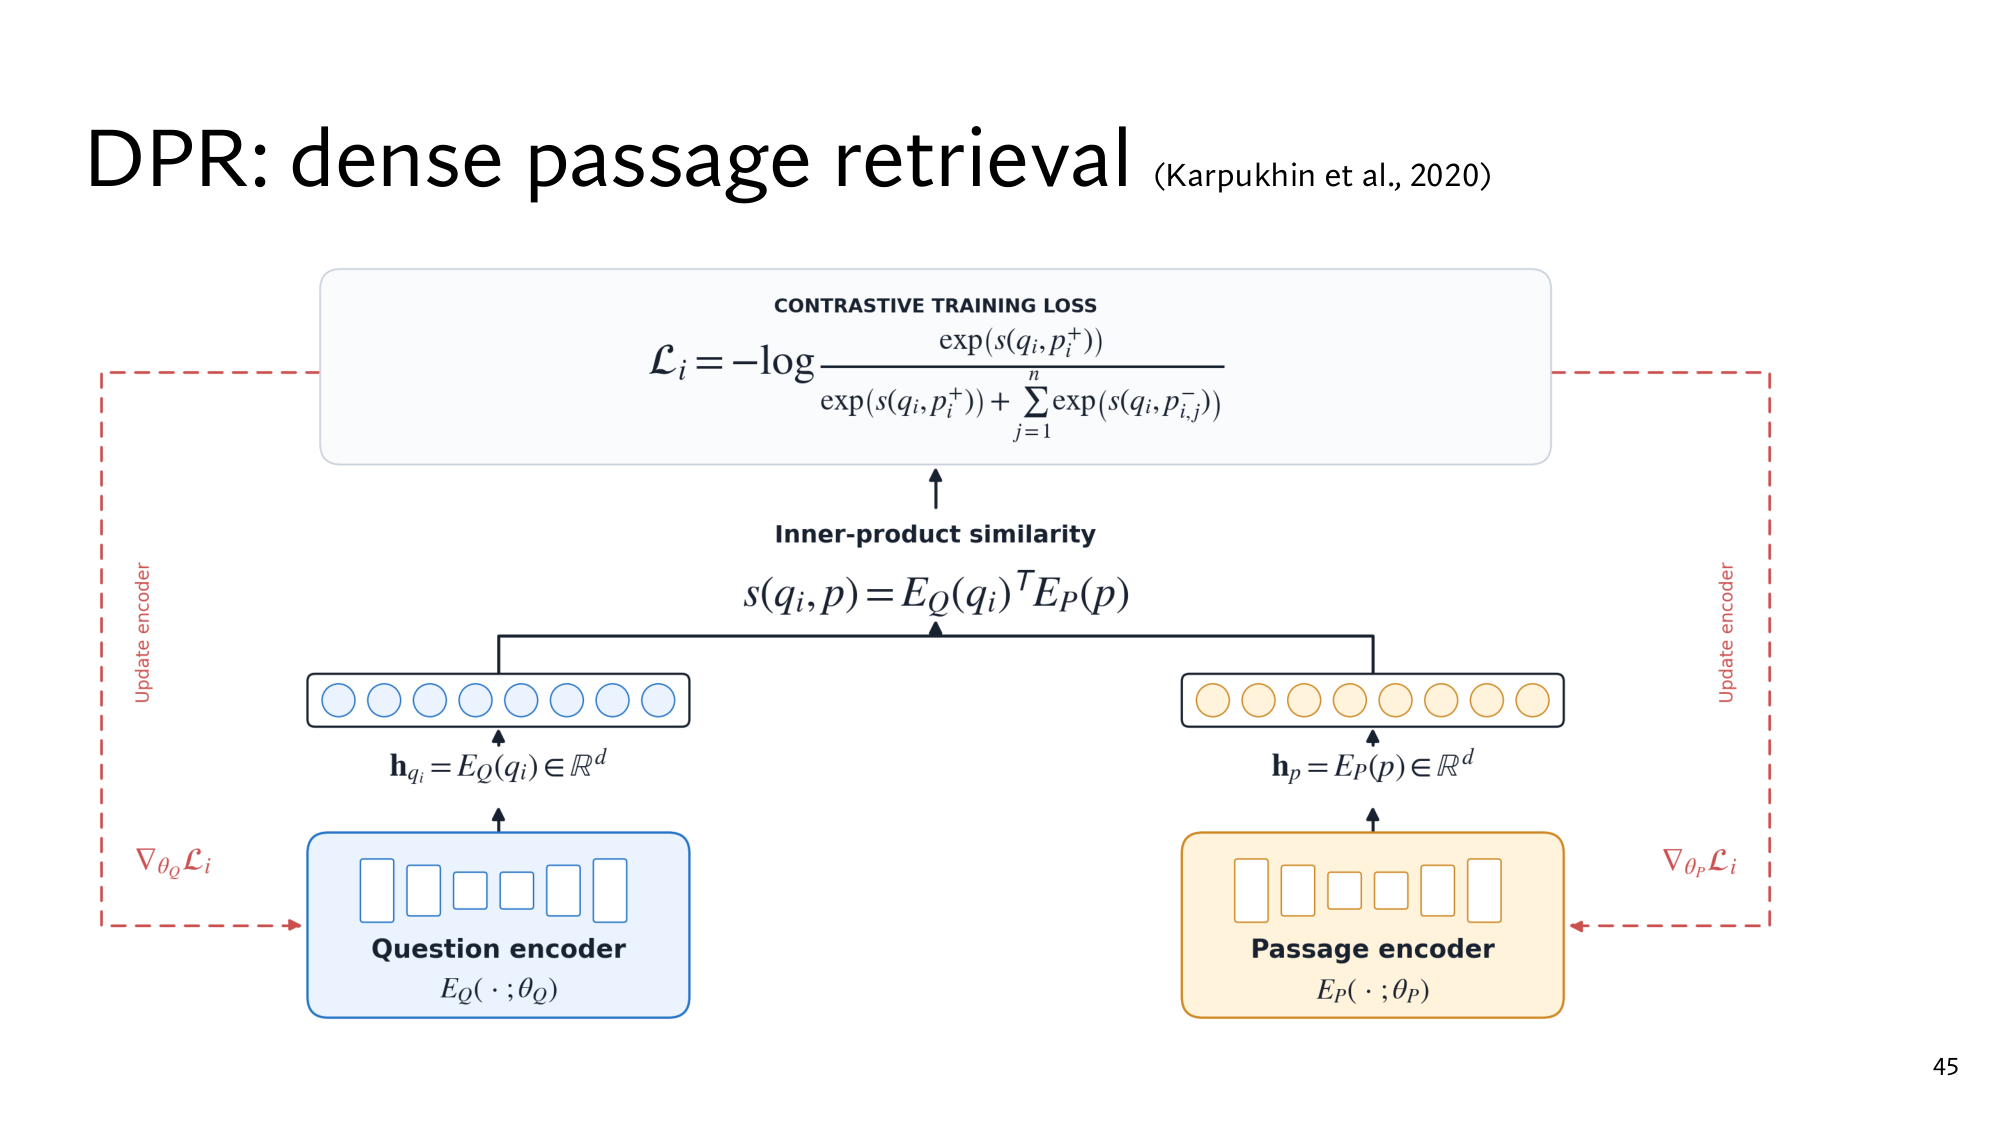
Stanford's training slide, and below it the loss part of the same slide, enlarged.
Read the training slide
In hqi ∈ ℝd, what is d? What was it in our example, and what is it in DPR?
Show the answer
4 in our example, and 768 in DPR. d is how many numbers the vector has. (Steps 6 and 8)
What is n in the ∑ under the loss? What was n in our example, and what is it in DPR's training?
Show the answer
n is the number of negatives for one question. Our example had 2, the forum post and Homework. DPR has 127 + 128 = 255. (Steps 6 and 7)
What do the red dashed arrows on both sides say? How does this differ from the RAG of lesson 5?
Show the answer
The arrows carry ∇θQ𝓛i and ∇θP𝓛i, so training changes the parameters of both encoders. In lesson 5's RAG the passage encoder stayed fixed, because changing it would have meant rebuilding the vectors of 21 million passages.
During DPR training there is no index. Each step encodes only the batch's passages, so the passage encoder can change too. The index is built once, after training ends. (Steps 1 and 6)
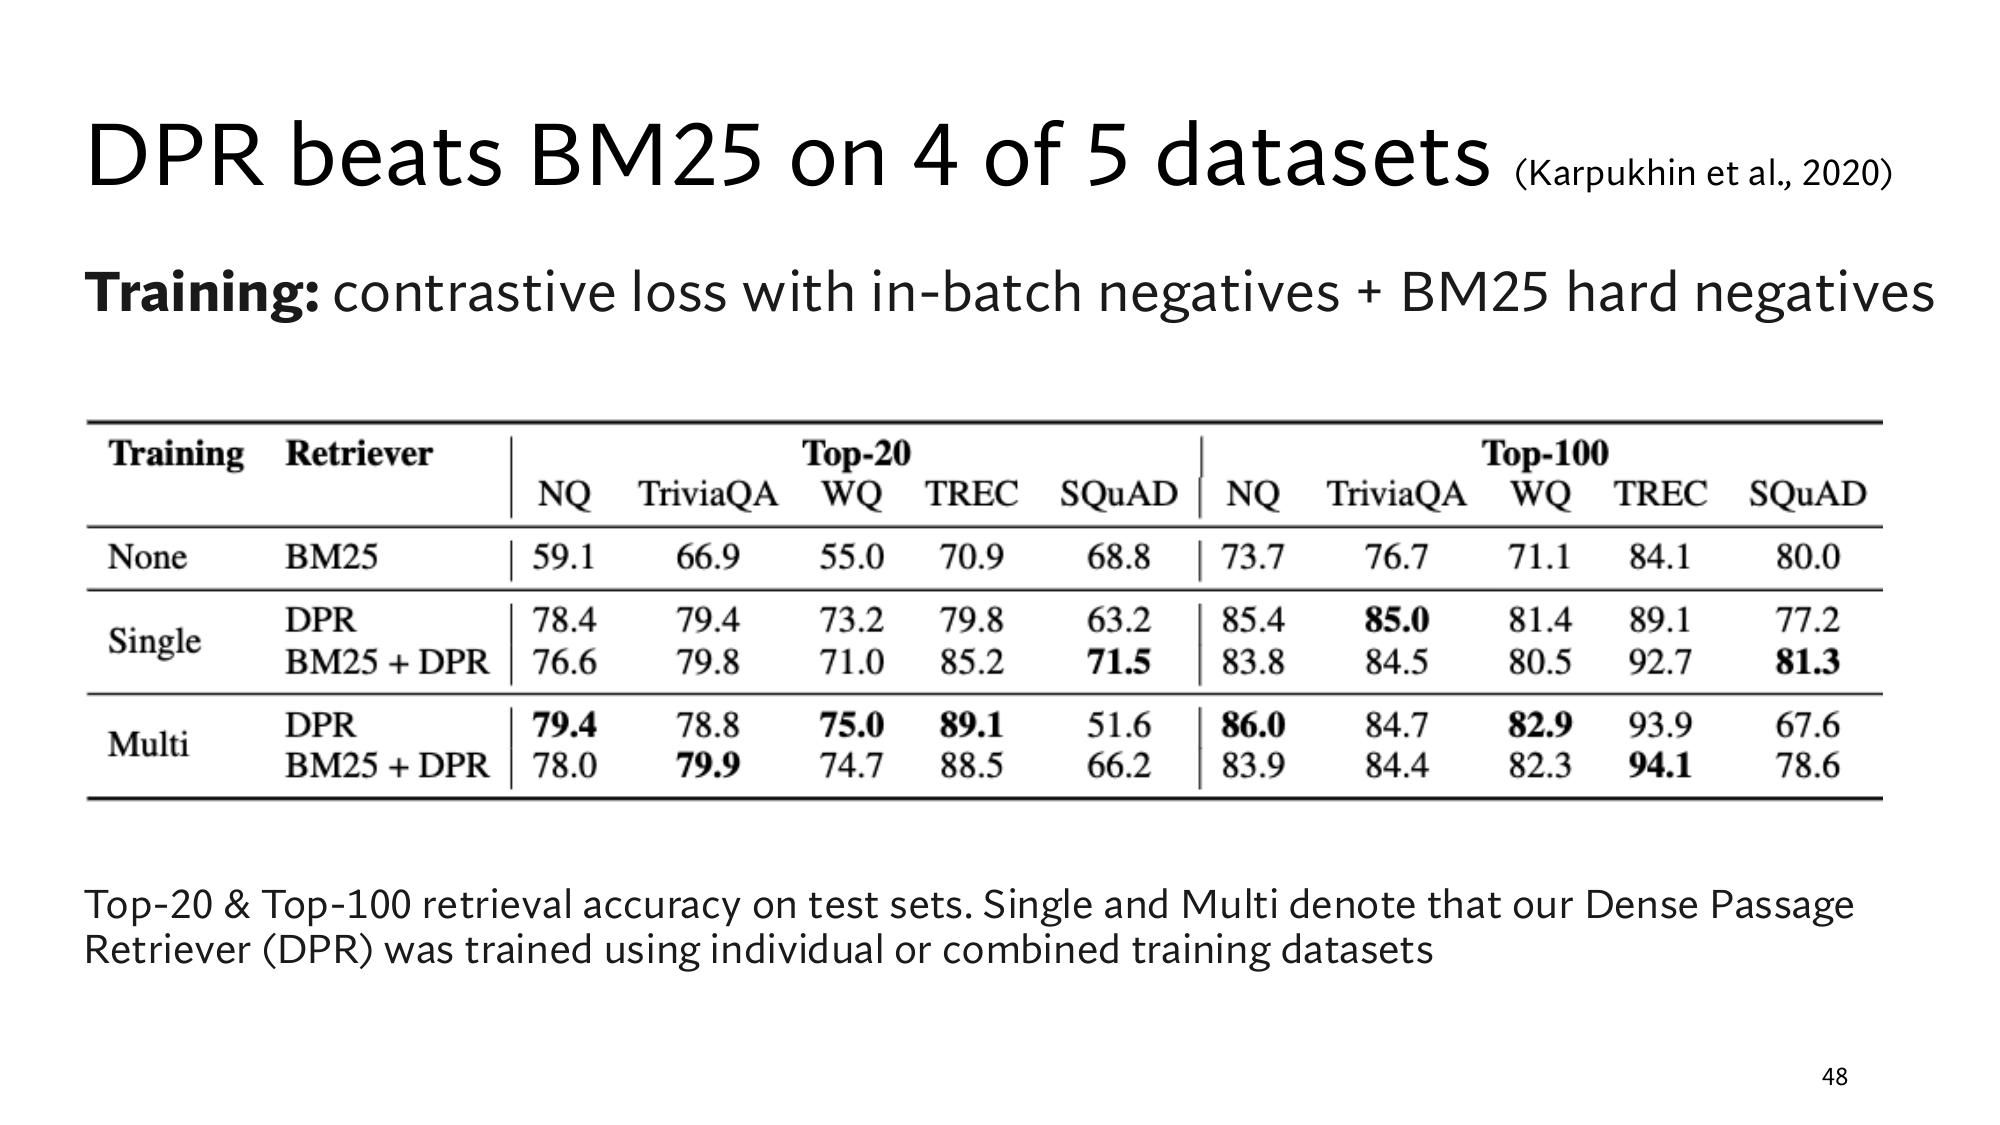
Stanford's results slide, and below it the table, enlarged.
Read the results slide
On which dataset is DPR behind BM25 at top-20, and why?
Show the answer
On SQuAD, 63.2 against 68.8. There people wrote the questions after reading the passage, so the questions reuse the passage's words, and that favours BM25. (Step 4)
On NQ, how big is the gap between BM25 and DPR at top-20, and at top-100?
Show the answer
At top-20 it is 78.4 − 59.1 = 19.3, and at top-100 it is 85.4 − 73.7 = 11.7. The gap shrinks as k grows, because with 100 passages BM25 also often finds the right one. (Steps 4 and 8)
What do Single and Multi mean? Why does the Multi DPR drop to 51.6 on SQuAD?
Show the answer
In Single, DPR was trained separately on each dataset. In Multi, one DPR was trained on all the datasets combined, but the paper left SQuAD out. So the Multi DPR was never trained on SQuAD questions. from the paper
Stanford's training-data slide, and below it the graph and the table, enlarged.
Read the training-data slide
In the graph, the blue line is BM25, and the orange line is DPR with only 1,000 pairs. Where is orange above blue, and what happens at k = 100?
Show the answer
At small k the orange line is clearly above. The gap shrinks as k grows, and at k = 100 the two are almost equal. The lines with more pairs sit higher at every k. (Step 4)
What is the 41.5 next to DPR in the table? And why does the comparison with ORQA and REALM matter?
Show the answer
41.5 is the full system's Exact Match on NQ, the percentage of answers that came out exactly right. ORQA and REALM used extra pretraining for the retriever, and DPR did not. DPR is still ahead of them. That is what the slide's line No extra pretraining says. (Step 8)
The slide says DPR beats REALM. Is that true in every column of the table?
Show the answer
No. On TREC the Single DPR is at 25.9, while REALMWiki is at 46.8. TREC is the smallest dataset, so a DPR trained on it alone had few pairs. The Multi DPR, trained on all the datasets together, reaches 49.4 on TREC. The slide's headline rests on the NQ numbers. from the paper
The other rows in the table, such as HardEM and GraphRetriever, are other systems. Their names are not needed for this lesson.
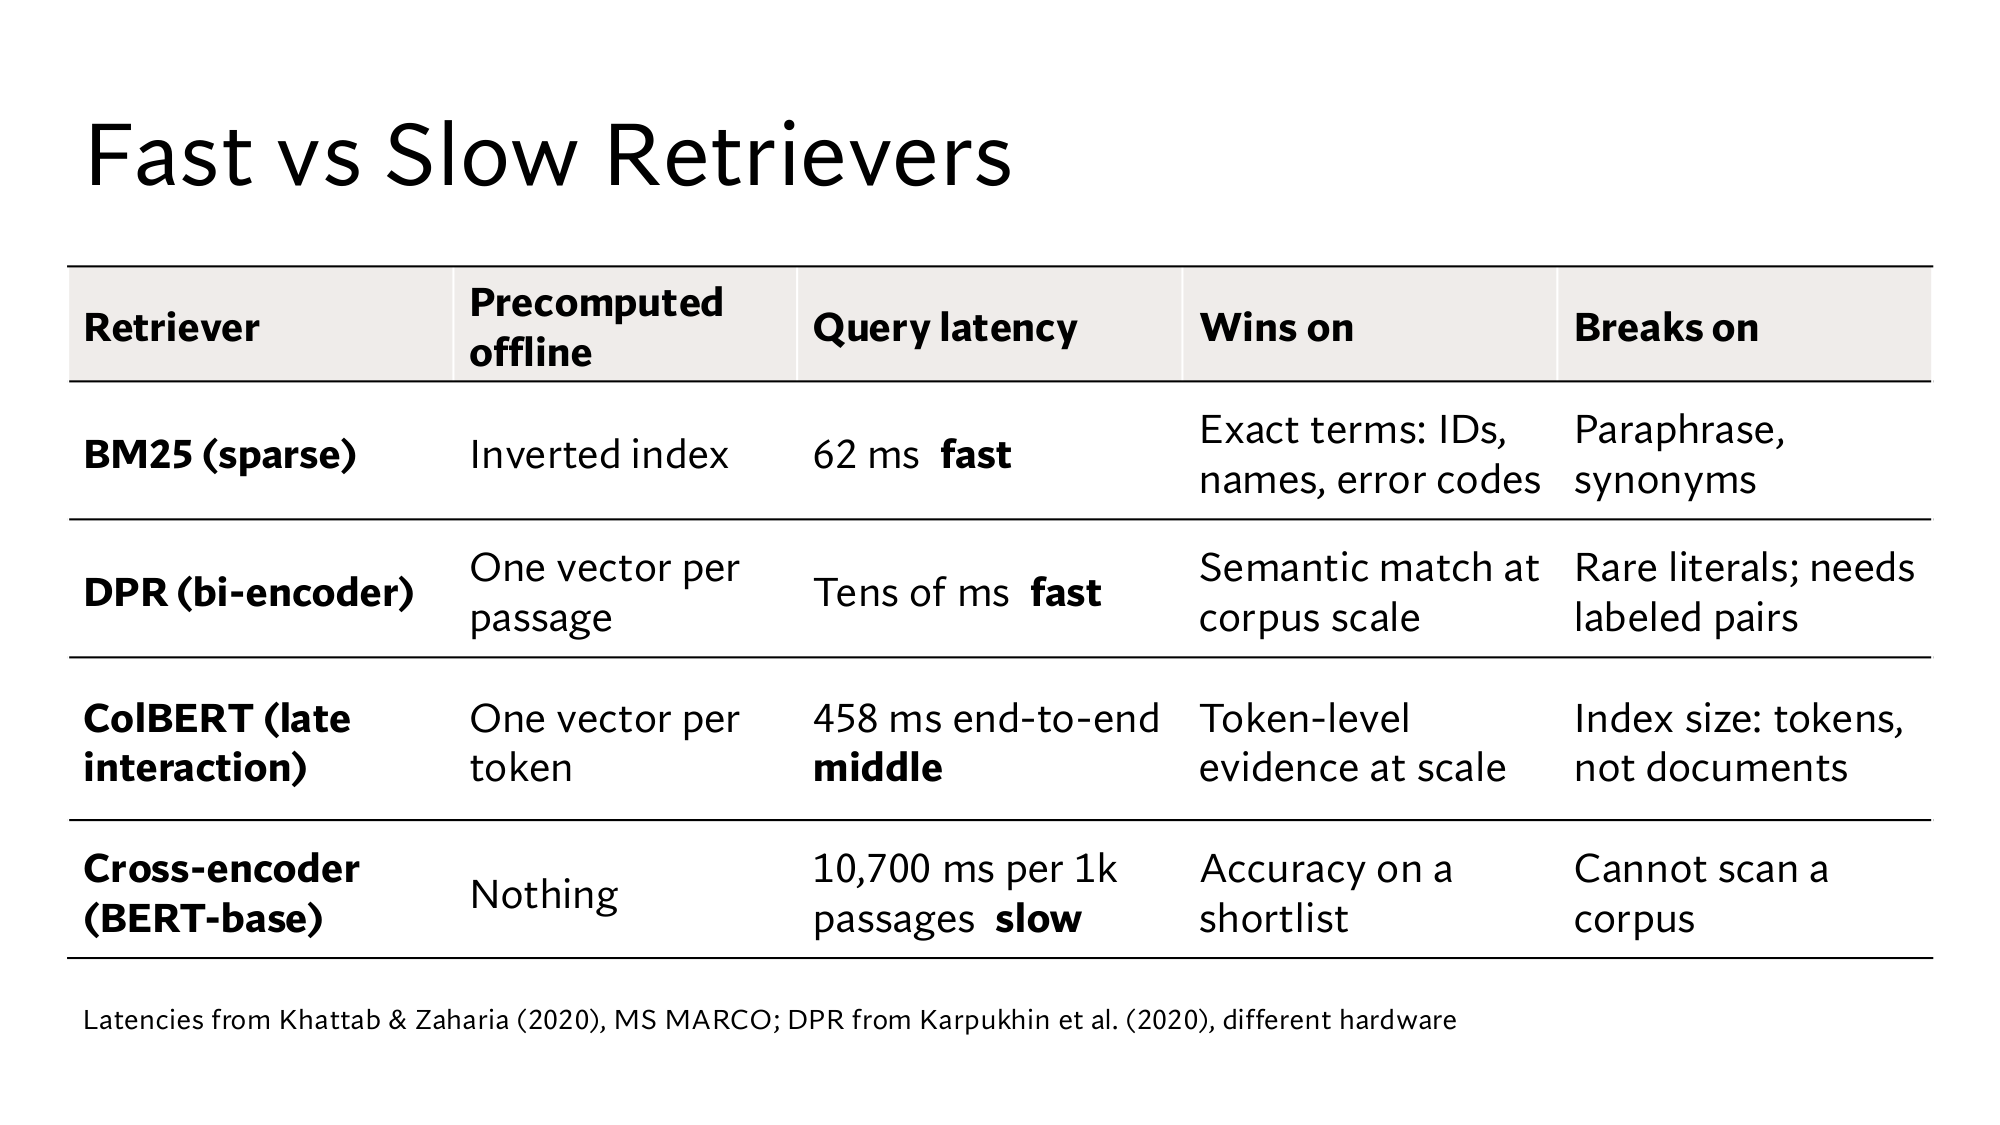
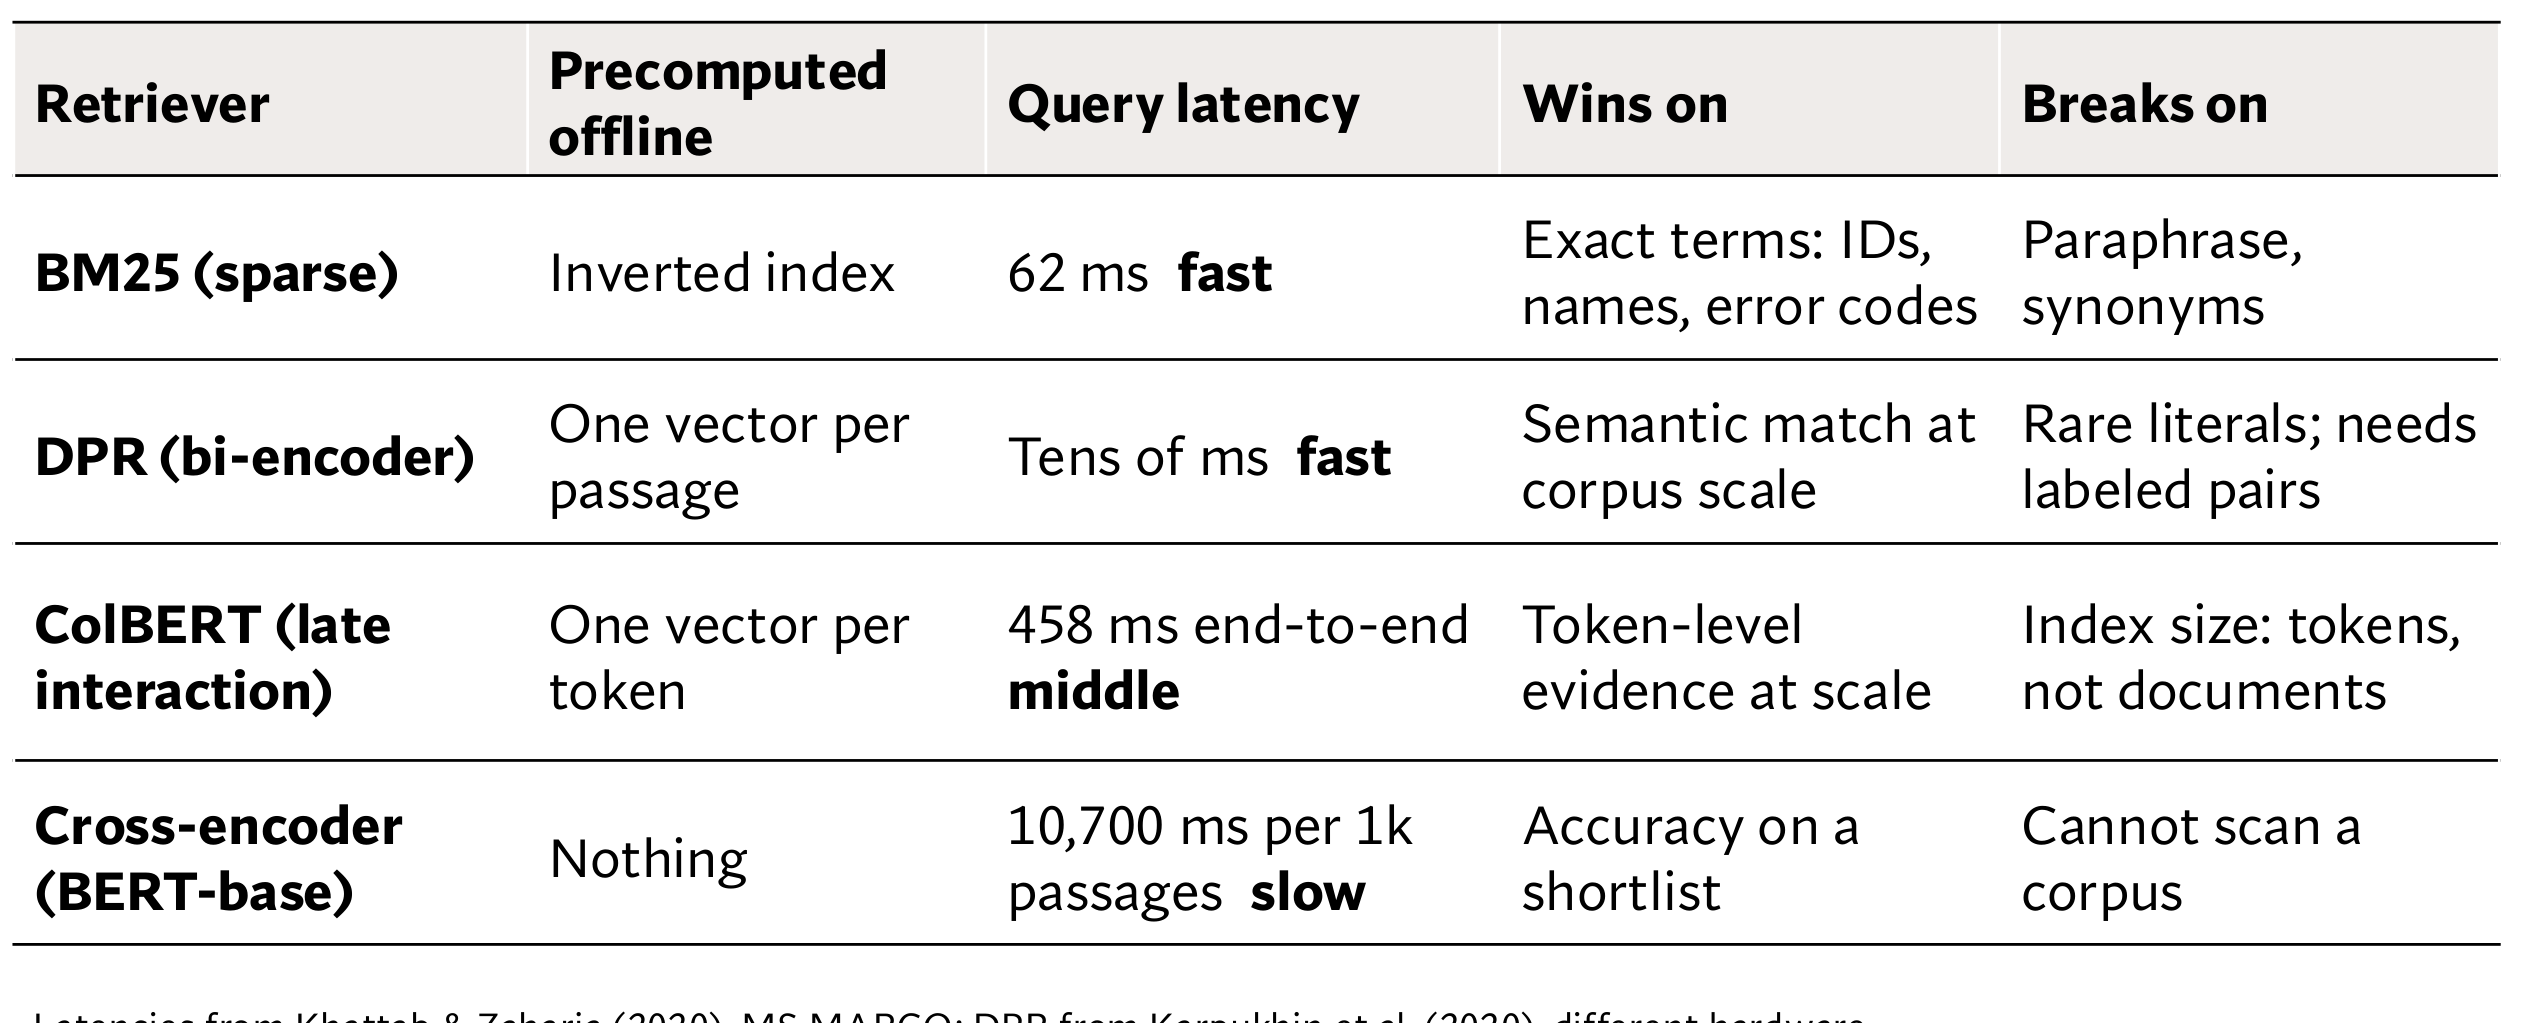
Stanford's comparison slide: four retrievers, and below it the table, enlarged. The ColBERT and cross-encoder rows come in lessons 14 and 15.
Read the comparison slide
What does “Precomputed offline: One vector per passage” mean in DPR's row?
Show the answer
Before any question arrives, the passage encoder makes one vector per passage and stores it in the index. When a question arrives, only the question encoder runs. (Step 1)
The cross-encoder takes 10,700 ms per 1,000 passages, and DPR takes tens of ms. Why such a gap?
Show the answer
A cross-encoder reads the question and the passage together, so it has to run the model once for every passage, and nothing can be prepared in advance. In DPR the model runs once per question, and the rest is dot products. The note under the slide says these numbers were measured on different hardware, so look only at the rough difference. (Step 1)
DPR's row says “Breaks on: Rare literals; needs labeled pairs”. Which step covered these two points?
Show the answer
Step 5. A rare code like error 4012 gets lost in DPR's vector, and training needs labeled question-passage pairs, even if only 1,000.
3 points from this lesson
DPR is a bi-encoder: two BERT encoders, with the score as the dot product of their vectors. Passage vectors are built offline into an index, so the question encoder runs only once per question.
Contrastive loss compares the positive's score with the negatives: softmax, then −ln. The loss's rate for each negative is its softmax share, so hard negatives teach the most.
A whole batch's scores come from one matrix product S = QP⊤, and one BM25 negative lifts top-20 from 73.0 to 78.0. Without extra pretraining, DPR beats BM25 on 4 of 5 datasets, but BM25 can still win on questions that hinge on exact words.
New terms in this lesson
DPR
Dense Passage Retrieval: a bi-encoder retriever with two BERT encoders, trained with contrastive loss on question-passage pairs. Built by Karpukhin and colleagues in 2020, and the retriever inside lesson 5's RAG.
Bi-encoder
Two separate encoders for the question and the passage, with the score as their dot product. Passages are encoded in advance. For example, even with 21 million passages the model runs once per question.
Pretraining
A model's first, large training on lots of general text. For example, BERT is first trained on general text.
Fine-tuning
Training an already trained model further on data for your own task. For example, DPR trains BERT on question-passage pairs.
Positive and negative passage
The question's correct passage (pi+), and wrong passages (pi,j−). For example, the least-crowded question's positive is the queue log, and its negatives are the forum post and the Homework announcement.
Contrastive loss
Softmax over the positive and negative scores, then −ln of the positive's share. It looks only at differences between scores. For example, scores 1.0, 2.0, 1.5 give loss 1.68, and 5.0, 2.0, 0.5 give 0.059.
Batch
A group of questions that training processes together. For example, a batch of 128 questions in DPR.
In-batch negatives
Using the positives of the other questions in the batch as negatives. For example, in a batch of 128 each question gets 127 negatives.
Hard negative
A wrong passage that looks similar to the question. DPR takes these from BM25's top passages. For example, the forum post for our question.
∂ (partial derivative)
How fast an output changes when one input changes a little and everything else stays the same. For example, ∂𝓛/∂s+ = −0.814: raise the queue log's score by 0.01 and the loss falls by about 0.008.
Chain rule (for rates)
Rates that are linked one after another multiply. For example, the rate of ln Z with respect to the queue log's score is 2.72 × (1 ÷ 14.59) = 0.186. Lesson 4's probability chain rule is a different rule.
ℝd
A list of d real numbers, that is, a vector with d dimensions. For example, [1.0, 0.5, 0.5, 1.0] ∈ ℝ4, and DPR's vectors are in ℝ768.
∇ (nabla)
∇θ𝓛: the loss's rate for every parameter in θ, as one list. Training nudges each parameter a little against its rate. For example, on the three scores these rates were −0.814, +0.506 and +0.307.
FAISS
An open-source library for fast search over vectors. For example, DPR built an HNSW index over 21 million vectors in it, which took about 8.5 hours.
ORQA
A 2019 dense retriever that trained its retriever with extra pretraining. For example, on NQ the full system's Exact Match is 33.3 with ORQA and 41.5 with DPR.
Top-k retrieval accuracy
The percentage of questions with an answer passage in the top k. For example, DPR's 78.4% on NQ at top-20.