Chunking: cutting documents into pieces for retrieval
Chunking means cutting a long document into small pieces, so that the retriever can make one vector per piece and store it in the index. These pieces are called chunks. The retriever searches for chunks and returns chunks, which is why Stanford's slide calls the chunk the basic unit of retrieval.
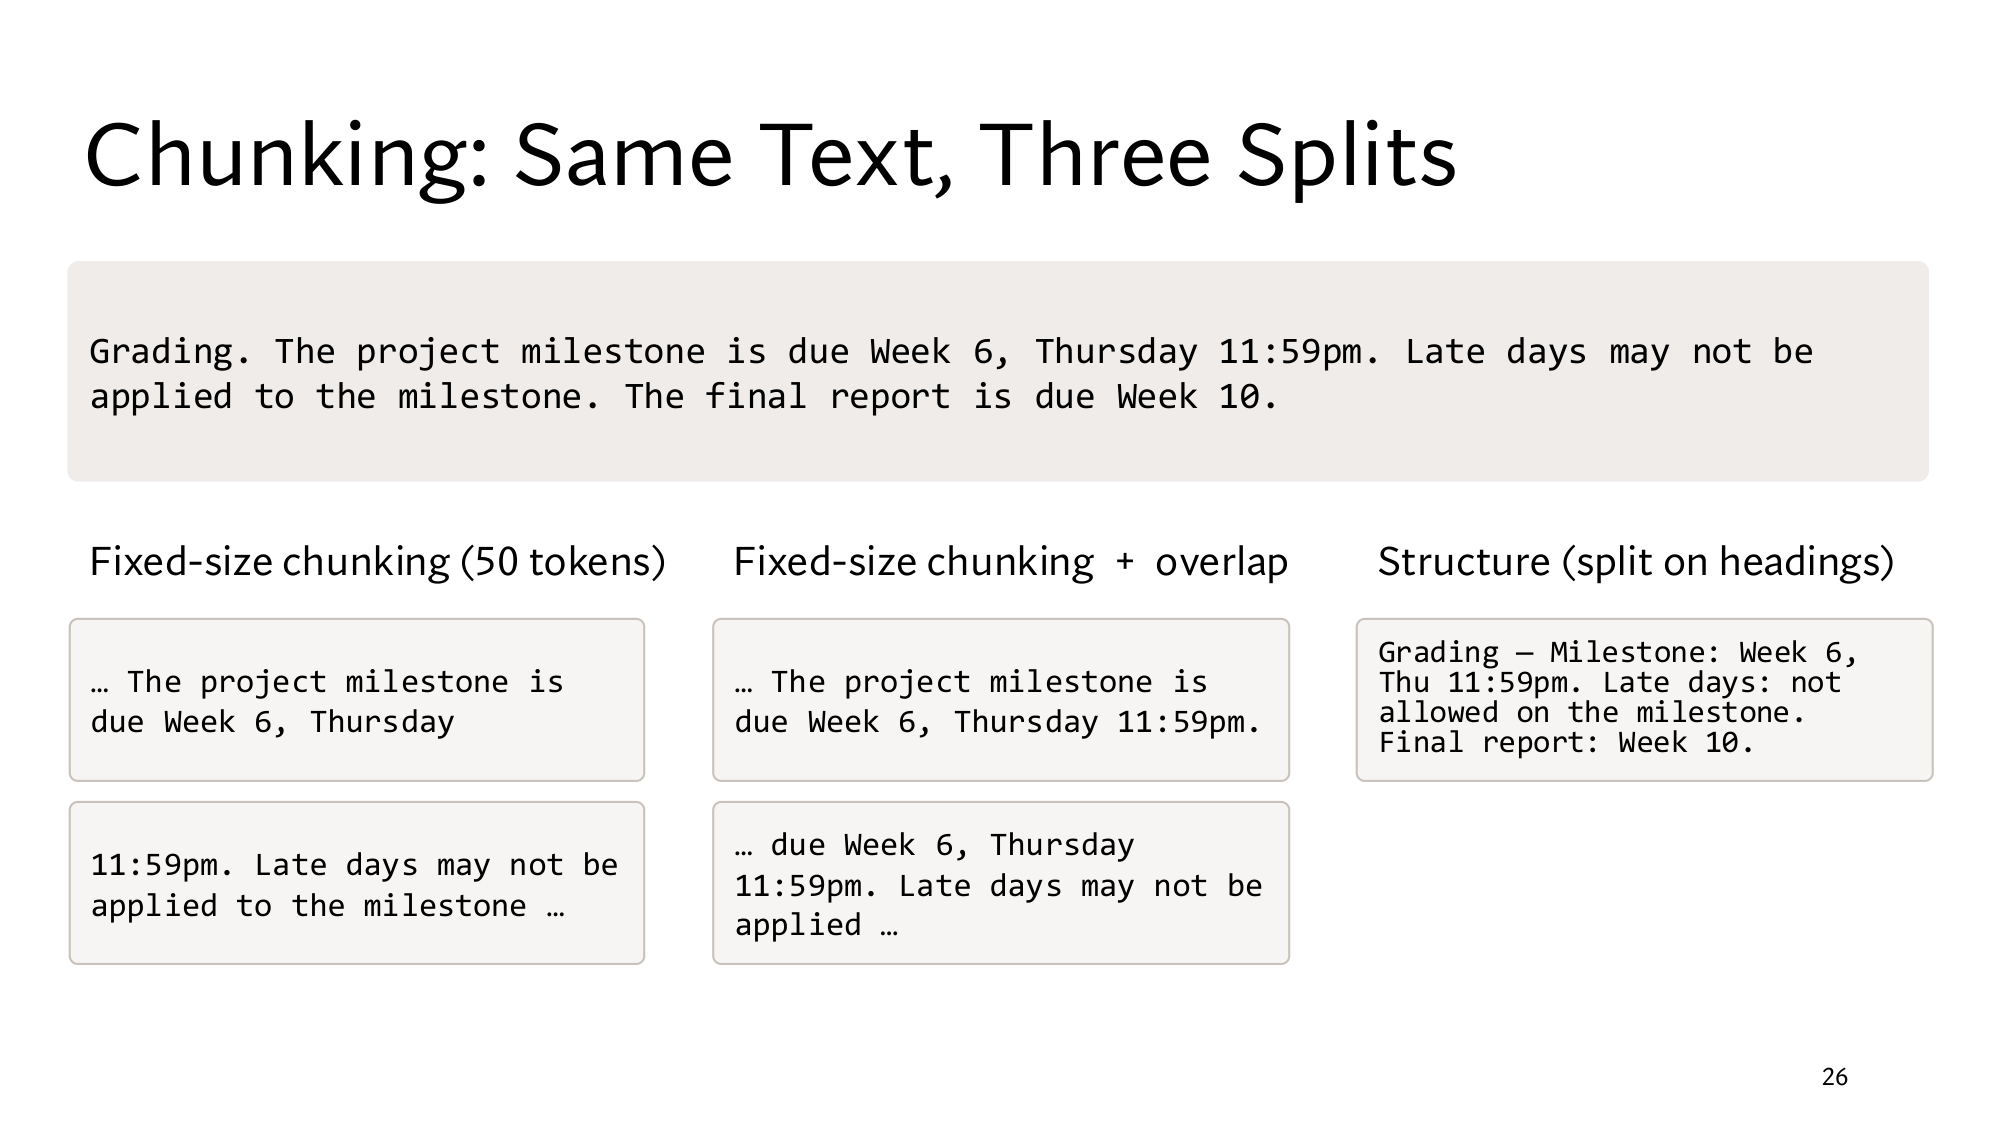
In lesson 2, the answer to when is the project milestone due was in the syllabus passage: Week 6, Thursday 11:59pm. That passage came to us already cut, but the real syllabus is 40 pages long. In the pipeline of lesson 6, cutting it is the first step of building the index. Cut it every 50 tokens, and one chunk ends at …due Week 6, Thursday while 11:59pm. lands in the next chunk. Do not cut it at all, and the milestone's 2 lines dissolve into a single vector for 40 pages.
The ladder for this lesson
The ladder has 4 steps. Under each step you can see what you will be able to do after it.
What you need first: Lesson 1 (token), Lesson 3 (vector, embedding, cosine) and Lesson 6 (indexing time). If you already know a step, skip to the next one. A word with a dotted underline and ▾ opens its definition when you click it.
1A chunk's vector: the average of its token vectors
Retrieval needs one vector per chunk, and that vector is often the average of the vectors of all the chunk's tokens. The index stores this one vector for each chunk. When a question arrives, the retriever computes the between the question's vector and every chunk's vector, and returns the chunks with the largest cosines. The six passages of lesson 2 were really chunks too.
First, look at where the token vectors come from. An makes a separate vector for every , and the surrounding words affect that vector too. This is called a contextual embedding.
Take the word late, which appears in two sentences: Late days may not be applied and late afternoon office hours. Suppose the first number of a vector stands for office hours and the second for deadlines. A contextual embedding then gives late two different vectors. Older static word embeddings, such as word2vec, kept one vector per word type. A word type is a word as it appears in the dictionary, whatever sentence it is in. my numbers
Sentence
Static: vector for late
Contextual: vector for late
Late days may not be applied
[0.5, 0.5]
[0.1, 0.9]
late afternoon office hours
[0.5, 0.5]
[0.9, 0.1]
Now we need one vector for the whole chunk, which is called a passage embedding. The most common way is to average all the chunk's token vectors: add up the numbers in each column and divide by the number of tokens. This is called mean pooling. Take a small chunk of three tokens: my example
Token
Vector
Office
[0.9, 0.1]
hours
[0.7, 0.3]
Tuesday
[0.8, 0.2]
Mean pooling: the average of each column
[0.8, 0.2]
First column: 0.9 + 0.7 + 0.8 = 2.4, and 2.4 ÷ 3 = 0.8.
Second column: 0.1 + 0.3 + 0.2 = 0.6, and 0.6 ÷ 3 = 0.2.
All three tokens leaned towards office hours, so the chunk's vector [0.8, 0.2] leans the same way. Mean pooling gives every token the same weight, and in step 2 this is exactly what hurts a large chunk.
Think first
Add one more token to the chunk: 4pm, with the vector [0.8, 0.2]. What is the chunk's vector now, and how many numbers does it have?
Show the answer
[0.8, 0.2], and it still has 2 numbers. First column: (0.9 + 0.7 + 0.8 + 0.8) ÷ 4 = 3.2 ÷ 4 = 0.8. Second: (0.1 + 0.3 + 0.2 + 0.2) ÷ 4 = 0.8 ÷ 4 = 0.2. Whether a chunk has 3 tokens or 300, the average has as many numbers as each token vector. So every chunk's vector has the same count of numbers, and the index can compare them all.
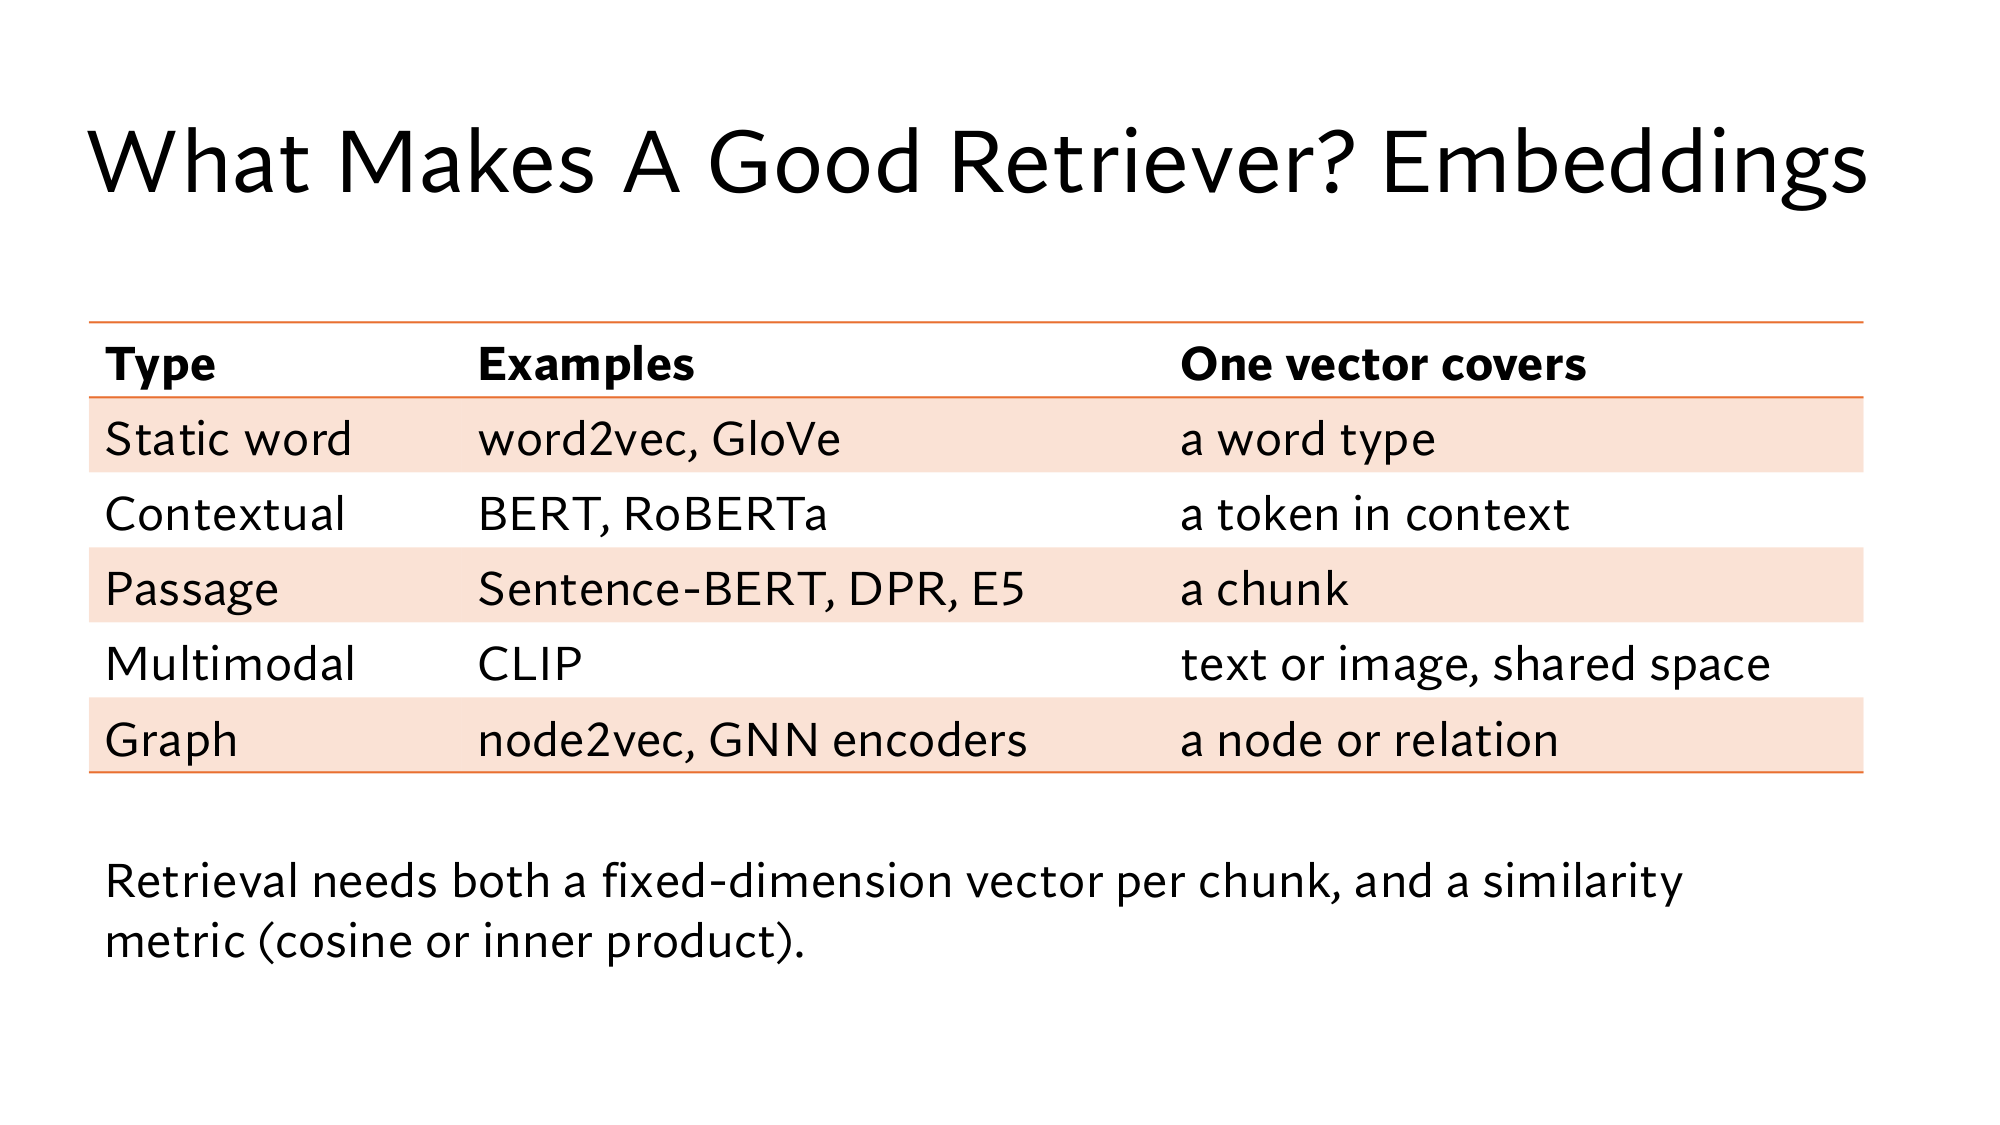
Stanford's embeddings slide makes the same point. Its table lists five kinds of embeddings, and you have just met the top three: static word, contextual and passage. The other two, and , are vectors for images and for networks. The slide's last line names two things retrieval needs. The first is one vector per chunk, with a fixed . The second is a way to compare vectors, cosine or inner product.
Stanford's slide: What Makes A Good Retriever? Embeddings. In the passage row, one vector covers one chunk, and this lesson is about that chunk. Click the image to open it at full size.
2Chunk size: small loses context, large gets averaged away
A large chunk becomes the average of many topics, and a small chunk loses its context. So choosing a chunk size means choosing between two opposite problems, and Stanford's slide lists both.
A large chunk: topics get averaged together
Suppose the office hours topic has the vector [1, 0] and the deadline topic has [0, 1]. If a large chunk holds both topics in equal parts, mean pooling gives [0.5, 0.5]. The query office hours has the vector [1, 0]. my example
The cosine from lesson 3 is the dot product of two vectors divided by the product of their . A small chunk about office hours only, [1, 0], has cosine 1 with the query, because the two point in the same direction. The large chunk's cosine takes three steps:
Dot product: 1 × 0.5 + 0 × 0.5 = 0.5.
Lengths: the query's length is 1, and the length of [0.5, 0.5] is √(0.5² + 0.5²) = √0.5 = 0.707. The square root √ is the number that gives the number inside when multiplied by itself. Check: 0.707 × 0.707 = 0.5.
Cosine: 0.5 ÷ (1 × 0.707) = 0.71.
Chunk
Vector
Cosine with the query
Small chunk, office hours only
[1, 0]
1.00
Large chunk, office hours and deadlines
[0.5, 0.5]
0.71
The large chunk does contain the right fact, yet its cosine fell from 1.00 to 0.71, because the deadline topic was mixed into the average. Any other chunk with a cosine of 0.8 now ranks above it. The 40-page syllabus covers office hours, deadlines, grading and the project, so there the cosine falls even further.
Think first
A chunk holds three topics in equal parts: [1, 0, 0], [0, 1, 0] and [0, 0, 1]. What vector does mean pooling give, and what is its cosine with the query [1, 0, 0]?
Show the answer
The average is [1/3, 1/3, 1/3], and its dot product with the query is 1/3. Its length is √(3 × 1/9) = √(1/3) = 0.577. Cosine = (1/3) ÷ (1 × 0.577) = 0.58. Two topics gave 0.71 and three give 0.58, so the more topics, the lower the cosine.
A small chunk: the context is left behind
Now go the other way and make very small chunks. The queue log has 19 words, and cutting it into chunks of 5 words gives these 4 chunks:
Chunk 1 · 5 words
Queue log, last 3 weeks:
Chunk 2 · 5 words
Tuesday 4pm office hour averaged
Chunk 3 · 5 words
14 students waiting; Thursday 9am
Chunk 4 · 4 words
office hour averaged 3.
The fourth chunk has the 3, but it does not say which day's office hour that is. Thursday 9am went into the third chunk, so the fourth chunk's vector does not know it either. The answer to lesson 2's question, which office hour is least crowded, is no longer complete in any single chunk.
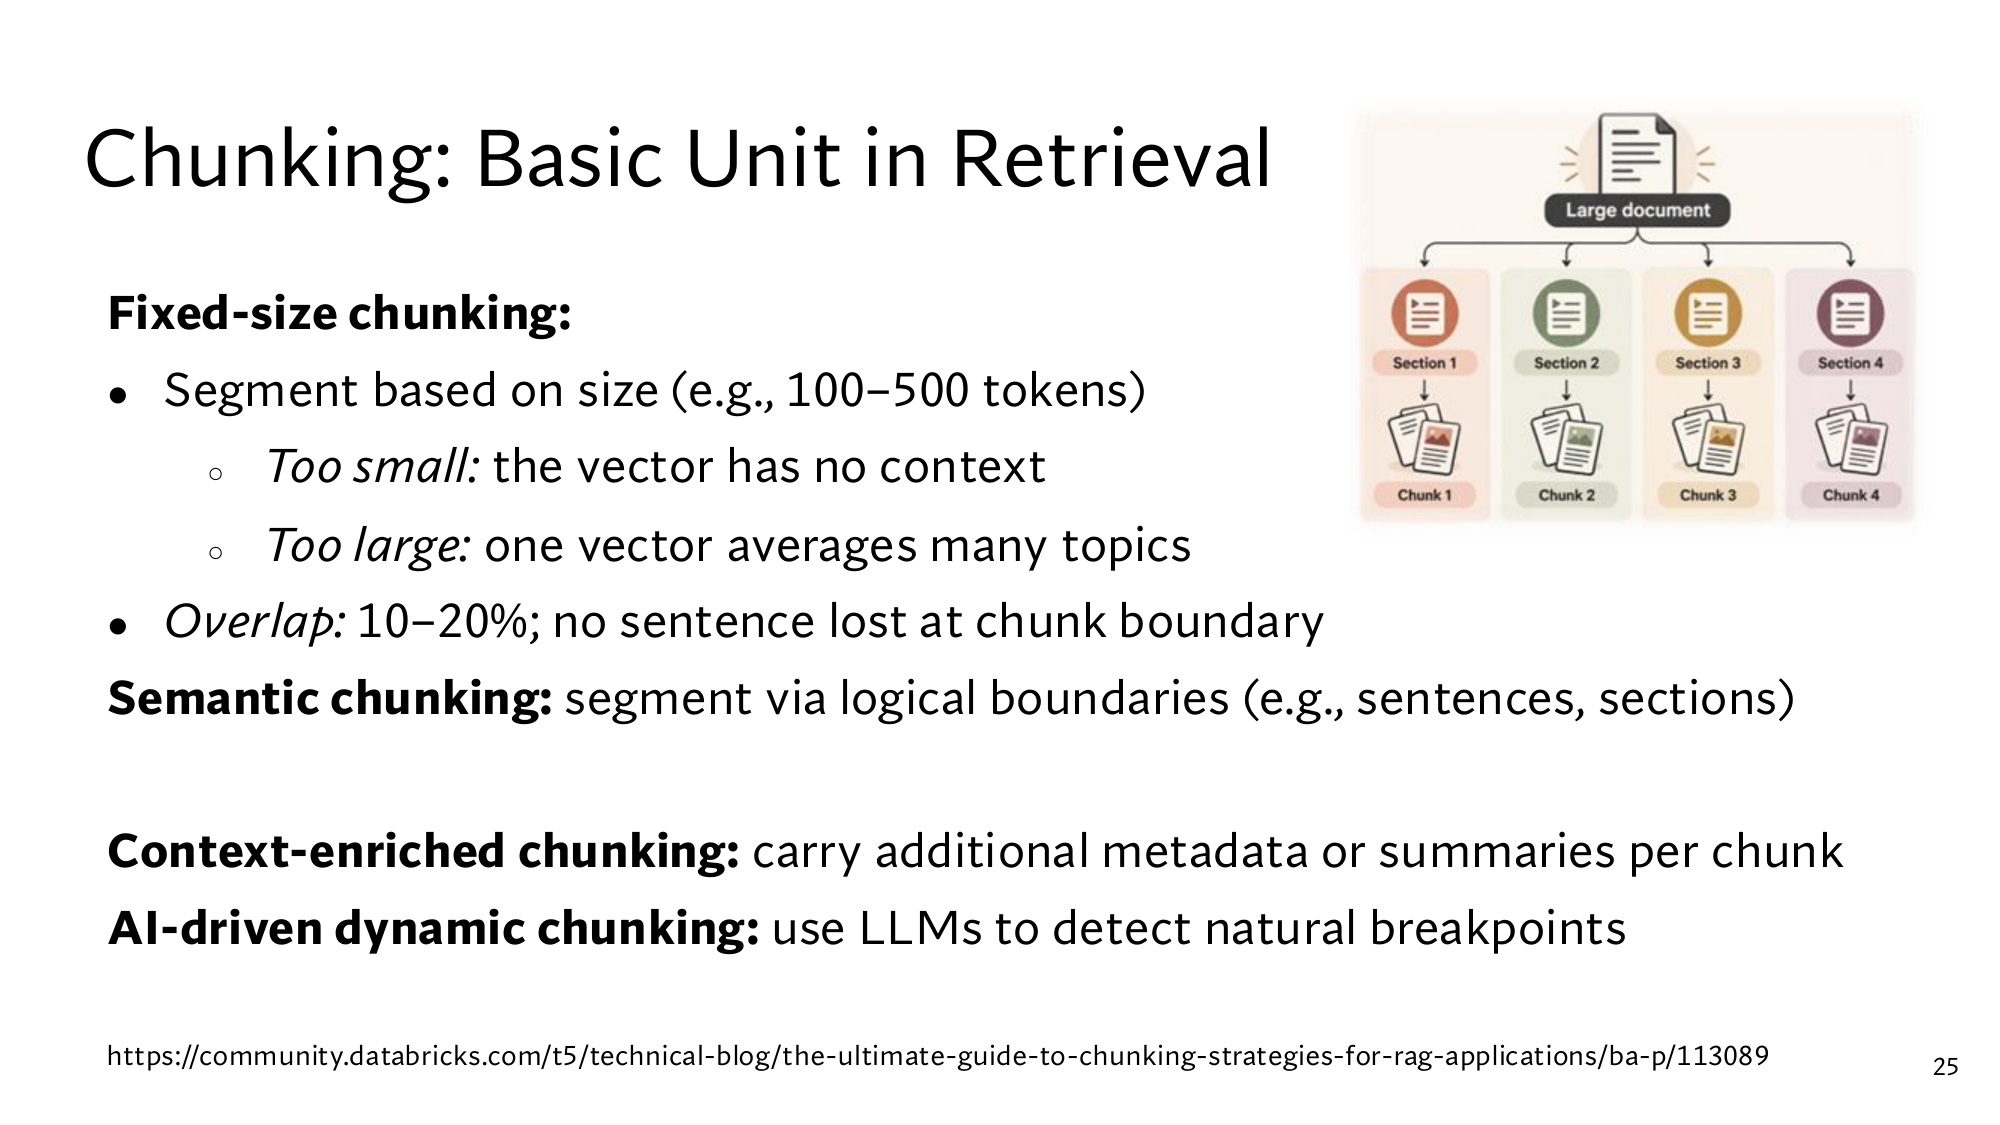
Fixed-size chunking takes the middle road: every chunk gets a fixed number of tokens. Stanford's slide gives 100 to 500 tokens as an example.
Small chunks are good for precise questions, but they lose their context. Large chunks get more context, but their one vector becomes the average of many topics. Lesson 8 gives a small chunk its lost context back, and lesson 9 builds a layer of summaries above the chunks for broad questions.
3Overlap and stride: saving a fact cut at a boundary
With overlap, every new chunk starts by repeating the last few tokens of the previous chunk, so that a fact cut at a boundary survives whole. You need it because whatever size you choose, some fact will fall on a boundary. That is exactly how the milestone date was cut at 50 tokens. Stanford's slide recommends an overlap of 10 to 20%.
The distance between the starts of two neighbouring chunks is called the stride: stride = chunk size − overlap. With chunk size 9 and overlap 6 the stride is 3, so chunks start at words 0, 3, 6, 9, ….
Now cut the beginning of the syllabus in the widget below. Treat every word as one token, and count from 0. The milestone fact, milestone is due Week 6, Thursday 11:59pm., is 7 words long and sits at words 3 to 9 of the syllabus. With chunk size 9 and overlap 0, the first chunk covers words 0 to 8, so 11:59pm. falls outside it.
Think first
Keep the chunk size at 9 and raise the overlap from 0 to 6. At what overlap does the date first appear whole in a single chunk? Guess first, then check in the widget.
Show the answer
Only at overlap 6. The stride is then 3, and the second chunk runs from word 3 to word 11, which holds the whole date. With overlap 1 to 5, no chunk starts at word 3 or earlier and still reaches word 9.
Cut the syllabus into chunks
The underlined fact, the milestone date, should be whole inside one chunk. Words with a light background are overlap.
How much overlap is enough
You can count out why it has to be 6. A chunk of 9 words holds the fact at words 3 to 9 only if it starts at word 1, 2 or 3. Chunks start at 0, stride, 2 × stride, …, and a start is certain to land on one of those 3 positions only if the stride is 3 or less. With stride 4 the starts are 0, 4, 8, which miss 1, 2 and 3 altogether. The stride is 9 − overlap, so the overlap must be at least 6.
The same count works for any size. With chunk size C and a fact of L words, there are C − L + 1 good starting positions for a chunk. Here that was 9 − 7 + 1 = 3. If the stride, which is C − overlap, is no larger than that, you get this rule: this rule is not on the slide, it follows from counting
overlap ≥ L − 1, and chunk size ≥ L
Here L = 7, so the overlap must be at least 6. If the chunk is shorter than the fact, no overlap can bring the fact into one chunk.
Think first
Set the widget to chunk size 10 and overlap 0. The date shows up whole. Is that a reliable defence?
Show the answer
No, that is luck. The first chunk covers words 0 to 9, and the date ends exactly at word 9. With one more word at the start of the syllabus, 11:59pm. would sit at word 10 and fall into the next chunk. An overlap of L − 1 protects the fact wherever it sits.
What overlap costs
Overlap is not free, because the repeated tokens go into two chunks. Cut a document of 1,000 tokens into chunks of 50 tokens, and without overlap you get 1,000 ÷ 50 = 20 chunks. With an overlap of 10 tokens, which is 20%, the stride is 40. Chunks then start at tokens 0, 40, …, 960, because the chunk starting at 960 already reaches the end of the document. That makes 960 ÷ 40 + 1 = 25 chunks.
So 20% overlap means 25% more embeddings to compute and store in the index.
4Cutting by meaning: headings, metadata and LLMs
Semantic chunking cuts the text where the text already divides itself, such as at the end of a sentence or a section. You need it because fixed-size chunking cuts by count and ignores the text's structure. Set the widget to chunk size 20 and overlap 0. The second chunk starts with final report is due Week 10. and runs on into the office hours part, so one chunk holds two topics.
Each part of the syllabus has its own heading: Grading, Office hours and Project. Splitting on headings is the simplest form of semantic chunking. Press Split on headings in the widget. The syllabus splits into 3 chunks of 26, 16 and 12 words, and each chunk is about one topic. The chunks are no longer the same size, and that is the price of this method.
A small chunk can still lose its context. Late days may not be applied to the milestone. does not say on its own which course it belongs to. Context-enriched chunking handles this by storing extra information with every chunk, such as metadata or a short summary.
Metadata is data about data: the document's name, the section and the date. A context-enriched chunk could look like this: my example
[Source: CS 329Z syllabus, section: Grading, updated: 30 Sep 2026] Late days may not be applied to the milestone.
Now even the small chunk says which course and which section it comes from. Lesson 8 shows the most effective form of this idea, where an LLM writes context for every chunk.
The last method is AI-driven dynamic chunking. It asks an LLM where the topic changes in the text, and cuts there. It works even without headings. But every document has to pass through the LLM once, which costs time and money.
Method
Benefit
Cost
Fixed-size
Simple, every chunk the same size
A fact can break in the middle
Fixed-size + overlap
A broken fact is whole in the next chunk
More chunks, repeated text
Semantic, such as headings
Each chunk is about one topic
Chunk sizes vary
Context-enriched
Even a small chunk carries its context
Metadata or summaries must be made
AI-driven
Meaningful boundaries even without headings
LLM calls for every document, slow and expensive
Now go back to the opening problem. Splitting on headings puts the whole milestone date into the Grading chunk, and that chunk is about a single topic. So the broken date and the averaged-away vector are both solved at once for this document. Not every document has clean headings, which is why the other methods are useful too.
You can now read both of Stanford's chunking slides. The first lists all four methods, and the second cuts our syllabus in three ways.
Stanford's slide: Chunking: Basic Unit in Retrieval. At the top are fixed-size chunking and overlap (steps 2 and 3), and below them the other three methods (step 4).Stanford's slide: Chunking: Same Text, Three Splits. Our syllabus is at the top. Below it, on the left, is the date broken at 50 tokens, in the middle the date saved by overlap, and on the right a chunk split on headings and rewritten more tidily.
What the dense version adds
The dense version contains this whole lesson, followed by 4 more steps that take you to the level of the Stanford slides:
Step 5: the maths of mean pooling. Cosine 1/√k for k equal topics, and how a fact with a small share gets diluted.
Step 6: the full arithmetic of overlap. The chance that a fact survives too little overlap, the slide's 10 to 20% advice, and a formula for counting chunks.
Step 7: the methods from the inside. The Databricks guide's sizes, recursive splitting, finding boundaries with sentence vectors, and the cost of LLM chunking.
Step 8: Stanford's three slides, which you read yourself.
Retrieval needs one vector per chunk, and it is often the average of the contextual token vectors, which is mean pooling. However many tokens there are, the vector keeps the same count of numbers.
A small chunk loses context, and a large chunk becomes an average of many topics and lowers the cosine, for example from 1.00 to 0.71.
To keep a fact of L tokens whole, the overlap must be at least L − 1, for example 6 for a 7-word date. Splitting on headings does not break the fact at all, and metadata gives a small chunk its context.
New terms in this lesson
Word type and token in context
A word as listed in the dictionary, and one use of it in a sentence. For example, late is a word type, and its use in Late days may not be applied is a token in context.
Static word embedding
One vector per word type, whatever the context. For example, word2vec and GloVe. The vector for late stays [0.5, 0.5] in both sentences. my numbers
Contextual embedding
A separate vector for each token, shaped by its sentence. For example, BERT. In Late days may not be applied late is [0.1, 0.9], and in late afternoon office hours it is [0.9, 0.1]. my numbers
Passage embedding
One vector for a whole chunk, the kind the retrieval index stores. For example, the vectors from Sentence-BERT, DPR and E5.
Multimodal embedding
Vectors for text and for images in the same space. For example, CLIP. A photo of office hours written on a whiteboard and the text office hours schedule can get nearby vectors.
Graph embedding
A vector for a node or a relation in a network. For example, node2vec. In a course graph: the TA, office hours, and the runs relation between them.
Mean pooling
Making one vector by averaging several token vectors. For example, the average of [0.9, 0.1], [0.7, 0.3] and [0.8, 0.2] is [0.8, 0.2].
Chunk
A piece of a document made for retrieval, and the basic unit of retrieval. For example, the Grading part of the 40-page syllabus.
Fixed-size chunking
Cutting at a fixed number of tokens, even if a fact breaks in the middle. For example, every 50 tokens.
Overlap
A new chunk starts by repeating the last few tokens of the previous one. To keep a fact of L tokens whole, it must be at least L − 1. For example, 6 for a 7-word date.
Stride
The distance between the starts of two neighbouring chunks: chunk size − overlap. For example, 9 − 6 = 3.
Semantic chunking
Cutting at logical boundaries such as sentences or sections. For example, cutting the syllabus at its Grading, Office hours and Project headings.
Context-enriched chunking
Storing metadata or a summary with every chunk. For example, Source: CS 329Z syllabus, section: Grading above every chunk.
Metadata
Data about data: name, section, date. For example, CS 329Z syllabus, Grading, 30 Sep 2026.
AI-driven dynamic chunking
Asking an LLM where the topic changes in a text, and cutting there. It needs LLM calls for every document.