Measuring a retriever: Hit@k, MRR, Recall@k and nDCG
Measuring a retriever means looking at its lists for a set of queries and counting how many right passages came back, and how high they sit. First someone has to write down the right passages for every query, and then each metric turns the lists into one number.
Lesson 2 counted recall roughly. Now run a retriever on the same 3 queries. For the first query the right passage comes back at rank 1, for the second at rank 2, and for the third not at all. In the top 3, the right passage arrived for 2 of the 3 queries, which is 0.667.
Then you improve the retriever, and the second query's right passage moves up to rank 1. If only one passage goes into the prompt, that query can now be answered too. Yet the top-3 count stays stuck at 0.667. This lesson builds numbers that can see that change.
The ladder for this lesson
The ladder has 5 steps. Under each step you can see what you will be able to do after it.
MRR@kWork out the reciprocal rank, and show that MRR sees the improvement.
Recall@kWork out Recall@k, choose the right k, and read Stanford's MRR and Recall slide.
nDCG@kWork out nDCG by hand, read Stanford's other slide, and choose the right metric.
What you need first: Lesson 2 (the 6 passages of the corpus, top-K, recall, the recall ceiling), Lesson 3 (the ∑ sign) and Lesson 4 (ln). If you already know a step, skip to the next one. A word with a dotted underline and ▾ opens its definition when you click it.
1Relevance labels and sets: write down the right passages first
Relevance labels are a list in which a person writes down, for each query, which passages are right. A retriever cannot tell you whether its own list is right, so before you can measure it, someone has to read the passages and make this list. Each passage can also get a grade: 3 means very useful, 1 means a little useful, and 0 means not useful.
The whole lesson uses the same 3 over lesson 2's corpus. Suppose a returns 5 passages for each query, with each passage's grade in brackets. my retriever and grades
Query
The retriever's order (grade)
Right passages
q1: Least crowded office hour?
queue log (3), old forum post (0), office hours page (1), syllabus (0), project page (0)
syllabus (0), Homework 1 announcement (0), project page (0), old forum post (0), queue log (0)
office hours page, grade 2
q1 has two right passages. The queue log has the crowd data, and the office hours page says that the Thursday 9am office hour is on Zoom. The real answer is in the queue log, so it gets grade 3, and the office hours page gets 1. q3's right passage is nowhere in the retriever's list.
Sets: short names for the right passages
The metric formulas give these lists short names, and for that they use sets. A set is a group of things written inside { }, and the order inside it does not matter.
The set of right passages for query q is written Rq, for example Rq1 = {queue log, office hours page}. The set of the retriever's top k passages is Topk(q). This k is the same as lesson 2's , only written small in formulas. So Top3(q1) = {queue log, old forum post, office hours page}. Three more signs come with sets:
∩ gives the things that are in both sets. Rq1 ∩ Top3(q1) = {queue log, office hours page}, so both of q1's right passages are in the top 3.
∅ is the empty set, with nothing in it. For q3, {office hours page} ∩ {syllabus, Homework 1 announcement, project page} has nothing in common, so it is ∅.
|A| is how many things set A holds. |Rq1| = 2, and for the set Q of all queries, |Q| = 3.
Labels have a cost. A person has to read and decide the right passages for every query, which is expensive. If that person misses a right passage, a retriever that finds it still loses on every metric.
2Hit@k and Failed@k: did a right passage arrive?
Hit@k checks, for each query, whether the top k holds at least one right passage, and then averages over the queries. If it does, the query gets 1, otherwise 0. At k = 3, q1's top 3 holds the queue log and the office hours page, so 1. q2's top 3 holds the syllabus, so 1. q3's top 3 holds no right passage, so 0.
Add the three queries' numbers: 1 + 1 + 0 = 2.
Divide by the number of queries, which gives the average: 2 ÷ 3 = 0.667.
Hit@3 = 0.667, the number from the start of the lesson.
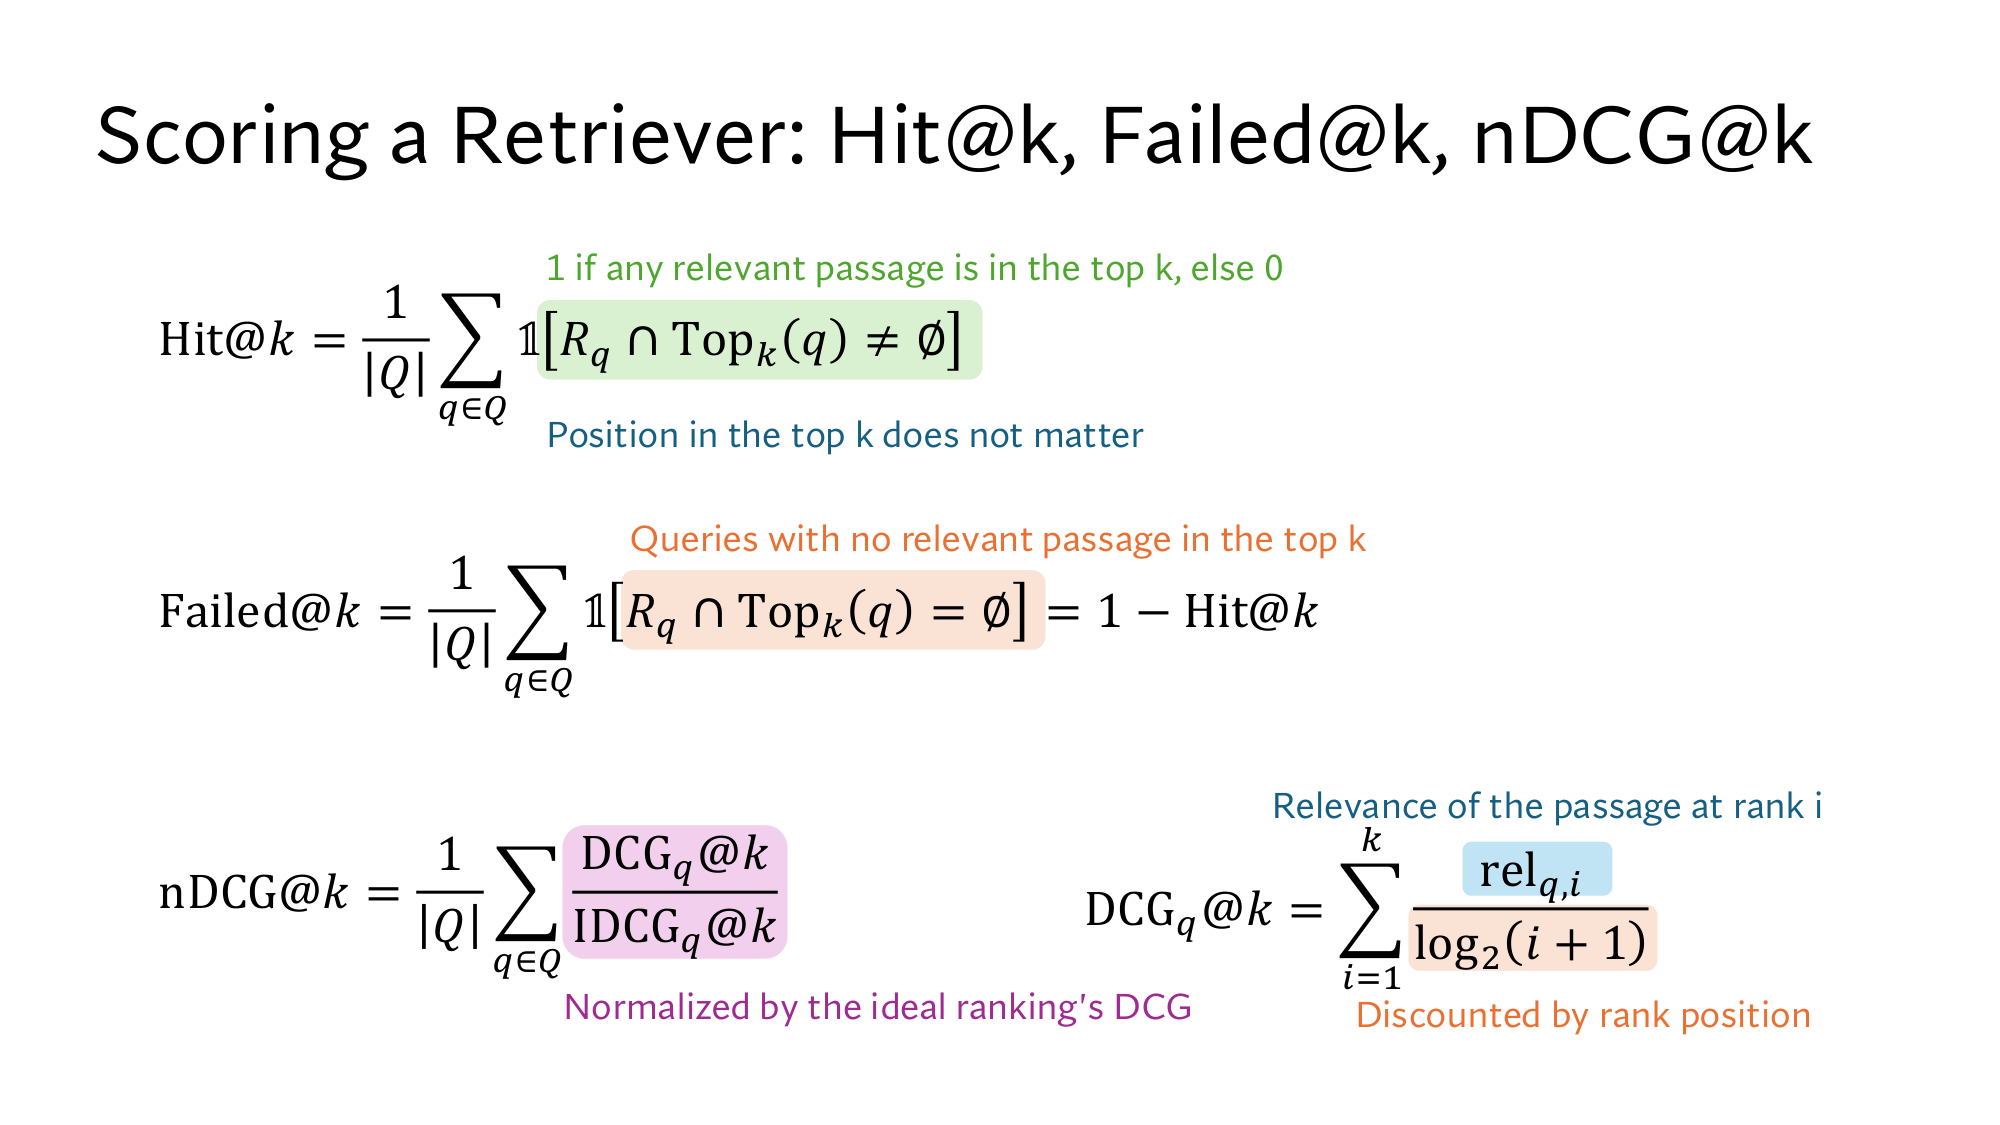
This “1 if true, 0 if false” rule has its own sign: . For example, 𝟙[2 > 1] = 1 and 𝟙[2 > 3] = 0. In Hit@k the condition is that Rq ∩ Topk(q) is not empty, written ≠ ∅, where ≠ means “not equal to”. For q3 the intersection is empty, so 𝟙[Rq3 ∩ Top3(q3) ≠ ∅] = 0. The formula holds the two steps above:
Hit@k = 1|Q|∑q ∈ Q 𝟙[Rq ∩ Topk(q) ≠ ∅]
q ∈ Q
Add over every query q in Q. ∈ means “one of the members of this set”. Here 1 + 1 + 0 = 2.
1 ÷ |Q|
Divide by the number of queries, which makes it an average. Here 2 ÷ 3 = 0.667.
Failed@k is the opposite: the share of queries where not a single right passage reached the top k. Each query scores 1 on either Hit or Failed, never both, so Failed@k = 1 − Hit@k. Here Failed@3 = 1 − 0.667 = 0.333, because 1 query out of 3, q3, failed.
Hit@3 = 0.667 is also lesson 2's here, because no more than 2 of the 3 queries can be answered from the passages. The same numbers come back later under other names. The of lesson 8 is Failed@20, because each query there had one right chunk. The of lesson 12 is Hit@20.
Now look at the improvement from the start. q2's syllabus moved from rank 2 to rank 1, but both times it is inside the top 3, so q2 gets 1 both times. Hit@k does not look at where inside the top k the right passage sits. Stanford's slide says so under Hit@k: Position in the top k does not matter.
Take k = 1 and the improvement shows: Hit@1 was 1 ÷ 3 = 0.333, and after the improvement it is 2 ÷ 3 = 0.667. But then Hit@1 cannot tell rank 2 from rank 5, because both get 0. So at any single k, Hit@k sees only one slice of the order.
3MRR@k: how high the first right passage is
The reciprocal rank is 1 divided by the rank of the first right passage, and MRR is its average over the queries. The reciprocal of a number is 1 divided by that number. If the first right passage is at rank 1, the reciprocal rank is 1 ÷ 1 = 1. At rank 2 it is 1 ÷ 2 = 0.5, and at rank 3 it is 1 ÷ 3 = 0.333. If no right passage is in the top k, it is 0.
Now look at the three queries at k = 3. q1's first right passage, the queue log, is at rank 1, so 1. q2's syllabus is at rank 2, so 0.5. q3 has no right passage in the top 3, so 0.
Add the three reciprocal ranks: 1 + 0.5 + 0 = 1.5.
Divide by 3 queries: 1.5 ÷ 3 = 0.5.
This average is called MRR, the mean reciprocal rank, and here MRR@3 = 0.5. The formula holds the same two steps:
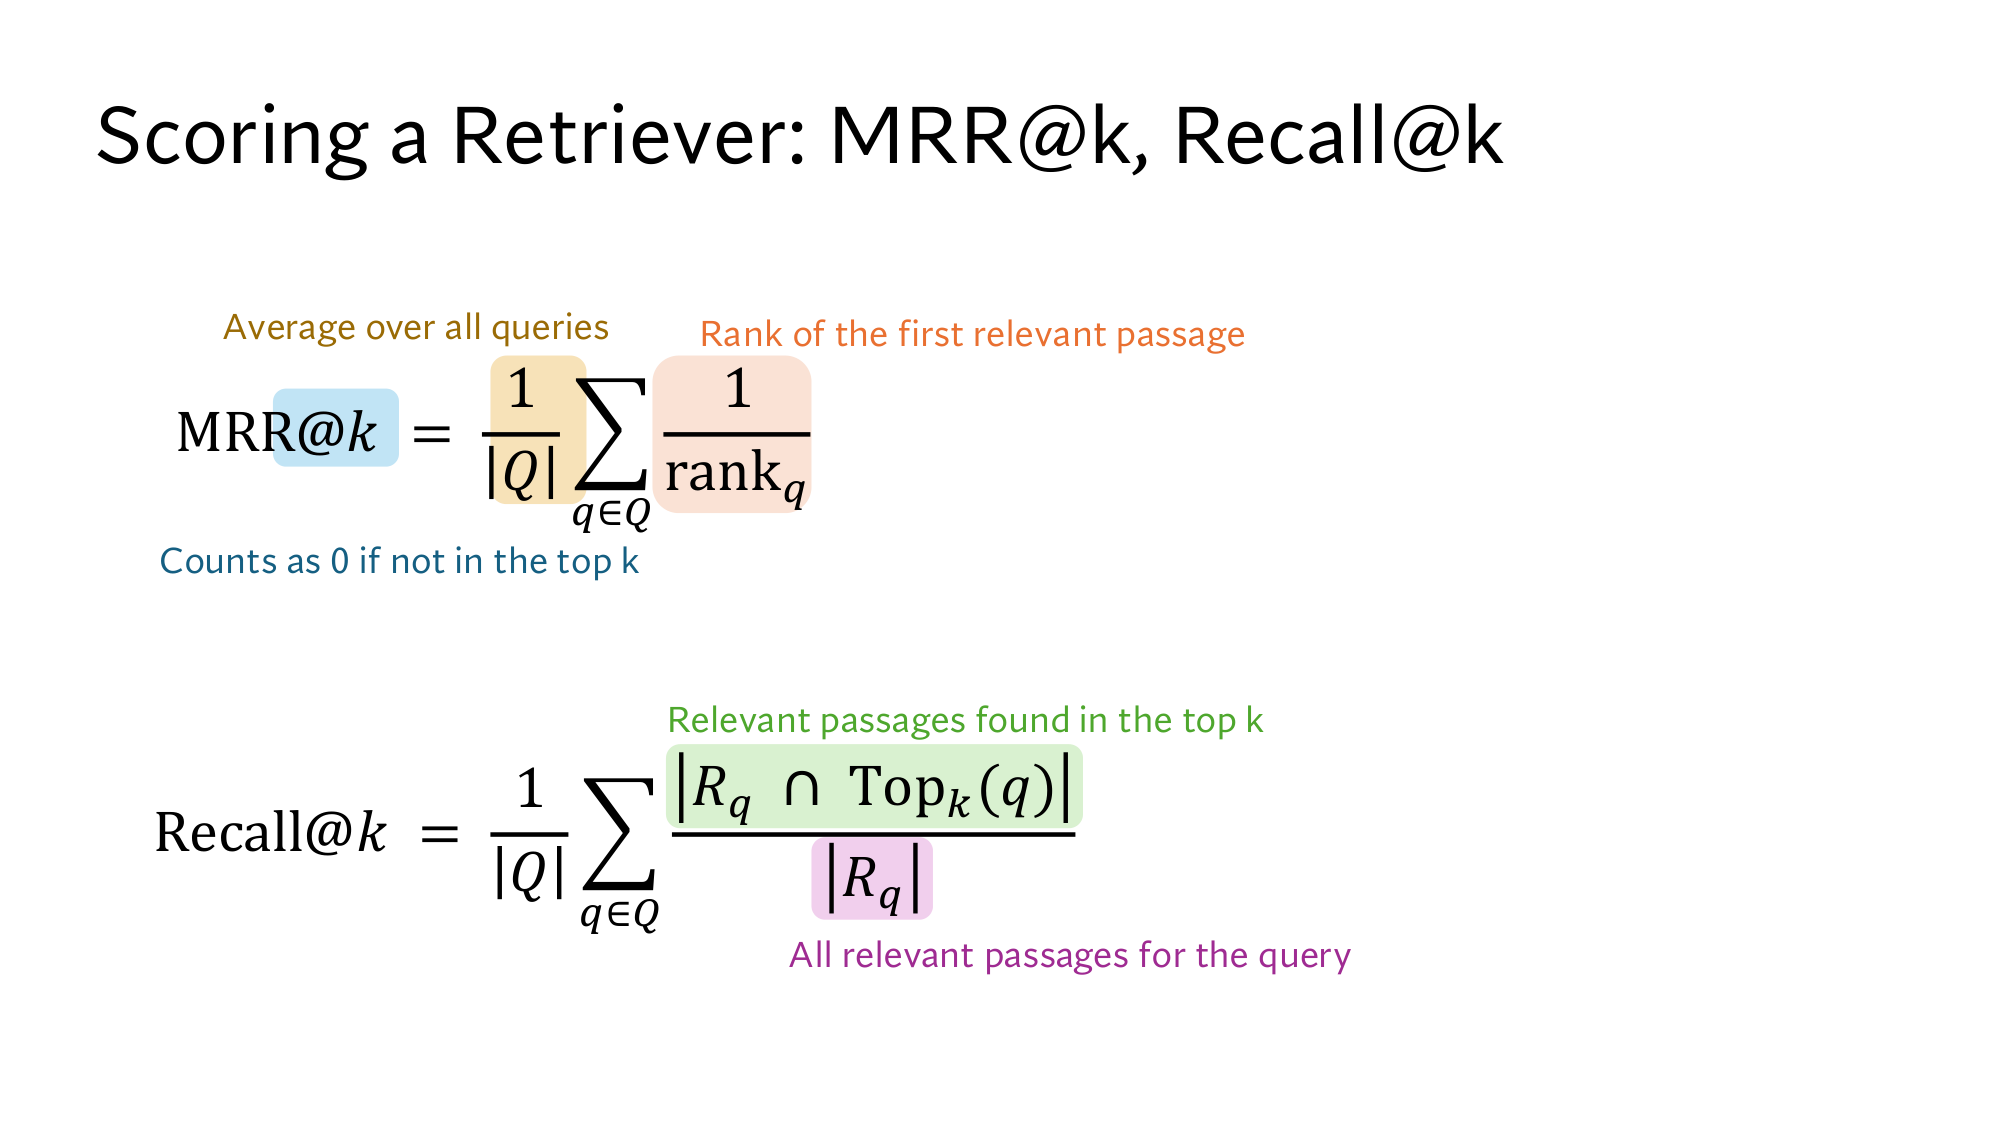
MRR@k = 1|Q|∑q ∈ Q1rankq
rankq
The rank of query q's first right passage: 1 for q1, and 2 for q2. q3 has none in the top 3, so it adds 0.
Now look at the improvement from the start. q2's syllabus moved to rank 1, so q2's reciprocal rank went from 0.5 to 1, and MRR@3 = (1 + 1 + 0) ÷ 3 = 0.667. Hit@3 did not move, but MRR@3 went from 0.5 to 0.667.my example of an improvement
MRR is most useful when one right passage is enough, as for q2, whose whole date is in the syllabus. The retrievers in lessons 14 and 15 are also compared by MRR@10.
But MRR looks only at the first right passage. Whether q1's office hours page is at rank 3 or outside the top 3, q1's reciprocal rank stays 1. Yet a full answer to q1 needs both passages: the time from the queue log, and the fact that it is on Zoom from the office hours page.
4Recall@k: how many of the right passages arrived
Recall@k counts, for each query, what share of all its right passages made the top k, and then averages over the queries. For a query like q1 one right passage is not enough, because the reader gets the time from the queue log and the place from the office hours page.
At k = 3, q1 found 2 of its 2 right passages, q2 found 1 of 1, and q3 found 0 of 1.
Each query's share: 2 ÷ 2 = 1 for q1, 1 ÷ 1 = 1 for q2, and 0 ÷ 1 = 0 for q3.
The average: (1 + 1 + 0) ÷ 3 = 0.667.
This number is called Recall@k. Lesson 2 introduced roughly, for example the right passage found for 60 of 100 questions, which is 0.6. This is its exact form.
At k = 1 Recall and Hit come apart. q1's top 1 holds only the queue log, 1 of 2, so 0.5. q2 and q3 get 0. Recall@1 = (0.5 + 0 + 0) ÷ 3 = 0.167, while Hit@1 = 0.333. Hit@1 gave q1 a full 1, and Recall@1 gave it only half, because the office hours page was missed.
Recall@k = 1|Q|∑q ∈ Q|Rq ∩ Topk(q)||Rq|
|Rq ∩ Topk(q)|
How many right passages are in the top k. At k = 1 for q1, |{queue log}| = 1.
|Rq|
How many right passages the query has in total. For q1 that is 2, so q1's share is 1 ÷ 2 = 0.5.
Recall@k has a weakness: it never goes down as k grows, because passages only join the top k and never leave it. At k = 1,000 recall will look very high, but by lesson 2's count the holds only about 14 passages. So look at Recall@k at the k you actually put into the prompt. Recall@k also ignores the order inside the top k: whether the queue log is at rank 1 or rank 3, q1's Recall@3 is the same.
The recall of search in lesson 10 compares against the list from exact search: if 9 of the exact top 10 come back, it is 0.9. Recall@k compares against relevance labels that a person wrote.
Stanford's slide: the formulas for MRR@k and Recall@k. You can now read every line of it. Click the image to open it at full size.
5nDCG@k: is the most useful passage on top?
nDCG@k reduces each grade according to its rank, adds them up, and divides the sum by the sum for the best possible order. So it looks at two things together: how useful a passage is, and how high it sits. In the three metrics so far, a passage was simply right or wrong.
Think first
Reverse q1's order: office hours page (1), old forum post (0), queue log (3). Which of Hit@3, the reciprocal rank and Recall@3 changes for q1?
Show the answer
None of them. Hit is 1, the reciprocal rank is also 1 because the office hours page is right too, and Recall is 2 of 2. But for the reader this list is worse, because the crowd data is now at rank 3.
A first attempt could be to add up the grades in the top k. But the original order gives 3 + 0 + 1 = 4, and the reversed order gives 1 + 0 + 3 = 4, so the sum sees the grades but not the order. That is why each grade is reduced according to its rank, so that a lower passage counts for less.
Dividing by log2(rank + 1)
The reduction divides each grade by (rank + 1). log2 x answers the question: to what power must you raise 2 to get x? 21 = 2, 22 = 4 and 23 = 8, so log2 2 = 1, log2 4 = 2 and log2 8 = 3. The log2 of 3 lies between 1 and 2, because 3 lies between 2 and 4: log2 3 = 1.585. Check: 21.585 = 3.000.
This is the same idea as from lesson 4, where the base was e, about 2.718, and here it is 2. The 1 is added to the rank so that rank 1 has the divisor log2 2 = 1, and the top passage keeps its full grade:
Rank
log2(rank + 1)
Share of the grade that counts
1
log2 2 = 1
1 ÷ 1 = 1
2
log2 3 = 1.585
1 ÷ 1.585 = 0.631
3
log2 4 = 2
1 ÷ 2 = 0.5
Now work out the sum for q1's original order:
Rank 1, queue log: 3 ÷ 1 = 3.
Rank 2, old forum post: 0 ÷ 1.585 = 0.
Rank 3, office hours page: 1 ÷ 2 = 0.5.
Sum: 3 + 0 + 0.5 = 3.5.
In the reversed order the office hours page is at rank 1 and the queue log at rank 3: 1 ÷ 1 + 0 + 3 ÷ 2 = 1 + 1.5 = 2.5. Now the order shows, because 3.5 and 2.5 differ. This sum is called the , the discounted cumulative gain. Gain means the grade, cumulative means added up, and discounted means reduced by rank.
Dividing by the IDCG: bringing every query between 0 and 1
One problem remains: how large the DCG can get depends on the query. q1 has two right passages, with grades 3 and 1, so its DCG can reach 3.631. q3 has one right passage, with grade 2, so its DCG can never go above 2. A plain average would give more weight to queries with more right passages.
So each query's DCG is divided by the DCG of the best possible order for that same query, called the IDCG, the ideal DCG. q1's best order is queue log (3), office hours page (1), so IDCG = 3 ÷ 1 + 1 ÷ 1.585 = 3.631. This order comes from all the labels, not from the retriever's list, which is why q3's IDCG is 2.
Now the original order gives 3.5 ÷ 3.631 = 0.964, and the reversed order gives 2.5 ÷ 3.631 = 0.689. This ratio is called nDCG, where the n stands for normalized. It always lies between 0 and 1, and 1 means no better order is possible.
Hit, the reciprocal rank and Recall missed the reversed order, but nDCG fell from 0.964 to 0.689. The formula holds the same arithmetic, followed by the average of every query's nDCG:
Here relq,i is the grade of the passage at rank i, which is 3, 0 and 1 in q1's original order. The same arithmetic works for the other two queries. q3's right passage is not in the top 3, so its DCG is 0, and its nDCG is 0 too.
Query, k = 3
DCG
IDCG
nDCG
q1queue log (3), forum post (0), office hours page (1)
3.5
3.631
0.964
q2project page (0), syllabus (3), Homework 1 (0)
?
3
?
q3syllabus (0), Homework 1 (0), project page (0)
0
2
0
Work out the second row
q2's right passage, the syllabus (grade 3), is at rank 2. What are its DCG and nDCG? Then work out nDCG@3 over all three queries.
Show the answer
DCG = 3 ÷ log2 3 = 3 ÷ 1.585 = 1.893. IDCG = 3 ÷ 1 = 3, because the best order would put the syllabus at rank 1. nDCG = 1.893 ÷ 3 = 0.631.
nDCG@3 = (0.964 + 0.631 + 0) ÷ 3 = 0.532.
Change q1's order
Press “Up” to move a passage up one rank, and change k. The right passages have a coloured border. Build the reversed order and watch nDCG drop to 0.689.
Metric (q1 only)
Value
Stanford's slide: the formulas for Hit@k, Failed@k and nDCG@k. You can now read every line of it.
One retriever, four numbers
Now put the starting retriever's four numbers side by side. The list is the same and k = 3, yet four different numbers come out:
Query
Hit@3
Reciprocal rank
Recall@3
nDCG@3
q1
1
1
1
0.964
q2
1
0.5
1
0.631
q3
0
0
0
0
Average
0.667
0.5MRR@3
0.667
0.532
Now look at the improvement from the start once more. When q2's syllabus moves to rank 1, its nDCG becomes 3 ÷ 3 = 1, and nDCG@3 = (0.964 + 1 + 0) ÷ 3 = 0.655. MRR@3 also becomes 0.667, while Hit@3 and Recall@3 stay at 0.667.
The cost of nDCG is that it needs grades, which are even more expensive than right-or-wrong labels. The late chunking scores in lesson 8 were this nDCG@10, written as percentages. Each metric answers a different question:
Metric
The question it answers
When to use it
Hit@k, Failed@k
Did the reader get at least one right passage?
To measure the recall ceiling
MRR@k
How high is the first right passage?
When one right passage is enough
Recall@k
How many of the right passages arrived?
When the answer is spread over several passages
nDCG@k
Are the more useful passages on top?
When you have grades and the order matters
Think first
A support bot puts the top 5 passages into its prompt, and most answers sit in a single passage. Retriever A has its first right passage at rank 2 for every query. Retriever B has it at rank 1 for half the queries and outside the top 5 for the other half. Work out MRR@5 and Hit@5 for both. Which one would you choose?
Show the answer
MRR@5: A = 0.5, and B = (1 + 0) ÷ 2 = 0.5, so they are equal. Hit@5: A = 1.0, and B = 0.5.
Choose A. A brings a right passage to the reader for every query, while B gives it nothing for half of them. Looking at MRR alone, you would never see this difference.
What the dense version adds
The dense version contains this whole lesson, followed by 5 more steps that take you to the level of the Stanford slides:
Step 6: the slides' symbols, and the rules of sets and 𝟙 that give Failed@k = 1 − Hit@k.
Step 7: the maths of the discount: a table of 1 ÷ rank and 1 ÷ log2(rank + 1), the harmonic series, and the ideal DCG.
Step 8: averaging over queries, percentages and points, and Stanford's nDCG@10 chart.
Step 9: these metrics in the papers: DPR's Hit@20, MS MARCO's MRR@10 and ColBERT's Recall@1000.
Step 10: Stanford's three slides, which you read yourself.
Every metric needs relevance labels: the right passages Rq for each query, and sometimes their grades.
Hit@k asks whether a right passage arrived, and MRR how high the first right passage is. Recall@k asks how many of all the right passages arrived, and nDCG whether the more useful passage is on top.
One number does not tell the whole story. Look at Hit@k or Recall@k at the k that goes into the prompt, and at MRR or nDCG for the order.
New terms in this lesson
Relevance labels
The right passages fixed in advance for each query, sometimes with grades. For example, for q1 the queue log (grade 3) and the office hours page (grade 1).
Set, ∩, ∅, |A|
A group of things, the things two sets share, the empty set, and how many things a set holds. For example, |{queue log, office hours page}| = 2, and for q3, Rq3 ∩ Top3(q3) = ∅.
𝟙[condition]
1 if the condition is true, 0 if not. For example, q3's top 3 holds no right passage, so 𝟙[Rq3 ∩ Top3(q3) ≠ ∅] = 0.
Hit@k
The share of queries with at least one right passage in the top k. For example, at k = 3, 2 of 3 queries, so 0.667.
Failed@k
1 − Hit@k, the share of queries with no right passage in the top k. For example, Failed@3 = 1 − 0.667 = 0.333.
MRR@k
1 ÷ the rank of the first right passage, averaged over the queries, with 0 if none is in the top k. For example, ranks 1, 2 and none give (1 + 0.5 + 0) ÷ 3 = 0.5.
Recall@k
Right passages found in the top k ÷ all right passages, averaged over the queries. For example, at k = 1 q1 found 1 of 2, so 0.5.
log2
The power you must raise 2 to in order to get a number. For example, log2 4 = 2, and log2 3 = 1.585.
DCG and IDCG
Each rank's grade ÷ log2(rank + 1), added up. The IDCG is the DCG of the best order. For example, q1's order queue log (3), forum post (0), office hours page (1) gives DCG 3.5 and IDCG 3.631.
nDCG@k
DCG ÷ IDCG, between 0 and 1, which looks at both grade and order. For example, q1's reversed order gives 2.5 ÷ 3.631 = 0.689.